
Bernoulli Distribution Calculator
Paste 0 and 1 outcomes, Yes and No answers, or any scores with a pass mark, and get the Bernoulli distribution probability p, the mean and variance of the Bernoulli distribution, the standard deviation, the probability mass function, four confidence intervals, an exact test and four clear plots.
Last updated 22 September 2026 · Reviewed by the StatsUnlock team
⚡ 0. Quick Answer
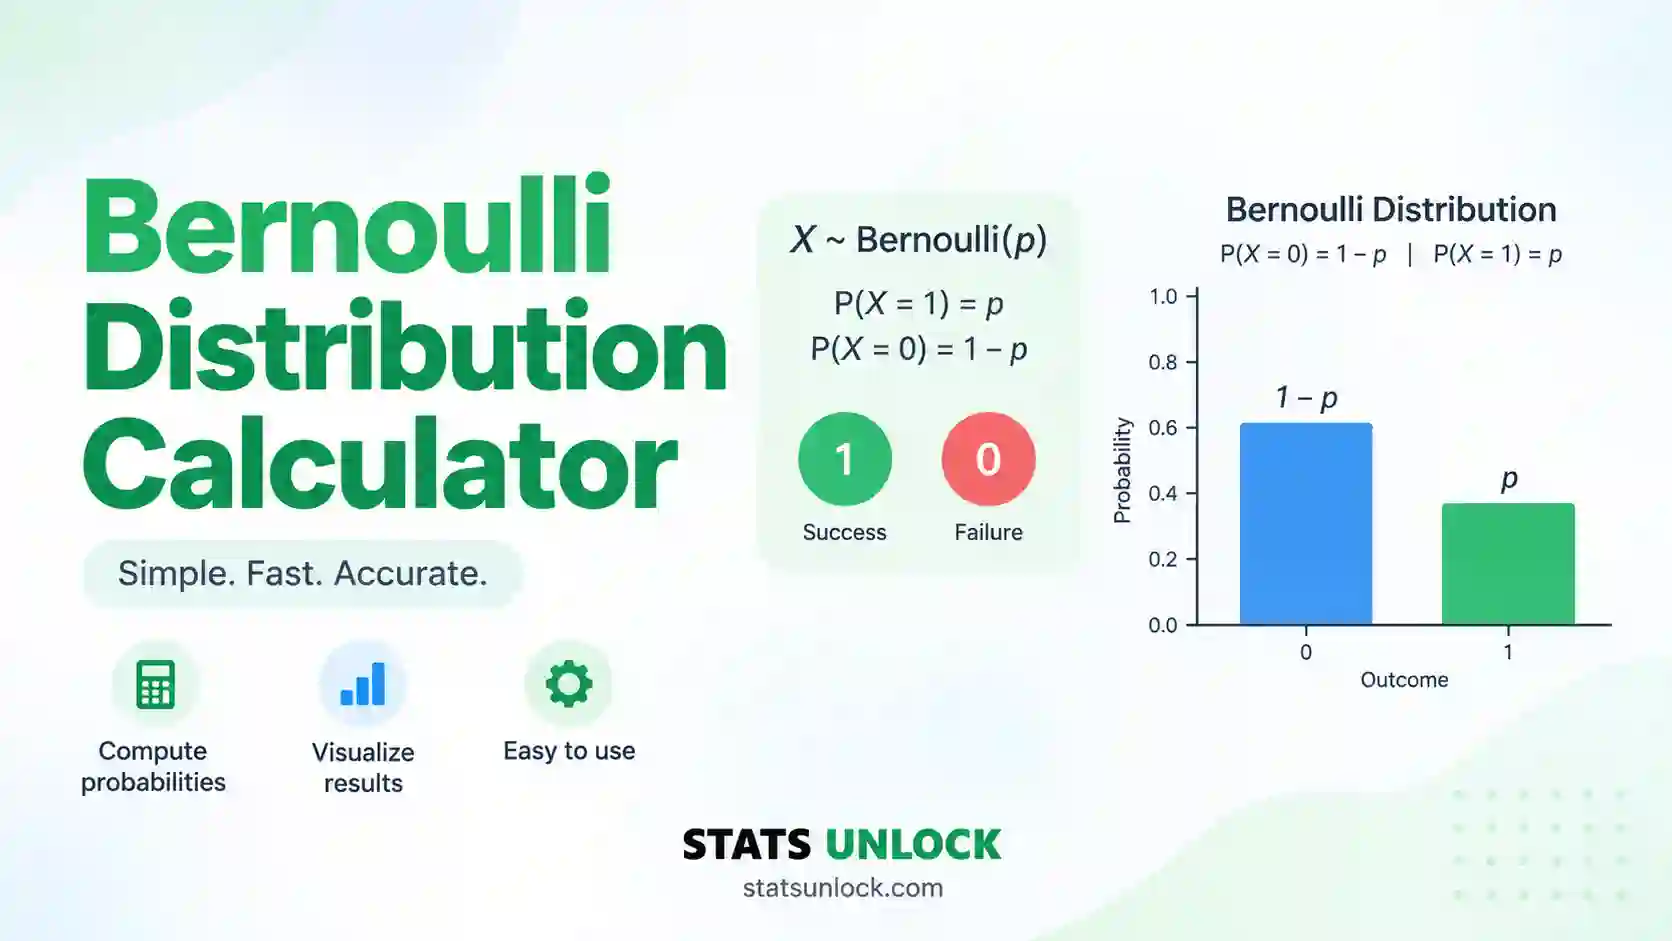
The Bernoulli distribution describes one trial with two outcomes: success (X = 1) with probability p, and failure (X = 0) with probability 1 − p.
Its mean is p and its variance is p(1 − p). For 13 successes in 20 trials, p̂ = 0.65, the variance is 0.65 × 0.35 = 0.2275 and the standard deviation is 0.4770.
Rule of thumb: the variance is largest (0.25) when p = 0.5. Report p̂ with a Wilson 95% interval, and switch to the exact test when np̂ or n(1 − p̂) is below 10.
Key takeaways
- The Bernoulli distribution models a single yes or no trial with success probability p.
- The mean is p and the variance is p(1 − p), which never exceeds 0.25.
- The best estimate of p is the sample proportion p̂ = k ÷ n, which is also the maximum likelihood estimate.
- For the worked example, 13 of 20 gives p̂ = 0.65 with a Wilson 95% CI of [0.433, 0.819].
- Adding n independent Bernoulli trials gives the binomial distribution, so every binomial result starts here.
📚 1. What Is the Bernoulli Distribution?
What is a Bernoulli distribution? It is the probability distribution of a random variable that can take only two values, 1 and 0. The value 1 is called a success and happens with probability p. The value 0 is called a failure and happens with probability 1 − p, often written q. It is named after the Swiss mathematician Jacob Bernoulli, whose book Ars Conjectandi (1713) first studied repeated trials of this kind.
What it measures: one number, p, the chance that a single trial ends in success. Everything else about a Bernoulli random variable distribution follows from p: the mean, the variance, the standard deviation, the skewness, the odds and the entropy.
A worked one-liner: a patient either responds to a drug (1) or does not (0). If 13 of 20 patients respond, p̂ = 13 ÷ 20 = 0.65, the mean is 0.65, the variance is 0.65 × 0.35 = 0.2275 and the standard deviation is √0.2275 = 0.477.
What "success" means is up to you. It does not have to be a good thing. A defective item, a disease case or a lost game can all be coded as 1. What matters is that you say which outcome is 1 and keep it the same everywhere.
Who uses it: doctors (responded or not), engineers (defective or not), marketers (clicked or not), ecologists (species present or absent), teachers (passed or failed) and data scientists (the target of logistic regression). It is the building block of the binomial, geometric and negative binomial distributions.
| Feature | Bernoulli distribution | Binomial distribution |
|---|---|---|
| Number of trials | Exactly 1 | n independent trials |
| Possible values | 0 or 1 | 0, 1, 2, …, n |
| Parameters | p | n and p |
| Mean | p | np |
| Variance | p(1 − p) | np(1 − p) |
| Notation | X ~ Bernoulli(p) or Bern(p) | Y ~ Bin(n, p) |
| Relationship | A binomial variable is the sum of n independent Bernoulli variables with the same p. Bernoulli is binomial with n = 1. | |
🧮 2. Set Up Your Data
Enter comma-separated values, one group per box. Accepted codes: 1 / 0, Yes / No, True / False, Success / Failure, Pass / Fail, Present / Absent, Heads / Tails. Spaces, tabs, semicolons and new lines also work. The group name above each box is editable.
Type one outcome per cell (1 or 0, Yes or No). Each column is a group, and you can rename it in the header. Empty cells are ignored.
📊 3. Results
🧠 4. Interpretation of Results, In Detail
4.1 What p̂ tells you
p̂ is the share of trials that ended in success. In the worked example, 13 of 20 patients responded, so p̂ = 0.65. It is your best single guess of the true Bernoulli parameter p, the probability that the next trial succeeds. It is also the maximum likelihood estimate, which means no other value of p makes the data you saw more likely. That is why chart 4 always peaks exactly at p̂.
p̂ describes the process, not one person. "p̂ = 0.65" does not mean each patient responded 65%. Each patient either responded or did not. It means that under the same conditions about 65 in every 100 patients are expected to respond.
4.2 Why the mean of a Bernoulli distribution equals p
The expected value of a Bernoulli distribution is E[X] = 0 × (1 − p) + 1 × p = p. So the mean of your 0/1 column is simply the proportion of 1s. This is useful: the Excel AVERAGE of a 0/1 column, the R mean() and the NumPy mean() all give p̂ directly. If your mean is not between 0 and 1, something other than 0 and 1 has slipped into the data.
4.3 Reading the variance and standard deviation
The variance of the Bernoulli distribution is p(1 − p). It measures how unpredictable a single trial is. It is 0 when p = 0 or p = 1, because the outcome is certain. It is largest, 0.25, when p = 0.5, because then the trial is a pure coin toss. For p̂ = 0.65 the variance is 0.2275, which is 91% of the maximum, so single outcomes are still hard to predict.
The standard deviation is √(p(1 − p)), so 0.477 in the example. Unlike a measurement SD, it is not a "typical distance" you can picture on a ruler, because every value is either 0 or 1. Treat it as an index of uncertainty that feeds into the standard error and sample-size formulas.
4.4 Population variance versus sample variance
This is the most common source of "why does my answer differ" emails. p(1 − p) = 0.2275 is the population form and matches Excel VAR.P. The sample form multiplies by n ÷ (n − 1), giving 0.2395, and matches Excel VAR.S, R var() and pandas .var(). NumPy np.var() uses the population form unless you set ddof=1. Both are correct; they answer slightly different questions. For describing a Bernoulli distribution with parameter p̂, use p̂(1 − p̂). For an unbiased estimate of the variance from a sample, use the n − 1 form. The difference shrinks as n grows.
4.5 Standard error: how precise is p̂?
The standard deviation describes one trial. The standard error, √(p̂(1 − p̂) ÷ n), describes how much p̂ itself would change from sample to sample. For 13 of 20 it is 0.107, so p̂ could easily be 0.1 higher or lower in a repeat study. Because n sits under a square root, you need four times as many trials to halve the standard error.
4.6 Which confidence interval to trust
The calculator reports four intervals. The Wald interval, p̂ ± 1.96 × SE, is the one most textbooks show, but it is known to cover the true p far less often than 95% when n is small or p is near 0 or 1 (Brown, Cai and DasGupta, 2001). It can even go below 0 or above 1. The Wilson interval fixes this and is the recommended default. Agresti-Coull is a simple approximation to Wilson. Clopper-Pearson is exact and never under-covers, but it is wider than needed. For the worked example, Wald gives [0.441, 0.859], Wilson [0.433, 0.819] and Clopper-Pearson [0.408, 0.846]. The Wilson interval is not symmetric around 0.65, and that is correct, because p cannot go above 1.
4.7 The test against p0
The exact binomial test asks: if the true p were p0, how surprising are k successes in n trials? For 13 of 20 against p0 = 0.5, p = 0.263, so a fair coin could easily produce this result. The z test gives p = 0.180. The two differ because the z test uses a normal curve to approximate a discrete distribution. With fewer than 10 expected successes or failures, trust the exact test. A non-significant result does not prove p = p0; the Wilson interval from 0.433 to 0.819 shows that many values, including 0.5, remain plausible.
4.8 Effect size: Cohen h
A p-value depends on n, so a tiny difference can be "significant" in a huge sample. Cohen h = 2 arcsin√p̂ − 2 arcsin√p0 measures the size of the gap on a scale where 0.2 is small, 0.5 medium and 0.8 large. For 0.65 against 0.5, h = 0.30, a small to medium effect. Report h beside the p-value.
4.9 Skewness, kurtosis, odds and entropy
Skewness (1 − 2p) ÷ √(pq) is negative when success is the common outcome and positive when failure is. For p = 0.65 it is −0.63. Excess kurtosis (1 − 6pq) ÷ pq is −2 at p = 0.5, the lowest value any distribution can have, and grows large for rare events. The odds p ÷ (1 − p) = 1.857 say there were about 1.86 successes per failure. The log-odds, 0.619, is the scale logistic regression uses. Entropy, 0.934 bits, says how much information one trial carries, with 1 bit as the maximum at p = 0.5.
4.10 Comparing groups
With two or more groups the calculator runs a chi-square test of homogeneity, which asks whether all groups share one p. For the drug example, treatment 13/20 against placebo 7/20 gives χ²(1, N = 40) = 3.60, p = .058, Cramér V = 0.30. That is a borderline result. If any expected count is below 5, the tool warns you to use Fisher's exact test instead.
4.11 Decision guide
| You see | What it means | What to do |
|---|---|---|
| Interval width above 0.3 | p is poorly pinned down | Collect more trials, report as preliminary |
| np̂ or n(1 − p̂) below 10 | Normal approximation is weak | Use Wilson or Clopper-Pearson and the exact test |
| p̂ = 0 or p̂ = 1 | Variance and SE are zero | Report the exact upper (or lower) limit; the rule of three gives about 3 ÷ n |
| Exact p < .05 but h < 0.2 | Real but tiny difference | Say so; statistical is not practical significance |
| Groups differ in the chi-square test | p is not the same across groups | Report each group separately, or model with logistic regression |
4.12 Common mistakes this calculator prevents
- Averaging codes like 1 and 2 as if they were 0 and 1. The validator skips anything that is not a recognised binary code and lists it.
- Reporting a Wald interval that goes below 0 or above 1. Wilson is the default here.
- Mixing VAR.P and VAR.S without saying which. Both are shown, clearly labelled.
- Treating a p-value above .05 as proof that p = p0. The interval and effect size are always shown beside it.
- Typing a zero for a missing answer. Blanks and "NA" are skipped, not counted as failures.
✍ 5. How to Write Your Results in Research
When reporting Bernoulli distribution results in APA format, give four things: the number of successes and trials (k and n), the estimated probability p̂, a confidence interval with its method named, and, if you tested a value, the test and its p-value. The five templates below fill in automatically after you run the calculator.
5.1 Example 1, APA 7th edition
📌 Key conventions for this style
- Italicise statistical symbols such as p, n and CI in the final manuscript.
- Drop the leading zero for p-values (p = .263) but keep it for proportions (p̂ = 0.65), since proportions are not bounded like p-values in APA's rule.
- Always name the interval method, for example "Wilson score interval".
- Report k and n, not only the percentage.
5.2 Example 2, thesis or dissertation
📌 Key conventions for this style
- Define what counts as a success in the Methods chapter.
- Justify the interval method and cite Brown et al. (2001) or Newcombe (1998).
- State how invalid or missing codes were handled and how many were removed.
- Name the software and version.
5.3 Example 3, plain-language summary
📌 Key conventions for this style
- Use percentages and "out of" counts, never symbols.
- Say "probably between" for the confidence interval.
- Avoid the word "significant"; say "clearly different" or "could be chance".
- Keep it to three sentences.
5.4 Example 4, structured abstract or conference poster
📌 Key conventions for this style
- Put the interval in square brackets straight after the estimate.
- Use the same decimal places throughout, usually 2 or 3.
- A PMF bar chart or forest plot of p̂ is the clearest poster figure.
- Cut every word that is not a number or a conclusion.
5.5 Example 5, replication or pre-registration
📌 Key conventions for this style
- Fix p0, α, the interval method and the sample size before data collection.
- State the smallest effect of interest as Cohen h.
- Say how you will handle missing outcomes (excluded, not coded as 0).
- Share the raw 0/1 data so others can reproduce p̂.
5.6 Tables and figures
In a table, give one row per group with columns for n, k, p̂, the 95% CI and, if relevant, the p-value. Footnote the interval method. The best figure is chart 2 on this page, a dot for p̂ with its interval, because it shows the estimate and its uncertainty at once. A PMF bar chart (chart 1) is best for teaching.
5.7 Reporting checklist
- What counts as success (1) is defined.
- k, n and p̂ are all reported.
- The CI method and level are named.
- Variance form (population or sample) is stated if variance is reported.
- The test, p0 and p-value are given, with Cohen h.
- Excluded entries are counted and explained.
∑ 6. Formulas Used
These are the Bernoulli distribution formulas the calculator uses, from the probability mass function to the confidence intervals and the test.
🔀 7. Bernoulli Distribution Calculation Flowchart, Step by Step
This flowchart shows how the Bernoulli distribution is calculated, step by step, from a raw column of outcomes to a reportable p̂, mean, variance and interval. Every box uses the same worked example as the Excel, R and Python sections: 20 patients in a drug trial, where 1 means the patient responded.
Check any box yourself: the Excel sheet in Section 9, the R script in Section 10 and the Python script in Section 11 all return p̂ = 0.65, variance 0.2275, Wilson CI [0.4329, 0.8188] and exact p = 0.2632 for this dataset.
📝 8. How to Use This Calculator
- Enter your data. Type or paste comma-separated outcomes in the box, for example 1, 0, 1, 1, 0. Yes/No, True/False, Pass/Fail and Success/Failure also work, as do new lines from an Excel column.
- Name each group. The group name above each box is editable. Type a meaningful name such as Treatment or Site A; it flows into the tables, charts and reports.
- Add more groups. Press Add group to compare up to eight groups side by side. Each group has its own Clear and Remove buttons.
- Or upload a CSV or Excel file. On the Upload tab choose a file, then click every column that should become a group. Selected columns turn green and are loaded as separate groups.
- Choose how values are coded. Keep Binary for 0/1 data. Choose Numeric scores to turn values like 52, 48, 55 into success or failure with a cut-off such as a pass mark of 50.
- Set the test value p0. Enter the probability you want to test against, such as 0.5 for a fair coin or a published rate.
- Pick the confidence level and interval method. 95% and Wilson are the recommended defaults. Clopper-Pearson, Agresti-Coull and Wald are also available.
- Press Calculate Bernoulli Distribution. Nothing is computed until you press the button. Changing any input clears old results so you never read stale numbers.
- Read the results and four charts. Check p̂, the mean, the variance, the interval and the exact test, then the PMF, interval, variance-curve and likelihood charts.
- Copy a report and export. Section 5 fills five reporting styles you can copy. Download Doc saves a text report and Download PDF prints a clean report with the charts.
📈 9. How to Calculate the Bernoulli Distribution in Excel
Excel has no function called BERNOULLI, but you do not need one. A Bernoulli distribution in Excel is just a column of 0s and 1s: AVERAGE gives p̂, VAR.P gives p(1 − p), and BINOM.DIST with one trial gives the Bernoulli PMF and CDF. This section builds the full analysis for the 20-patient worked example, with the spreadsheet shown at each step.
=AVERAGE(A2:A21) is p̂ and the mean, and =VAR.P(A2:A21) is the Bernoulli variance p(1 − p).9.1 The functions you need
| You want | Excel formula | Worked result |
|---|---|---|
| Trials n | =COUNT(A2:A21) | 20 |
| Successes k | =SUM(A2:A21) or =COUNTIF(A2:A21,1) | 13 |
| p̂ and mean E[X] | =AVERAGE(A2:A21) | 0.65 |
| Bernoulli variance p(1 − p) | =VAR.P(A2:A21) | 0.2275 |
| Sample variance | =VAR.S(A2:A21) | 0.2395 |
| Standard deviation | =STDEV.P(A2:A21) | 0.4770 |
| Standard error of p̂ | =SQRT(D4*(1-D4)/D2) | 0.1067 |
| PMF, P(X = 1) | =BINOM.DIST(1,1,D4,FALSE) | 0.65 |
| CDF, P(X ≤ 0) | =BINOM.DIST(0,1,D4,TRUE) | 0.35 |
| Exact CI lower / upper | =BETA.INV(0.025,13,8) / =BETA.INV(0.975,14,7) | 0.4078 / 0.8461 |
| Random Bernoulli value | =IF(RAND()<0.65,1,0) | 1 or 0 |
9.2 Step by step
1 Put the outcomes in one column as 0 and 1
Type a header in A1 and the 20 outcomes in A2:A21. If your sheet has "Yes" and "No", convert them in column B with =IF(A2="Yes",1,0) and work from column B.
=IF(A2="Yes",1,0)The first six responses of the 20-patient example. Cell A2 holds 1, a responder.
2 Count n and k, then take the average
The average of a 0/1 column is the proportion of 1s, so it is p̂ and the Bernoulli mean at the same time.
=COUNT(A2:A21)=SUM(A2:A21)=AVERAGE(A2:A21)n = 20, k = 13, p̂ = 0.65.
3 Add the variance, SD and standard error
Use VAR.P for the Bernoulli variance p(1 − p). VAR.S gives the sample version, which is larger by n ÷ (n − 1).
=VAR.P(A2:A21)=VAR.S(A2:A21)=SQRT(D4*(1-D4)/D2)Variance 0.2275, sample variance 0.2395, SD 0.4770, SE 0.1067.
4 Build the Wilson and exact confidence intervals
Put z = 1.96 in D5. The Wilson limits need one long formula each; the exact Clopper-Pearson limits use BETA.INV.
=(D4+D5^2/(2*D2)-D5*SQRT(D4*(1-D4)/D2+D5^2/(4*D2^2)))/(1+D5^2/D2)=BETA.INV(0.025,D3,D2-D3+1)Wilson 95% CI [0.4329, 0.8188]; exact CI [0.4078, 0.8461]. For the upper Wilson limit change the minus before D5*SQRT to a plus.
5 Test against p0 and get the PMF
Excel has no two-sided exact binomial test. When p0 = 0.5 the distribution is symmetric, so double the upper tail. For other p0 values use the calculator above, R or Python.
=2*(1-BINOM.DIST(D3-1,D2,0.5,TRUE))=BINOM.DIST(1,1,D4,FALSE)Exact p = 0.2632, and the Bernoulli PMF gives P(X = 1) = 0.65 and P(X = 0) = 0.35.
=2*BINOM.DIST(D3,D2,0.5,TRUE) instead.9.3 The awkward cases
- Text codes.
AVERAGEignores text, so a column of "Yes" and "No" returns #DIV/0!. Convert with=--(A2="Yes"). - Blanks.
AVERAGEskips blanks but treats a typed 0 as a failure. Never type 0 for a missing answer. - Several groups. Use
=AVERAGEIF(B2:B41,"Placebo",A2:A41)to get p̂ per group. - Simulating Bernoulli trials.
=IF(RAND()
9.4 Why the answers differ across software
| Quantity | Excel | R | Python | This calculator |
|---|---|---|---|---|
| Variance | VAR.P = 0.2275, VAR.S = 0.2395 | var() = 0.2395 (n − 1) | np.var() = 0.2275, ddof=1 gives 0.2395 | Both, labelled |
| 95% CI | No built-in, build it by hand | prop.test Wilson (set correct=FALSE), binom.test exact | binomtest().proportion_ci(), default exact | Wilson default, all four shown |
| Test vs p0 | Doubling trick at p0 = 0.5 only | binom.test exact = 0.2632 | binomtest exact = 0.2632 | Exact 0.2632 and z 0.1797 |
R's prop.test applies a continuity correction by default, which widens the Wilson interval from [0.433, 0.819] to [0.409, 0.837]. Always set correct = FALSE if you want the plain Wilson interval that matches this page.
9.5 Charting the Bernoulli PMF in Excel
Type "0" and "1" in F2:F3 and =BINOM.DIST(F2,1,$D$4,FALSE) in G2:G3. Select F1:G3 and choose Insert, Column Chart. Set the vertical axis maximum to 1 so readers see the probabilities on their true scale. This is the Bernoulli distribution histogram most textbooks show.
9.6 Error messages
| Error | Cause | Fix |
|---|---|---|
| #DIV/0! | The column contains only text or blanks | Convert Yes/No to 1/0 first |
| #NUM! from BETA.INV | k = 0 or k = n, so one shape parameter is 0 | Set the exact lower limit to 0 when k = 0 and the upper to 1 when k = n |
| Mean above 1 | A code like 2 or 9 (missing) is in the data | Filter the column; only 0 and 1 are allowed |
| #VALUE! | Numbers stored as text | Use Data, Text to Columns, or multiply by 1 |
📈 10. How to Calculate the Bernoulli Distribution in R
R treats the Bernoulli distribution in R as a binomial with size = 1, so dbinom(x, 1, p) is the PMF, pbinom(x, 1, p) the CDF and rbinom(n, 1, p) simulates Bernoulli trials. The script below is complete and runs top to bottom. It prints p̂, the mean, the variance, three confidence intervals, an exact test with a plain-English verdict, and saves one 300 dpi figure. It uses base R only.
x <- c(...) line, or read a CSV with the commented line.10.1 The complete script
R, base only, saves bernoulli_plot.png
# ============================================================
# Bernoulli distribution: p-hat, mean, variance, CIs, exact test
# StatsUnlock - https://statsunlock.com/bernoulli-distribution-calculator/
# Base R only. No packages to install.
# ============================================================

# ---- 1. Your data (1 = success, 0 = failure) ---------------
# Replace with your own values, or read a CSV:
#   x <- read.csv("data.csv")$response
#   x <- x[!is.na(x)]                      # drop missing values
x <- c(1, 1, 0, 1, 1, 0, 1, 1, 1, 0,
       1, 0, 1, 1, 0, 1, 0, 1, 1, 0)
label <- "Treatment"
p0    <- 0.5                                # value to test against

stopifnot(all(x %in% c(0, 1)))              # only 0 and 1 allowed

# ---- 2. Bernoulli summary ----------------------------------
n     <- length(x)
k     <- sum(x)
p_hat <- mean(x)                            # mean of 0/1 = proportion
var_p <- p_hat * (1 - p_hat)                # Bernoulli variance, VAR.P
var_s <- var(x)                             # sample variance, n - 1
sd_p  <- sqrt(var_p)
se    <- sqrt(var_p / n)

# ---- 3. Confidence intervals and test ----------------------
wilson <- prop.test(k, n, correct = FALSE)$conf.int   # Wilson score
exact  <- binom.test(k, n, p = p0)                    # Clopper-Pearson + exact p
wald   <- p_hat + c(-1, 1) * qnorm(0.975) * se
h      <- 2 * asin(sqrt(p_hat)) - 2 * asin(sqrt(p0))  # Cohen h

cat(sprintf("n = %d, k = %d, p-hat = %.4f\n", n, k, p_hat))
cat(sprintf("mean = %.4f  variance p(1-p) = %.4f  sample var = %.4f\n",
            p_hat, var_p, var_s))
cat(sprintf("SD = %.4f  SE = %.4f\n", sd_p, se))
cat(sprintf("Wald 95%% CI   [%.4f, %.4f]\n", wald[1], wald[2]))
cat(sprintf("Wilson 95%% CI [%.4f, %.4f]\n", wilson[1], wilson[2]))
cat(sprintf("Exact 95%% CI  [%.4f, %.4f]\n", exact$conf.int[1], exact$conf.int[2]))
cat(sprintf("Exact binomial test vs p0 = %.2f: p = %.4f, Cohen h = %.2f\n",
            p0, exact$p.value, h))
cat(if (exact$p.value < 0.05) "Verdict: p differs from p0.\n" else
    "Verdict: the data are consistent with p0.\n")
cat(sprintf("P(X = 1) = %.4f, P(X = 0) = %.4f\n",
            dbinom(1, 1, p_hat), dbinom(0, 1, p_hat)))

# ---- 4. One figure, two panels, 300 dpi --------------------
png("bernoulli_plot.png", width = 3000, height = 1350, res = 300)
par(mfrow = c(1, 2), mar = c(4.5, 4.5, 3, 1), family = "sans")

bp <- barplot(c(1 - p_hat, p_hat), names.arg = c("X = 0", "X = 1"),
              col = c("#fdba74", "#93c5fd"), border = c("#ea580c", "#2563eb"),
              ylim = c(0, 1), ylab = "P(X = x)",
              main = paste0("Bernoulli PMF, ", label))
text(bp, c(1 - p_hat, p_hat) + 0.05, sprintf("%.3f", c(1 - p_hat, p_hat)))

pp <- seq(0.001, 0.999, length.out = 400)
rl <- exp(k * log(pp) + (n - k) * log(1 - pp) -
          (k * log(p_hat) + (n - k) * log(1 - p_hat)))
plot(pp, rl, type = "l", lwd = 2.5, col = "#9333ea", las = 1,
     xlab = "p", ylab = "L(p) / L(p-hat)", main = "Likelihood function")
rect(wilson[1], 0, wilson[2], 1.05, col = adjustcolor("#2563eb", 0.10), border = NA)
abline(v = p_hat, lty = 2, lwd = 2, col = "#2563eb")
abline(v = p0, lty = 3, lwd = 2, col = "#dc2626")
legend("topleft", bty = "n", cex = 0.8,
       legend = c("p-hat", "p0", "Wilson 95% CI"),
       col = c("#2563eb", "#dc2626", adjustcolor("#2563eb", 0.3)),
       lty = c(2, 3, NA), pch = c(NA, NA, 15), pt.cex = 2)
dev.off()
cat("Saved bernoulli_plot.png\n")
Output: n = 20, k = 13, p-hat = 0.6500, variance 0.2275, sample var 0.2395, Wilson [0.4329, 0.8188], exact [0.4078, 0.8461], exact p = 0.2632.
10.2 What each line does
| Line or function | What it does, and why it is there |
|---|---|
| stopifnot(all(x %in% c(0, 1))) | Stops the script if any value is not 0 or 1, so a stray 2 or 9 cannot silently raise the mean. |
| mean(x) | The mean of a 0/1 vector is the proportion of 1s, which is p̂. |
| p_hat * (1 - p_hat) | The Bernoulli variance. R has no var.p(), so compute it directly. |
| var(x) | Sample variance with n − 1. It is always larger than p̂(1 − p̂) by n ÷ (n − 1). |
| prop.test(..., correct = FALSE) | Returns the Wilson score interval. Leave correct at its default and you get a continuity-corrected version instead. |
| binom.test(k, n, p = p0) | Exact two-sided test and the Clopper-Pearson interval in one call. |
| dbinom(1, 1, p_hat) | Bernoulli PMF, because Bernoulli is binomial with size 1. |
| png(..., res = 300) | Opens a 300 dpi file for print quality. dev.off() closes it. |
| exp(k*log(pp) + ...) | The likelihood curve scaled so its peak is 1, which sits exactly at p̂. |
10.3 What the figure shows
The left panel is the Bernoulli PMF: two bars at 0.35 and 0.65. The right panel is the likelihood function. Its peak is at p̂ = 0.65 (dashed blue line), the shaded band is the Wilson 95% interval, and the dotted red line marks p0 = 0.5. Because p0 falls inside the band, the test is not significant.
10.4 Common R problems and fixes
| Symptom | Cause | Fix |
|---|---|---|
No dbern() function | Base R has no separate Bernoulli functions | Use dbinom(x, 1, p), or extraDistr::dbern() |
mean(x) is NA | Missing values in x | x <- x[!is.na(x)] before anything else |
| Wilson CI differs from this page | prop.test uses a continuity correction by default | Add correct = FALSE |
| Factor "Yes"/"No" gives an error | mean() of a factor is not defined | x <- as.integer(df$ans == "Yes") |
| Empty PNG | dev.off() not reached | Run the script to the end |
10.5 Useful one-liners
| You want | R code |
|---|---|
| Simulate 100 Bernoulli trials | rbinom(100, size = 1, prob = 0.3) |
| Bernoulli PMF table | dbinom(0:1, 1, 0.3) |
| Bernoulli CDF | pbinom(0:1, 1, 0.3) |
| p̂ per group | tapply(df$y, df$group, mean) |
| Logistic regression on a Bernoulli outcome | glm(y ~ x, family = binomial, data = df) |
| Compare two groups | prop.test(c(13, 7), c(20, 20), correct = FALSE) |
📈 11. How to Calculate the Bernoulli Distribution in Python
For the Bernoulli distribution in Python, SciPy has a ready object, scipy.stats.bernoulli, with .pmf(), .cdf(), .mean(), .var() and .rvs(). NumPy simulates Bernoulli trials with rng.binomial(1, p, size). The script below matches the R script to four decimal places.
Install with pip install numpy scipy matplotlib. The proportion_ci method needs SciPy 1.7 or newer.
11.1 The complete script
Python 3, saves bernoulli_plot.png
# ============================================================
# Bernoulli distribution: p-hat, mean, variance, CIs, exact test
# StatsUnlock - https://statsunlock.com/bernoulli-distribution-calculator/
# ============================================================
import numpy as np
import matplotlib
matplotlib.use("Agg")                       # save without opening a window
import matplotlib.pyplot as plt
from scipy import stats

# ---- 1. Your data (1 = success, 0 = failure) ---------------
# Or read a CSV:
#   import pandas as pd
#   x = pd.read_csv("data.csv")["response"].dropna().to_numpy()
x = np.array([1, 1, 0, 1, 1, 0, 1, 1, 1, 0,
              1, 0, 1, 1, 0, 1, 0, 1, 1, 0])
label = "Treatment"
p0 = 0.5                                    # value to test against

assert set(np.unique(x)) <= {0, 1}, "only 0 and 1 allowed"

# ---- 2. Bernoulli summary ----------------------------------
n = x.size
k = int(x.sum())
p_hat = x.mean()                            # mean of 0/1 = proportion
var_p = p_hat * (1 - p_hat)                 # Bernoulli variance
var_s = x.var(ddof=1)                       # sample variance, n - 1
sd_p = np.sqrt(var_p)
se = np.sqrt(var_p / n)

dist = stats.bernoulli(p_hat)               # frozen Bernoulli(p-hat)
assert np.isclose(dist.mean(), p_hat) and np.isclose(dist.var(), var_p)

# ---- 3. Confidence intervals and test ----------------------
res = stats.binomtest(k, n, p=p0)           # exact two-sided test
wilson = res.proportion_ci(confidence_level=0.95, method="wilson")
exact = res.proportion_ci(confidence_level=0.95, method="exact")
z = stats.norm.ppf(0.975)
wald = (p_hat - z * se, p_hat + z * se)
h = 2 * np.arcsin(np.sqrt(p_hat)) - 2 * np.arcsin(np.sqrt(p0))

print(f"n = {n}, k = {k}, p-hat = {p_hat:.4f}")
print(f"mean = {dist.mean():.4f}  variance p(1-p) = {var_p:.4f}  sample var = {var_s:.4f}")
print(f"SD = {sd_p:.4f}  SE = {se:.4f}")
print(f"Wald 95% CI   [{wald[0]:.4f}, {wald[1]:.4f}]")
print(f"Wilson 95% CI [{wilson.low:.4f}, {wilson.high:.4f}]")
print(f"Exact 95% CI  [{exact.low:.4f}, {exact.high:.4f}]")
print(f"Exact binomial test vs p0 = {p0:.2f}: p = {res.pvalue:.4f}, Cohen h = {h:.2f}")
print("Verdict: p differs from p0." if res.pvalue < 0.05
      else "Verdict: the data are consistent with p0.")
print(f"P(X = 1) = {dist.pmf(1):.4f}, P(X = 0) = {dist.pmf(0):.4f}")

# ---- 4. One figure, two panels, 300 dpi --------------------
fig, (ax1, ax2) = plt.subplots(1, 2, figsize=(10, 4.5))
bars = ax1.bar(["X = 0", "X = 1"], [dist.pmf(0), dist.pmf(1)],
               color=["#fdba74", "#93c5fd"], edgecolor=["#ea580c", "#2563eb"])
ax1.bar_label(bars, fmt="%.3f")
ax1.set_ylim(0, 1)
ax1.set_ylabel("P(X = x)")
ax1.set_title(f"Bernoulli PMF, {label}")

pp = np.linspace(0.001, 0.999, 400)
loglik = k * np.log(pp) + (n - k) * np.log(1 - pp)
ax2.plot(pp, np.exp(loglik - loglik.max()), color="#9333ea", lw=2.5)
ax2.axvspan(wilson.low, wilson.high, color="#2563eb", alpha=0.10, label="Wilson 95% CI")
ax2.axvline(p_hat, color="#2563eb", ls="--", lw=2, label="p-hat")
ax2.axvline(p0, color="#dc2626", ls=":", lw=2, label="p0")
ax2.set_xlabel("p")
ax2.set_ylabel("L(p) / L(p-hat)")
ax2.set_title("Likelihood function")
ax2.legend(frameon=False, fontsize=8, loc="upper left")

fig.tight_layout()
fig.savefig("bernoulli_plot.png", dpi=300)
print("Saved bernoulli_plot.png")
Output: identical to R, p-hat 0.6500, variance 0.2275, Wilson [0.4329, 0.8188], exact [0.4078, 0.8461], p = 0.2632.
11.2 What each line does
| Line or function | What it does, and why it is there |
|---|---|
| x.mean() | Proportion of 1s, which is p̂ and the Bernoulli mean. |
| x.var(ddof=1) | Sample variance. Without ddof=1 NumPy returns p̂(1 − p̂). |
| stats.bernoulli(p_hat) | A frozen Bernoulli distribution; .pmf(1), .cdf(0), .var() and .moment(r) all work. |
| stats.binomtest(k, n, p=p0) | Exact two-sided binomial test; same p-value as R binom.test. |
| proportion_ci(method="wilson") | Wilson interval. "exact" gives Clopper-Pearson, the default. |
| matplotlib.use("Agg") | Saves the figure without needing a screen, so it runs on servers too. |
| fig.savefig(..., dpi=300) | Print-quality output. |
11.3 What the figure shows
The same two panels as the R figure: the Bernoulli distribution plot of the PMF on the left and the likelihood function with the Wilson band on the right.
11.4 Common Python problems and fixes
| Symptom | Cause | Fix |
|---|---|---|
| Variance differs from R | NumPy default ddof=0 | Use ddof=1 for the sample form |
AttributeError: proportion_ci | SciPy older than 1.7 | pip install -U scipy |
binom_test is deprecated | Renamed in SciPy 1.10 | Use stats.binomtest |
| Strings "Yes"/"No" | Not numeric | (df["ans"] == "Yes").astype(int) |
11.5 Useful one-liners
| You want | Python code |
|---|---|
| Simulate Bernoulli trials with NumPy | np.random.default_rng(42).binomial(1, 0.3, size=100) |
| Bernoulli PMF and CDF | stats.bernoulli.pmf([0, 1], 0.3), stats.bernoulli.cdf([0, 1], 0.3) |
| Mean, variance, skew, kurtosis | stats.bernoulli.stats(0.3, moments="mvsk") |
| p̂ per group | df.groupby("group")["y"].mean() |
| Log-likelihood | stats.bernoulli.logpmf(x, p_hat).sum() |
📋 12. Reference Tables
12.1 Bernoulli distribution table: mean, variance and shape by p
| p | q = 1 − p | Mean E[X] | Variance pq | SD | Skewness | Entropy (bits) |
|---|---|---|---|---|---|---|
| 0.01 | 0.99 | 0.01 | 0.0099 | 0.0995 | 9.849 | 0.081 |
| 0.05 | 0.95 | 0.05 | 0.0475 | 0.2179 | 4.129 | 0.286 |
| 0.10 | 0.90 | 0.10 | 0.0900 | 0.3000 | 2.667 | 0.469 |
| 0.20 | 0.80 | 0.20 | 0.1600 | 0.4000 | 1.500 | 0.722 |
| 0.25 | 0.75 | 0.25 | 0.1875 | 0.4330 | 1.155 | 0.811 |
| 0.30 | 0.70 | 0.30 | 0.2100 | 0.4583 | 0.873 | 0.881 |
| 0.40 | 0.60 | 0.40 | 0.2400 | 0.4899 | 0.408 | 0.971 |
| 0.50 | 0.50 | 0.50 | 0.2500 | 0.5000 | 0.000 | 1.000 |
| 0.60 | 0.40 | 0.60 | 0.2400 | 0.4899 | -0.408 | 0.971 |
| 0.70 | 0.30 | 0.70 | 0.2100 | 0.4583 | -0.873 | 0.881 |
| 0.75 | 0.25 | 0.75 | 0.1875 | 0.4330 | -1.155 | 0.811 |
| 0.80 | 0.20 | 0.80 | 0.1600 | 0.4000 | -1.500 | 0.722 |
| 0.90 | 0.10 | 0.90 | 0.0900 | 0.3000 | -2.667 | 0.469 |
| 0.95 | 0.05 | 0.95 | 0.0475 | 0.2179 | -4.129 | 0.286 |
| 0.99 | 0.01 | 0.99 | 0.0099 | 0.0995 | -9.849 | 0.081 |
Conclusion: the variance is symmetric around p = 0.5, where it peaks at 0.25; p = 0.2 and p = 0.8 have the same variance, 0.16, but skew in opposite directions.
12.2 Bernoulli PMF and CDF values
| p | P(X = 0) | P(X = 1) | F(0) = P(X ≤ 0) | F(1) |
|---|---|---|---|---|
| 0.10 | 0.90 | 0.10 | 0.90 | 1.00 |
| 0.25 | 0.75 | 0.25 | 0.75 | 1.00 |
| 0.50 | 0.50 | 0.50 | 0.50 | 1.00 |
| 0.75 | 0.25 | 0.75 | 0.25 | 1.00 |
| 0.90 | 0.10 | 0.90 | 0.10 | 1.00 |
Conclusion: the CDF at 0 always equals 1 − p, and at 1 it is always 1.
12.3 Critical z values for confidence intervals
| Confidence level | z | α (two-sided) |
|---|---|---|
| 80% | 1.282 | 0.20 |
| 90% | 1.645 | 0.10 |
| 95% | 1.960 | 0.05 |
| 98% | 2.326 | 0.02 |
| 99% | 2.576 | 0.01 |
| 99.9% | 3.291 | 0.001 |
Conclusion: moving from 95% to 99% confidence widens every interval by about 31% (2.576 ÷ 1.960).
12.4 Trials needed for a given margin of error (95%)
| Expected p | ±0.10 | ±0.05 | ±0.03 | ±0.02 | ±0.01 |
|---|---|---|---|---|---|
| 0.1 | 35 | 139 | 385 | 865 | 3458 |
| 0.2 | 62 | 246 | 683 | 1537 | 6147 |
| 0.3 | 81 | 323 | 897 | 2017 | 8068 |
| 0.4 | 93 | 369 | 1025 | 2305 | 9220 |
| 0.5 | 97 | 385 | 1068 | 2401 | 9604 |
Conclusion: n = z²p(1 − p) ÷ E². If you do not know p, plan for p = 0.5, the worst case; values for p = 0.6 to 0.9 match those for 0.4 to 0.1.
12.5 Upper 95% limit when you see zero successes
| Trials n | Exact upper limit | Wilson upper limit | Rule of three, 3 ÷ n |
|---|---|---|---|
| 10 | 0.3085 | 0.2775 | 0.3000 |
| 20 | 0.1684 | 0.1611 | 0.1500 |
| 30 | 0.1157 | 0.1135 | 0.1000 |
| 50 | 0.0711 | 0.0713 | 0.0600 |
| 100 | 0.0362 | 0.0370 | 0.0300 |
| 200 | 0.0183 | 0.0188 | 0.0150 |
| 500 | 0.0074 | 0.0076 | 0.0060 |
| 1000 | 0.0037 | 0.0038 | 0.0030 |
Conclusion: zero events does not mean p = 0. With 0 of 100, p could still be as high as about 3.6%.
12.6 Effect size bands for Cohen h
| |h| | Label | Example |
|---|---|---|
| < 0.20 | Negligible | 0.52 vs 0.50, h = 0.04 |
| 0.20 to 0.49 | Small | 0.65 vs 0.50, h = 0.30 |
| 0.50 to 0.79 | Medium | 0.75 vs 0.50, h = 0.52 |
| ≥ 0.80 | Large | 0.90 vs 0.50, h = 0.93 |
Conclusion: always pair the p-value with h; a large sample can make a negligible h significant.
12.7 The Bernoulli family: Bernoulli, binomial, geometric and Poisson
| Distribution | Counts | Mean | Variance |
|---|---|---|---|
| Bernoulli(p) | Success in one trial (0 or 1) | p | p(1 − p) |
| Binomial(n, p) | Successes in n trials | np | np(1 − p) |
| Geometric(p) | Trials until the first success | 1 ÷ p | (1 − p) ÷ p² |
| Negative binomial(r, p) | Trials until the r-th success | r ÷ p | r(1 − p) ÷ p² |
| Poisson(λ) | Limit of binomial, large n, small p, λ = np | λ | λ |
Conclusion: every row is built from independent Bernoulli trials, which is why the Bernoulli assumptions matter for all of them.
📈 13. Example Results
Eight worked Bernoulli distribution example problems and answers, from a textbook die to a production line. Each shows the numbers, a figure, what the result means and how to write it.
Rolling a six on a fair die
The classic Bernoulli trial with a known p = 1/6.
A student rolls a die 60 times and records 1 for a six and 0 for anything else. Is the die fair?
| Statistic | Value | Note |
|---|---|---|
| Trials n | 60 | Valid 0/1 outcomes |
| Successes k | 10 | Count of 1s |
| p̂ = mean | 0.1667 | k ÷ n |
| Variance p(1 − p) | 0.1389 | Maximum 0.25 |
| Standard deviation | 0.3727 | √(p(1 − p)) |
| Standard error | 0.0481 | √(p̂q̂ ÷ n) |
| Wald 95% CI | [0.0724, 0.2610] | Textbook, unreliable at small np |
| Wilson 95% CI | [0.0931, 0.2803] | Recommended |
| Exact 95% CI | [0.0829, 0.2852] | Clopper-Pearson |
| Exact test vs p0 | p = 1.0000 | p0 = 0.1667 |
| Cohen h | 0.000 | 0.2 small, 0.5 medium, 0.8 large |
What it means: p̂ = 0.167 is exactly 1/6, the value a fair die should give. The exact test returns p = 1.000, so there is no evidence the die is biased. Notice the Wilson interval, [0.093, 0.280], is still wide: 60 rolls cannot tell a fair die from one with p = 0.10 or 0.28.
How to write it: "Sixes occurred in 10 of 60 rolls, p̂ = 0.167, 95% CI [0.093, 0.280], consistent with a fair die (exact binomial p = 1.000)."
Pass rate in a flipped classroom
A large gap from p0 with a moderate sample.
24 of 30 students passed after a flipped-classroom course. The historical pass rate is 50%.
| Statistic | Value | Note |
|---|---|---|
| Trials n | 30 | Valid 0/1 outcomes |
| Successes k | 24 | Count of 1s |
| p̂ = mean | 0.8000 | k ÷ n |
| Variance p(1 − p) | 0.1600 | Maximum 0.25 |
| Standard deviation | 0.4000 | √(p(1 − p)) |
| Standard error | 0.0730 | √(p̂q̂ ÷ n) |
| Wald 95% CI | [0.6569, 0.9431] | Textbook, unreliable at small np |
| Wilson 95% CI | [0.6269, 0.9049] | Recommended |
| Exact 95% CI | [0.6143, 0.9229] | Clopper-Pearson |
| Exact test vs p0 | p = 0.0014 | p0 = 0.5 |
| Cohen h | 0.644 | 0.2 small, 0.5 medium, 0.8 large |
What it means: p̂ = 0.80 is far above 0.5. The exact test gives p = .001 and Cohen h = 0.64, a medium to large effect. The whole Wilson interval, [0.627, 0.905], lies above 0.5, which tells the same story without a p-value.
How to write it: "The pass rate was 80.0% (24/30), 95% CI [0.627, 0.905], higher than the historical 50% (exact binomial p = .001, h = 0.64)."
Drug response, treatment arm
The worked example used across this page.
13 of 20 patients responded to a new drug. The question is whether the response rate beats a coin toss.
| Statistic | Value | Note |
|---|---|---|
| Trials n | 20 | Valid 0/1 outcomes |
| Successes k | 13 | Count of 1s |
| p̂ = mean | 0.6500 | k ÷ n |
| Variance p(1 − p) | 0.2275 | Maximum 0.25 |
| Standard deviation | 0.4770 | √(p(1 − p)) |
| Standard error | 0.1067 | √(p̂q̂ ÷ n) |
| Wald 95% CI | [0.4410, 0.8590] | Textbook, unreliable at small np |
| Wilson 95% CI | [0.4329, 0.8188] | Recommended |
| Exact 95% CI | [0.4078, 0.8461] | Clopper-Pearson |
| Exact test vs p0 | p = 0.2632 | p0 = 0.5 |
| Cohen h | 0.305 | 0.2 small, 0.5 medium, 0.8 large |
What it means: p̂ = 0.65 looks well above 0.5, but with n = 20 the exact test gives p = .263. The Wilson interval, [0.433, 0.819], includes 0.5. The honest summary is a promising but uncertain response rate; a larger trial is needed.
How to write it: "Thirteen of 20 patients responded (p̂ = 0.65, 95% CI [0.433, 0.819]); this did not differ significantly from 0.5 (exact binomial p = .263)."
Is the coin fair?
A result that sits right on p0.
A coin was tossed 50 times and landed heads 26 times.
| Statistic | Value | Note |
|---|---|---|
| Trials n | 50 | Valid 0/1 outcomes |
| Successes k | 26 | Count of 1s |
| p̂ = mean | 0.5200 | k ÷ n |
| Variance p(1 − p) | 0.2496 | Maximum 0.25 |
| Standard deviation | 0.4996 | √(p(1 − p)) |
| Standard error | 0.0707 | √(p̂q̂ ÷ n) |
| Wald 95% CI | [0.3815, 0.6585] | Textbook, unreliable at small np |
| Wilson 95% CI | [0.3851, 0.6520] | Recommended |
| Exact 95% CI | [0.3742, 0.6634] | Clopper-Pearson |
| Exact test vs p0 | p = 0.8877 | p0 = 0.5 |
| Cohen h | 0.040 | 0.2 small, 0.5 medium, 0.8 large |
What it means: p̂ = 0.52 is almost exactly 0.5 and the exact test gives p = .888. The variance, 0.2496, is essentially the Bernoulli maximum of 0.25, because a fair coin is the most unpredictable Bernoulli trial there is.
How to write it: "Heads occurred in 26 of 50 tosses (p̂ = 0.52, 95% CI [0.385, 0.652]), consistent with a fair coin (p = .888)."
Free throws, one player
Why 12 trials say little.
A player made 9 of 12 free throws in one game. Is this player better than a 50% shooter?
| Statistic | Value | Note |
|---|---|---|
| Trials n | 12 | Valid 0/1 outcomes |
| Successes k | 9 | Count of 1s |
| p̂ = mean | 0.7500 | k ÷ n |
| Variance p(1 − p) | 0.1875 | Maximum 0.25 |
| Standard deviation | 0.4330 | √(p(1 − p)) |
| Standard error | 0.1250 | √(p̂q̂ ÷ n) |
| Wald 95% CI | [0.5050, 0.9950] | Textbook, unreliable at small np |
| Wilson 95% CI | [0.4677, 0.9111] | Recommended |
| Exact 95% CI | [0.4281, 0.9451] | Clopper-Pearson |
| Exact test vs p0 | p = 0.1460 | p0 = 0.5 |
| Cohen h | 0.524 | 0.2 small, 0.5 medium, 0.8 large |
What it means: p̂ = 0.75 sounds impressive, but the Wilson interval runs from 0.468 to 0.911, and the Wald interval would claim an upper limit of 0.995, close to 1. The exact test gives p = .146. With 12 trials, only a very large effect could reach significance.
How to write it: "The player made 9 of 12 free throws (p̂ = 0.75, 95% Wilson CI [0.468, 0.911]); with n = 12 this was not significantly above 0.5 (p = .146)."
Newborn sex ratio in a large registry
Huge n makes a tiny gap significant.
A birth registry records 5,210 boys among 10,000 births. Is the sex ratio different from 50:50?
| Statistic | Value | Note |
|---|---|---|
| Trials n | 10,000 | Valid 0/1 outcomes |
| Successes k | 5,210 | Count of 1s |
| p̂ = mean | 0.5210 | k ÷ n |
| Variance p(1 − p) | 0.2496 | Maximum 0.25 |
| Standard deviation | 0.4996 | √(p(1 − p)) |
| Standard error | 0.0050 | √(p̂q̂ ÷ n) |
| Wald 95% CI | [0.5112, 0.5308] | Textbook, unreliable at small np |
| Wilson 95% CI | [0.5112, 0.5308] | Recommended |
| Exact 95% CI | [0.5112, 0.5308] | Clopper-Pearson |
| Exact test vs p0 | p < 0.0001 | p0 = 0.5 |
| Cohen h | 0.042 | 0.2 small, 0.5 medium, 0.8 large |
What it means: The exact test gives p = < .001, very small. But p̂ = 0.521 is only 2.1 percentage points from 0.5 and Cohen h = 0.042 is far below the 0.2 threshold for a small effect. The result is real but tiny. In fact it matches the well-known natural ratio of about 105 boys per 100 girls.
How to write it: "Of 10,000 births, 52.1% were male (95% CI [0.511, 0.531]), a statistically significant but small departure from 0.5 (p = < .001, h = 0.042)."
Rare defects on a production line
Where the Wald interval breaks.
Quality control found 3 defective items among 80. The target defect rate is 1%.
| Statistic | Value | Note |
|---|---|---|
| Trials n | 80 | Valid 0/1 outcomes |
| Successes k | 3 | Count of 1s |
| p̂ = mean | 0.0375 | k ÷ n |
| Variance p(1 − p) | 0.0361 | Maximum 0.25 |
| Standard deviation | 0.1900 | √(p(1 − p)) |
| Standard error | 0.0212 | √(p̂q̂ ÷ n) |
| Wald 95% CI | [-0.0041, 0.0791] | Textbook, unreliable at small np |
| Wilson 95% CI | [0.0128, 0.1045] | Recommended |
| Exact 95% CI | [0.0078, 0.1057] | Clopper-Pearson |
| Exact test vs p0 | p = 0.0466 | p0 = 0.01 |
| Cohen h | 0.189 | 0.2 small, 0.5 medium, 0.8 large |
What it means: p̂ = 0.0375 and np̂ = 3, far below 10. The Wald interval is [-0.0041, 0.0791], and its lower limit is below zero, which is impossible for a probability. The Wilson interval, [0.0128, 0.1045], stays inside 0 to 1. The exact test against 1% gives p = .047, so the defect rate is probably above target.
How to write it: "Three of 80 items were defective (p̂ = 0.0375, 95% Wilson CI [0.0128, 0.1045]); the exact binomial test indicated a rate above the 1% target (p = .047)."
Seed germination against a certified rate
Checking a supplier's claim.
A seed packet claims 85% germination. In a test, 32 of 40 seeds germinated.
| Statistic | Value | Note |
|---|---|---|
| Trials n | 40 | Valid 0/1 outcomes |
| Successes k | 32 | Count of 1s |
| p̂ = mean | 0.8000 | k ÷ n |
| Variance p(1 − p) | 0.1600 | Maximum 0.25 |
| Standard deviation | 0.4000 | √(p(1 − p)) |
| Standard error | 0.0632 | √(p̂q̂ ÷ n) |
| Wald 95% CI | [0.6760, 0.9240] | Textbook, unreliable at small np |
| Wilson 95% CI | [0.6524, 0.8950] | Recommended |
| Exact 95% CI | [0.6435, 0.9095] | Clopper-Pearson |
| Exact test vs p0 | p = 0.3742 | p0 = 0.85 |
| Cohen h | -0.132 | 0.2 small, 0.5 medium, 0.8 large |
What it means: p̂ = 0.80 is a little below the claimed 0.85, but the exact test gives p = .374 and the Wilson interval [0.652, 0.895] contains 0.85. The data do not contradict the supplier. To detect a 5-point shortfall you would need several hundred seeds.
How to write it: "Germination was 80.0% (32/40, 95% CI [0.652, 0.895]), not significantly different from the certified 85% (exact binomial p = .374)."
🧪 14. Data Collection Protocol
Design statement: a Bernoulli analysis needs a set of independent trials, each ending in one of two clearly defined outcomes, collected under the same conditions so that p is constant.
- Write down, before you collect data, exactly what counts as a success (1) and a failure (0).
- Decide what happens to unclear outcomes: exclude them and record why, never guess.
- Plan the sample size with Table 12.4 for the margin of error you need.
- Make each trial independent: one row per unit, no repeated measures on the same person unless you model them.
- Keep conditions constant: same protocol, same equipment, same time window.
- Randomise the order of trials if a learning or fatigue effect is possible.
- Record the outcome as 1 or 0 at the time it happens, not reconstructed later.
- Store missing outcomes as blank or NA, never as 0.
- Record a group column if you plan to compare groups.
- Double-enter or spot-check at least 10% of records.
| unit_id | group | outcome | date |
|---|---|---|---|
| P01 | Treatment | 1 | 2026-03-02 |
| P02 | Treatment | 1 | 2026-03-02 |
| P03 | Placebo | 0 | 2026-03-03 |
Minimum sample: at least 10 successes and 10 failures for normal-approximation methods; below that, use Wilson or exact methods, which this tool does by default.
Pre-registration line: "The outcome is binary, analysed as Bernoulli(p); p̂ is reported with a 95% Wilson interval and tested against p0 with an exact binomial test."
Common mistakes: coding missing as 0, counting the same person twice, changing the definition of success mid-study, and pooling groups with different p.
🎯 15. When to Use the Bernoulli Distribution
This free Bernoulli distribution tool is designed for anyone who needs to describe a yes or no outcome: students learning probability, researchers summarising a binary endpoint, and analysts reporting a rate.
- Each observation has exactly two outcomes
- You want p, the mean and the variance of the outcome
- You need a confidence interval for a proportion
- You want to test p against a known value
- You compare success rates across a few groups
- The outcome has three or more categories (use a multinomial or chi-square goodness-of-fit)
- You count events per unit of time (use Poisson)
- Trials are clustered or repeated on the same people (use a mixed logistic model)
- p changes with predictors you want to model (use logistic regression)
Four examples: a clinical response rate, a website conversion rate, a species presence or absence survey, and a manufacturing defect rate.
Decision tree: two outcomes, one trial per unit? Use Bernoulli. Want the count of successes in n trials? Use the binomial. Two groups with small counts? Use Fisher's exact test. Predictors? Use logistic regression. Counts with no upper limit? Use Poisson.
🔧 16. Troubleshooting and Common Errors
Some entries were skipped
Cause: values such as 2, NA, "?" or misspelt words. Fix: correct them in your data, or leave them out on purpose; the message lists exactly which were skipped.
My mean is not between 0 and 1 in Excel
Cause: a code other than 0 or 1, such as 9 for missing. Fix: filter the column and replace invalid codes with blanks.
The Wald interval goes below 0 or above 1
Cause: the normal approximation fails when np̂ or n(1 − p̂) is small. Fix: use the Wilson interval, the default here.
My variance differs from R or Python
Cause: population versus sample form. Fix: compare p(1 − p) with np.var(x) and the sample variance with var(x) or np.var(x, ddof=1).
My Wilson interval differs from R's prop.test
Cause: prop.test adds a continuity correction by default. Fix: add correct = FALSE.
The z test and exact test disagree
Cause: the z test approximates a discrete distribution with a normal curve. Fix: report the exact test when counts are small; they converge for large n.
All my values are 1 (or all 0)
Cause: p̂ is at the boundary, so variance and SE are 0. Fix: report the exact one-sided limit from Table 12.5, not a zero-width interval.
My Yes/No column loads as all skipped
Cause: the coding option is set to Numeric scores. Fix: switch "How are your values coded?" back to Binary.
The chi-square test shows a warning about expected counts
Cause: at least one expected count is below 5. Fix: use Fisher's exact test for two groups, or combine small groups.
Charts do not appear
Cause: the chart library was blocked by an ad blocker or firewall. Fix: allow cdnjs.cloudflare.com; all numbers still work without the charts.
⚖ 17. Assumptions and Limitations
17.1 Bernoulli distribution assumptions
- Two outcomes only. Check: every value is 0 or 1. If broken: invalid codes distort p̂; the direction depends on how they are coded.
- Constant p. Check: plot outcomes over time, or compare early and late trials. If broken: p̂ is an average of different rates and the SE is too small, so intervals are too narrow.
- Independent trials. Check: one row per independent unit. If broken (clustering), the SE is underestimated and p-values are too small, giving false positives.
- Correct definition of success. Check: the protocol. If broken, the result answers a different question.
17.2 Limitations
- A single p cannot explain why outcomes differ; use logistic regression for predictors.
- Clustered data (patients in hospitals, seeds in trays) need a mixed-effects or beta-binomial model.
- The chi-square homogeneity test assumes expected counts of 5 or more; use Fisher's exact test otherwise.
- Very rare events need large n; consider a Poisson model or exact methods.
- Results describe the sampled population only; generalising needs a random or representative sample.
🏁 18. Conclusion
Run the analysis above to see a conclusion written for your data. Until then, here is the general one.
The Bernoulli distribution is the simplest and most widely used model in statistics: one trial, two outcomes, one parameter p. Its mean is p, its variance is p(1 − p), and the best estimate of p is the sample proportion k ÷ n.
Good practice is simple. Define success clearly, keep missing values out of the zeros, report k, n and p̂ together, use a Wilson or exact interval rather than the Wald interval, and test against p0 with the exact binomial test. Add Cohen h so readers can judge whether a difference matters.
Because the binomial, geometric, Poisson and logistic regression models are all built from Bernoulli trials, getting the Bernoulli distribution right is the foundation for everything that follows.
❓ 19. Frequently Asked Questions
Q1. What is a Bernoulli distribution?
A Bernoulli distribution is the probability distribution of a single trial with exactly two outcomes: success (X = 1) with probability p and failure (X = 0) with probability 1 − p. It is the simplest discrete distribution and the building block of the binomial distribution.
Q2. What is the Bernoulli distribution formula?
The Bernoulli distribution formula, its probability mass function, is P(X = x) = px(1 − p)1 − x for x = 0 or 1. So P(X = 1) = p and P(X = 0) = 1 − p.
Q3. What is the mean of a Bernoulli distribution?
The mean, or expected value, of a Bernoulli distribution is E[X] = p, because E[X] = 0 × (1 − p) + 1 × p. For 13 successes in 20 trials the estimated mean is 0.65.
Q4. What is the variance of a Bernoulli distribution?
The variance of a Bernoulli distribution is p(1 − p), often written pq. It is largest, 0.25, when p = 0.5 and falls to 0 as p approaches 0 or 1. For p = 0.65 it is 0.2275.
Q5. How do you find the variance of a Bernoulli distribution?
Use Var(X) = E[X²] − (E[X])². Because X is 0 or 1, X² = X, so E[X²] = p. Therefore Var(X) = p − p² = p(1 − p). With data, replace p by the sample proportion p̂.
Q6. What is the standard deviation of a Bernoulli distribution?
The standard deviation is √(p(1 − p)). For p = 0.5 it is 0.5, its maximum; for p = 0.65 it is 0.477.
Q7. What is the difference between the Bernoulli and binomial distribution?
A Bernoulli distribution describes one trial; a binomial distribution counts the successes in n independent Bernoulli trials with the same p. Bernoulli is binomial with n = 1. The binomial mean is np and its variance np(1 − p).
Q8. What are the assumptions of the Bernoulli distribution?
Each trial has exactly two outcomes, the probability of success p is the same for every trial, and, when you analyse several trials together, the trials are independent of each other.
Q9. What is the maximum likelihood estimate for a Bernoulli distribution?
The maximum likelihood estimate is p̂ = k ÷ n, the sample proportion of successes. It comes from maximising the likelihood L(p) = pk(1 − p)n − k, whose log has derivative zero at k ÷ n.
Q10. What is the moment generating function of a Bernoulli distribution?
The moment generating function is M(t) = 1 − p + pet. Its first derivative at t = 0 is p, the mean, and every raw moment E[Xr] equals p.
Q11. What is the CDF of a Bernoulli distribution?
The cumulative distribution function is F(x) = 0 for x < 0, F(x) = 1 − p for 0 ≤ x < 1, and F(x) = 1 for x ≥ 1. It is a step function with jumps at 0 and 1.
Q12. Does a Bernoulli distribution have a probability density function?
No. The Bernoulli distribution is discrete, so it has a probability mass function, not a density. When people say Bernoulli PDF they usually mean the PMF, P(X = x) = px(1 − p)1 − x.
Q13. How is the Bernoulli distribution used in logistic regression?
Logistic regression assumes each outcome Yi is Bernoulli with its own probability pi, and models the log-odds ln(pi ÷ (1 − pi)) as a linear function of predictors. Fitting it maximises the Bernoulli likelihood.
Q14. How do you calculate the Bernoulli distribution in Excel?
Put 0/1 values in A2:A21. =AVERAGE(A2:A21) gives p and the mean, =VAR.P(A2:A21) gives p(1 − p), and =BINOM.DIST(1,1,p,FALSE) gives the Bernoulli PMF. Section 9 shows every step.
Q15. How do you use the Bernoulli distribution in R?
R uses the binomial functions with size = 1: dbinom(x, 1, p) for the PMF, pbinom(x, 1, p) for the CDF and rbinom(n, 1, p) to simulate. binom.test() gives the exact test and interval.
Q16. How do you use the Bernoulli distribution in Python?
Use scipy.stats.bernoulli(p) for the PMF, CDF, mean and variance, scipy.stats.binomtest for the exact test and intervals, and numpy.random.default_rng().binomial(1, p, size) to simulate trials.
Q17. Which confidence interval should I use for a Bernoulli proportion?
Use the Wilson score interval by default. The Wald interval, p̂ ± 1.96 SE, under-covers badly when n is small or p is near 0 or 1. Clopper-Pearson is exact but conservative.
Q18. What is the relationship between the Bernoulli, binomial, geometric and Poisson distributions?
All come from Bernoulli trials. The binomial counts successes in n trials, the geometric counts trials until the first success, and the Poisson is the limit of the binomial when n is large and p is small with np held fixed.
Q19. What is a Bernoulli-Gaussian distribution?
A Bernoulli-Gaussian variable is the product of a Bernoulli variable and a normal variable: it is 0 with probability 1 − p and drawn from a normal distribution with probability p. It is used in signal processing for sparse spikes.
Q20. Can I use this calculator for my thesis or published research?
Yes for exploratory work, teaching and checking hand calculations. For a formal paper, reproduce the numbers in R, Python, SPSS or Stata with the scripts in Sections 10 and 11 and cite that software. You can also cite this tool using Section 20.
📑 20. Cite This Tool
StatsUnlock. (2026). Bernoulli distribution calculator [Interactive statistical tool]. https://statsunlock.com/bernoulli-distribution-calculator/@misc{statsunlock_bernoulli_2026, title={Bernoulli Distribution Calculator}, author={{StatsUnlock}}, year={2026}, note={Interactive statistical tool}, url={https://statsunlock.com/bernoulli-distribution-calculator/}}Binary outcomes were modelled as Bernoulli trials and analysed with the StatsUnlock Bernoulli Distribution Calculator (2026). The success probability was estimated as the sample proportion with 95% Wilson score confidence intervals, and H0: p = p0 was tested with a two-sided exact binomial test.🔗 21. Related Tools
Probabilities for the number of successes in n Bernoulli trials.
Open the tool →Confidence intervals and tests for a single proportion.
Open the tool →Test whether a success rate differs from a target value.
Open the tool →Compare the success rates of two Bernoulli groups.
Open the tool →Compare two groups when success counts are small.
Open the tool →Test whether success rates differ across several groups.
Open the tool →Build intervals for means and proportions.
Open the tool →Plan how many trials you need for a precise estimate of p.
Open the tool →Population and sample variance for any dataset.
Open the tool →📖 22. Glossary of Terms
| Term | Plain-English meaning |
|---|---|
| Bernoulli trial | One experiment with only two possible outcomes, success or failure. |
| Binomial distribution | The number of successes in n independent Bernoulli trials with the same p. |
| CDF | Cumulative distribution function: the probability that X is less than or equal to a value. |
| Clopper-Pearson interval | An exact confidence interval for p built from the binomial distribution; never too narrow. |
| Cohen h | An effect size for the gap between two proportions, on an arcsine scale. |
| Confidence interval | A range of values of p that are compatible with the data at a chosen level, such as 95%. |
| Entropy | How uncertain one trial is, in bits; 1 bit for a fair coin, 0 for a certain outcome. |
| Exact binomial test | A test of p = p0 that uses binomial probabilities directly instead of a normal approximation. |
| Expected value | The long-run average of a random variable; for a Bernoulli variable, p. |
| Independence | The outcome of one trial tells you nothing about another trial. |
| Likelihood function | How probable the observed data are for each possible value of p. |
| Logit | The log of the odds, ln(p ÷ (1 − p)); the scale of logistic regression. |
| Maximum likelihood estimate | The value of p that makes the observed data most probable; here p̂ = k ÷ n. |
| Moment generating function | A function whose derivatives give the moments; for Bernoulli, 1 − p + pet. |
| Odds | Probability of success divided by probability of failure. |
| p (parameter) | The true probability of success in one trial. |
| p̂ (p-hat) | The estimate of p from data: successes divided by trials. |
| p0 | The value of p stated by the null hypothesis. |
| PMF | Probability mass function: the probability of each exact value of a discrete variable. |
| Standard error | How much p̂ would vary from sample to sample. |
| Variance | The average squared distance from the mean; for Bernoulli, p(1 − p). |
| Wald interval | The textbook interval p̂ ± z × SE; unreliable for small n or extreme p. |
| Wilson interval | A score-based interval for p that keeps close to its stated coverage; the recommended default. |
📚 23. References
The following peer-reviewed references support the methods used in this Bernoulli distribution calculator, covering interval estimation for a proportion, maximum likelihood, exact tests, effect sizes and reporting.
- Agresti, A., & Coull, B. A. (1998). Approximate is better than "exact" for interval estimation of binomial proportions. The American Statistician, 52(2), 119–126. https://doi.org/10.1080/00031305.1998.10480550
- Agresti, A., & Caffo, B. (2000). Simple and effective confidence intervals for proportions and differences of proportions result from adding two successes and two failures. The American Statistician, 54(4), 280–288. https://doi.org/10.1080/00031305.2000.10474560
- Blaker, H. (2000). Confidence curves and improved exact confidence intervals for discrete distributions. Canadian Journal of Statistics, 28(4), 783–798. https://doi.org/10.2307/3315916
- Bland, J. M., & Altman, D. G. (2000). The odds ratio. BMJ, 320(7247), 1468. https://doi.org/10.1136/bmj.320.7247.1468
- Brown, L. D., Cai, T. T., & DasGupta, A. (2001). Interval estimation for a binomial proportion. Statistical Science, 16(2), 101–133. https://doi.org/10.1214/ss/1009213286
- Campbell, I. (2007). Chi-squared and Fisher-Irwin tests of two-by-two tables with small sample recommendations. Statistics in Medicine, 26(19), 3661–3675. https://doi.org/10.1002/sim.2832
- Clopper, C. J., & Pearson, E. S. (1934). The use of confidence or fiducial limits illustrated in the case of the binomial. Biometrika, 26(4), 404–413. https://doi.org/10.1093/biomet/26.4.404
- Cumming, G. (2014). The new statistics: Why and how. Psychological Science, 25(1), 7–29. https://doi.org/10.1177/0956797613504966
- Fagerland, M. W., Lydersen, S., & Laake, P. (2015). Recommended confidence intervals for two independent binomial proportions. Statistical Methods in Medical Research, 24(2), 224–254. https://doi.org/10.1177/0962280211415469
- Fisher, R. A. (1922). On the mathematical foundations of theoretical statistics. Philosophical Transactions of the Royal Society A, 222, 309–368. https://doi.org/10.1098/rsta.1922.0009
- Nelder, J. A., & Wedderburn, R. W. M. (1972). Generalized linear models. Journal of the Royal Statistical Society: Series A, 135(3), 370–384. https://doi.org/10.2307/2344614
- Newcombe, R. G. (1998). Two-sided confidence intervals for the single proportion: Comparison of seven methods. Statistics in Medicine, 17(8), 857–872. https://doi.org/10.1002/(SICI)1097-0258(19980430)17:8<857::AID-SIM777>3.0.CO;2-E
- Pearson, K. (1900). On the criterion that a given system of deviations from the probable in the case of a correlated system of variables is such that it can be reasonably supposed to have arisen from random sampling. The London, Edinburgh, and Dublin Philosophical Magazine and Journal of Science, 50(302), 157–175. https://doi.org/10.1080/14786440009463897
- Peng, C.-Y. J., Lee, K. L., & Ingersoll, G. M. (2002). An introduction to logistic regression analysis and reporting. The Journal of Educational Research, 96(1), 3–14. https://doi.org/10.1080/00220670209598786
- Shannon, C. E. (1948). A mathematical theory of communication. Bell System Technical Journal, 27(3), 379–423. https://doi.org/10.1002/j.1538-7305.1948.tb01338.x
- Stigler, S. M. (2007). The epic story of maximum likelihood. Statistical Science, 22(4), 598–620. https://doi.org/10.1214/07-STS249
- Virtanen, P., Gommers, R., Oliphant, T. E., et al. (2020). SciPy 1.0: Fundamental algorithms for scientific computing in Python. Nature Methods, 17, 261–272. https://doi.org/10.1038/s41592-019-0686-2
- Vollset, S. E. (1993). Confidence intervals for a binomial proportion. Statistics in Medicine, 12(9), 809–824. https://doi.org/10.1002/sim.4780120902
- Wasserstein, R. L., & Lazar, N. A. (2016). The ASA statement on p-values: Context, process, and purpose. The American Statistician, 70(2), 129–133. https://doi.org/10.1080/00031305.2016.1154108
- Wilson, E. B. (1927). Probable inference, the law of succession, and statistical inference. Journal of the American Statistical Association, 22(158), 209–212. https://doi.org/10.1080/01621459.1927.10502953