
Berger-Parker Dominance Index Calculator
Free online tool to compute the Berger-Parker dominance index (d) for ecology and biodiversity research, instant calculation, four colourful visualisations, full interpretation, and publication-ready report.
⚡ 0. Quick Answer
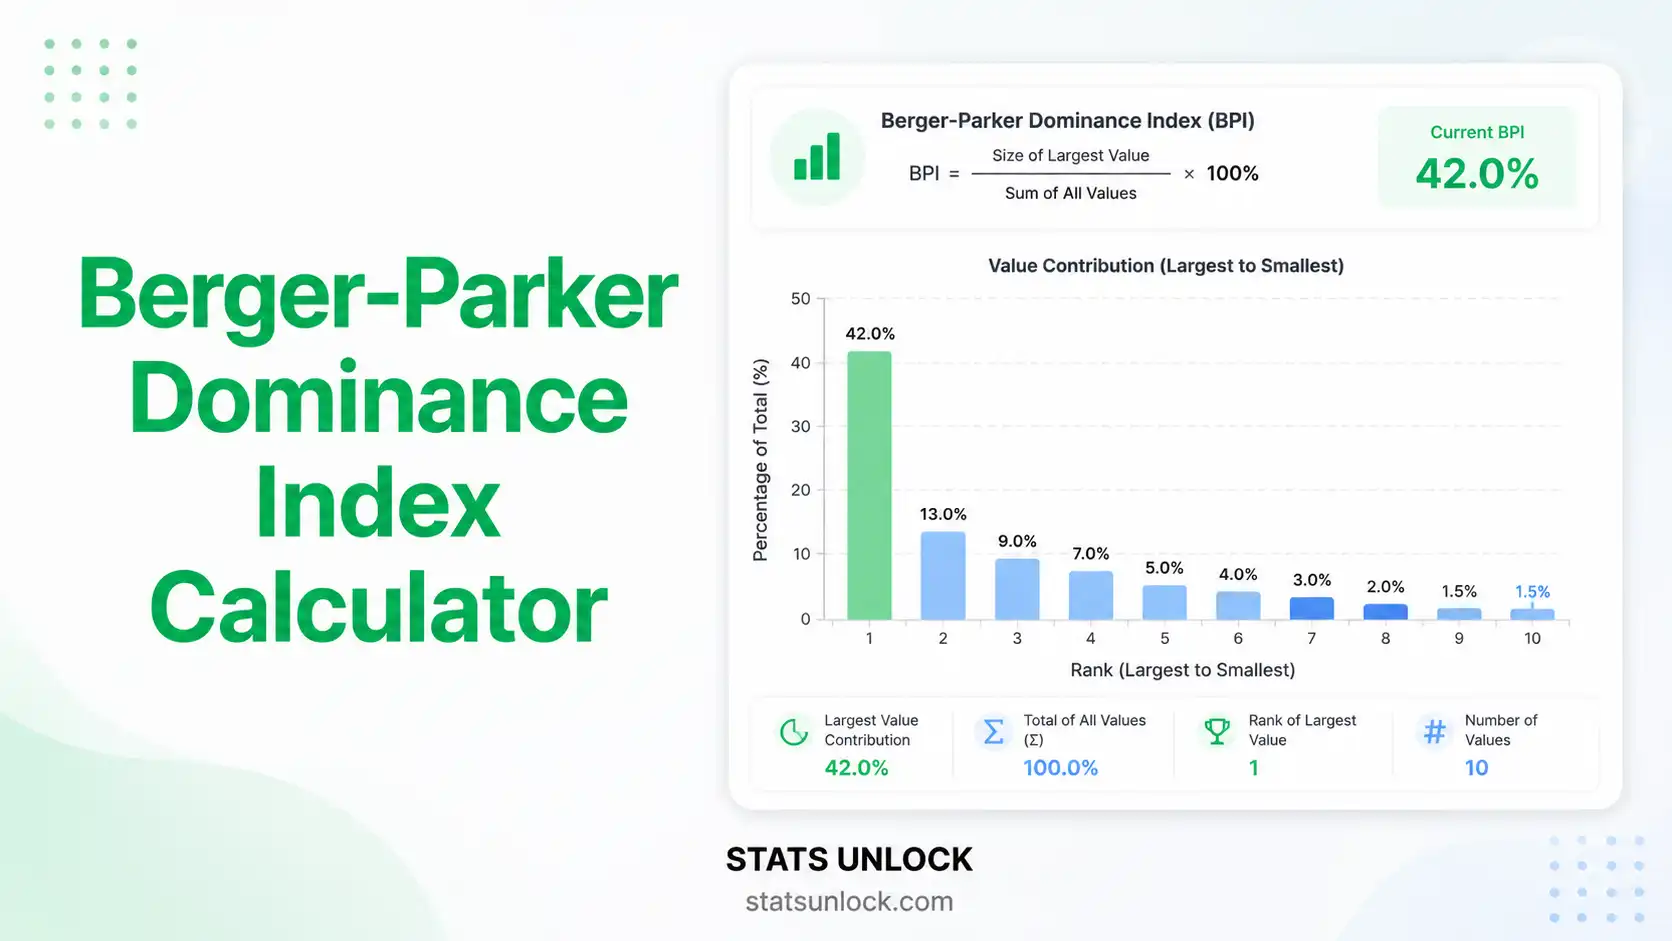
The Berger-Parker dominance index calculator measures how much of a community one species holds. Enter counts such as 68, 45, 22, 11, 4 and the tool returns d = 0.453 from d = Nmax / N, meaning the commonest species holds 45.33 percent of individuals, with reciprocal 1/d = 2.21. Higher d means stronger dominance.
🌿 Key Takeaways
- The Berger-Parker dominance index is the simplest dominance measure in ecology: one species count divided by the total.
- You only need two numbers, the largest species count and the overall total, so it works when a full species list is unavailable.
- Values run from 1/S to 1. Above 0.50 means one species holds most of the community; below 0.30 means the load is spread.
- The reciprocal 1/d is easier to compare between sites, because it behaves like a count of effective dominant species.
- It is robust to small samples and to missed rare species, which is exactly where the Shannon index becomes unreliable.
🌱 1. What Is the Berger-Parker Dominance Index?
The Berger-Parker dominance index (d) is the share of a sample held by its single commonest species. Divide the largest species count by the total number of individuals and you have it. If 68 of 150 birds are bulbuls, then d = 0.453 and the bulbul holds 45.33 percent of the community.
It is the simplest biodiversity index in use, and that simplicity is the point. Berger and Parker introduced it in 1970 while studying deep-sea foraminifera, where counting every rare species was impractical but identifying the dominant one was straightforward. The same logic applies today to camera trap grids, reef transects and forest plots: you often know your commonest species very well and your rarest hardly at all.
Because it ignores everything except the top species, it stays stable when the Shannon index does not. Missing a few singletons changes H' noticeably; it barely moves d. That makes Berger-Parker the honest choice for small samples, pilot surveys and any dataset where the rare tail is poorly known.
1.1 The two forms you will see
| Form | Formula | Range | Reads as |
|---|---|---|---|
| Dominance (d) | Nmax / N | 1/S to 1 | Higher means more dominated |
| Reciprocal (1/d) | N / Nmax | 1 to S | Higher means more diverse |
What to conclude: the reciprocal is often preferred in papers because it rises with diversity, matching the direction of every other index. Say which form you are reporting, because 0.453 and 2.21 describe the same community.
1.2 What the value means
| d | Top species holds | Reading | Typical setting |
|---|---|---|---|
| Below 0.20 | Under 20 percent | Very low dominance Healthy | Species-rich tropical samples, large insect traps |
| 0.20 to 0.30 | 20 to 30 percent | Low dominance Healthy | Mature forest, healthy reef transect |
| 0.30 to 0.50 | 30 to 50 percent | Moderate Watch | Edge habitat, secondary forest, farmland |
| 0.50 to 0.75 | 50 to 75 percent | High dominance Concern | Degraded sites, early succession, urban cores |
| Above 0.75 | Over 75 percent | Extreme Concern | Invasion, pollution, plantation, breeding colony |
What to conclude: the worked example scores 0.453, moderate dominance. Note that a breeding colony or reed bed can sit above 0.75 naturally and still be a high-value habitat, so read d against a reference site of the same type.
📥 2. Data Input
Enter species count data. The Berger-Parker index uses the most abundant species count divided by the total, d = Nmax / N.
0 valid values entered
Supports .csv, .txt, .xlsx, .xls. Select ONE column containing your species count values, each row in that column becomes one species/group.
Edit species and counts directly. Click "Add Species" to append more rows.
0 values entered
⚙️ 2.1 Analysis Configuration
Used in interpretation, reporting examples, and the research poster.
Label for the taxonomic or functional group analysed.
Compare result against a published d value.
📊 3. Results Summary
Berger-Parker Dominance Index Equation
The formula for the Berger-Parker dominance index (d) is:
- d: Berger-Parker dominance index, ranging from near 0 (no dominance) to 1 (single-species dominance)
- Nmax: Number of individuals of the single most abundant species in the community
- N: Total number of individuals across all species
- 1/d: Berger-Parker reciprocal, the effective number of "equally common" dominant species
- Threshold: d > 0.5 indicates strong dominance by a single species; d < 0.3 indicates an even community
| Statistic | Value | Description |
|---|
📈 3.1 Four Visualisations
📖 4. Interpretation of Results, In Detail
✍️ 5. How to Write Your Results in Research
Five fully detailed reporting templates auto-filled with your computed values. Copy the one that matches your audience.
🪧 5.1 Research Poster Panel
🧮 6. Formulas Used
Every number this Berger-Parker dominance index calculator reports comes from one of the seven formulas below. Card 1 is the index itself, and each later card puts it in context.
Berger-Parker dominance index
- d Berger-Parker dominance, unitless, a proportion
- Nmax count of the single commonest species
- N total individuals across all species
- Range: 1/S to 1. It reaches 1 when only one species is present.
- Example: 68 / 150 = 0.4533.
Reciprocal Berger-Parker
- 1/d reciprocal index, in effective species units
- Range: 1 to S. It equals S only when every species is equally common.
- Use for: reporting, because it rises with diversity like every other index.
- Example: 150 / 68 = 2.206.
Dominance as a percentage
- Range: 0 to 100 percent.
- Example: 0.4533 × 100 = 45.33 percent.
- Use for: reports and presentations, where a percentage is read faster than a proportion.
- Note: this is identical to the dominant species' relative abundance.
Subordinate share
- Meaning: the share of the community held by every species except the dominant one.
- Example: (1 - 0.4533) × 100 = 54.67 percent, which is 82 individuals.
- Use for: a plain sentence in a report, since "one species holds nearly half" is easier to grasp than a decimal.
Minimum possible dominance
- S species richness, a count
- Meaning: the value d would take if every species were equally common.
- Example: with 5 species, d cannot fall below 0.20.
- Rule: d is bounded by richness, so compare d only between samples with similar S, or use the standardised form below.
Richness-standardised dominance
- d* dominance rescaled to 0 to 1 regardless of richness
- Meaning: 0 is perfectly even for that richness, 1 is a single species.
- Example: (0.4533 - 0.20) / (1 - 0.20) = 0.317.
- Use for: comparing sites whose species counts differ a lot.
The sibling dominance measures
- Simpson D uses every species, not just the top one
- McNaughton index uses the top two species, for co-dominated communities
- Example: Simpson D = 0.323 and McNaughton = (68 + 45) / 150 = 0.753 for this dataset.
- Rule: if two species clearly share the top, Berger-Parker alone understates the dominance.
🧭 7. How to Use This Calculator
Ten steps from a field sheet to a publication-ready Berger-Parker result.
- Collect standardised counts. Record the number of individuals for each species using the same effort at every site.
- Count the dominant species carefully. The whole index rests on Nmax, so an error there moves the result directly.
- Pick an input tab. Use Paste or Type for a quick run, Upload CSV or Excel for a spreadsheet, or Manual Table to key in rows.
- Enter species names and counts. Names appear in the results table and identify the dominant species by name.
- Or load a sample dataset. The preloaded ecological datasets show different dominance patterns before you use your own data.
- Name your study area. Type the site name into the Study Area box so it appears in every report template and in the poster panel.
- Set the decimal places. Three decimals is normal for d in ecology papers, or report the percentage to two.
- Click Run Berger-Parker Analysis. Nothing computes until you do. The tool returns d, 1/d, Nmax, N, richness and four charts.
- Check the dominant species is the one you expect. If an unexpected species tops the list, look for a data entry error or a single aggregation.
- Copy or download your result. Use the report templates, the poster panel, Download Doc or Download PDF for your thesis or paper.
📗 8. How to Calculate Berger-Parker in Excel
Excel, step by step, with the same worked example used everywhere on this page
The worked example below uses five species with counts 68, 45, 22, 11, 4 (N = 150). Excel, R, Python and this calculator all return d = 0.4533, 1/d = 2.2059 and a dominance of 45.33 percent.
8.1 The Excel functions you need
| Function | What it does | Example |
|---|---|---|
| MAX | Finds the largest species count, Nmax | =MAX(B2:B6) |
| SUM | Adds your counts to get N | =SUM(B2:B6) |
| INDEX and MATCH | Returns the name of the dominant species | =INDEX(A2:A6,MATCH(MAX(B2:B6),B2:B6,0)) |
| COUNTIF | Counts species present, giving S for the standardised form | =COUNTIF(B2:B6,">0") |
| LARGE | Returns the second largest count, for the McNaughton index | =LARGE(B2:B6,2) |
| COUNTIF on the max | Checks whether two species tie for the top | =COUNTIF(B2:B6,MAX(B2:B6)) |
What to conclude: this is the only index on StatsUnlock that needs no proportion column at all. MAX divided by SUM is the entire calculation.
8.2 Step by step in the sheet
Step 1. Total the counts
Species names go in column A, counts in column B. Cell B7 holds =SUM(B2:B6) and returns N = 150.
Step 2. Find the largest count
B8 holds =MAX(B2:B6) and returns 68, the bulbul count shown in red. This single value is N max, and it is the only species-level number the index uses.
Step 3. Divide to get d
B9 holds =B8/B7 and returns d = 0.4533. Multiply by 100 for the percentage version, 45.33 percent, which is what most reports quote.
Step 4. Add the reciprocal and the species name
B10 holds =1/B9 and returns 2.2059. INDEX with MATCH returns the dominant species name, Bulbul, and the COUNTIF check returns 1, confirming no tie for the top spot.
8.3 The awkward cases
| Case | What breaks | Fix |
|---|---|---|
| Two species tie for the top | Nothing numerically, but INDEX names only the first | Check with COUNTIF on MAX, and report both species as co-dominant |
| A total row inside the range | MAX picks up the total, so d returns about 0.5 every time | Stop the range at the last species row |
| Duplicate species rows | One species is split, so Nmax is too small and d is understated | Use a PivotTable to sum counts by species name first |
| Data already in percentages | N is 100, so d still works but the raw counts are gone | d is fine. Any other index needing raw counts is not. |
| Only one species present | d returns exactly 1 | Correct. A single-species sample is complete dominance. |
What to conclude: the total-row error is the dangerous one, because a d of roughly 0.50 looks like a plausible ecological result rather than an obvious mistake.
8.4 Why answers differ between Excel, R and Python
For d itself they should not differ, because it is one division with no logs, no squares and no rounding sensitivity. Differences come from three places. First, which form was reported: 0.453 is d and 2.206 is 1/d, and both get called "the Berger-Parker index" in the literature. Second, whether zero-count species were left in the data: they do not change d at all, but they do change S, which matters if you use the richness-standardised form. Third, whether the value was reported as a proportion or a percentage. Name the form and the problem disappears.
8.5 Charting the result in Excel
- Ranked bar chart with the top bar highlighted. Sort descending, then colour the first bar differently. This is the clearest single picture of dominance.
- Dominant versus subordinate. A two-slice pie or a single stacked bar at 45.33 and 54.67 percent. Blunt, and very effective for non-specialist audiences.
- d across sites or years. A line or bar chart with the axis fixed from 0 to 1, so differences are not exaggerated.
- Label the axis with the form. Write "Berger-Parker d" or "1/d", never just "dominance", because the two run in opposite directions.
8.6 Excel error messages and what they mean
| Message | Cause | Fix |
|---|---|---|
| #DIV/0! | The total cell is empty or zero | Check the SUM range covers every data row |
| #VALUE! | Text inside a numeric range | Clear notes such as "none seen" from the count column |
| #N/A | MATCH could not find the maximum value | Check the INDEX and MATCH ranges are the same height |
| d is above 1 | Nmax and N were divided the wrong way round | d cannot exceed 1. Swap the numerator and denominator. |
| d is exactly 0.5 on every site | A total row is inside the MAX range | Exclude the total row |
| 1/d is below 1 | The reciprocal was taken of a d above 1 | Fix d first; 1/d is bounded below by 1 |
What to conclude: d above 1 or 1/d below 1 are both arithmetically impossible, and both point at the same swapped-division mistake.
📘 9. How to Calculate Berger-Parker in R
R, one complete script you can run top to bottom
9.1 The complete script
Copy this into RStudio and press Run. It needs no packages. Change only the counts line. It prints d, the reciprocal, the standardised form and a tie check, then saves one 300 dpi figure.
# ------------------------------------------------------------------
# Berger-Parker Dominance Index in R
# StatsUnlock.com - free ecology and wildlife analysis tools
# ------------------------------------------------------------------
set.seed(42)

# 1. YOUR DATA -- change only this line
counts <- c(68, 45, 22, 11, 4)
species <- c("Bulbul", "Babbler", "Sunbird", "Barbet", "Drongo")

# Reading from a file instead? Uncomment the two lines below.
# dat <- read.csv("my_survey.csv")          # columns: species, count
# counts <- dat$count; species <- dat$species

# 2. CLEAN THE DATA
counts[is.na(counts)] <- 0        # missing values become zero
keep <- counts > 0                # a species recorded as zero is not present
counts <- counts[keep]
species <- species[keep]

# 3. CALCULATE
N <- sum(counts)                          # total individuals
S <- length(counts)                       # species richness
Nmax <- max(counts)                       # count of the commonest species
d <- Nmax / N                             # Berger-Parker dominance
recip <- 1 / d                            # reciprocal form
dom_pct <- d * 100                        # dominance as a percentage
sub_pct <- (1 - d) * 100                  # everything else
d_min <- 1 / S                            # lowest possible d for this richness
d_star <- (d - d_min) / (1 - d_min)       # richness-standardised dominance

dominant <- species[which.max(counts)]    # name of the commonest species
ties <- sum(counts == Nmax)               # check for co-dominants
mcnaughton <- sum(sort(counts, decreasing = TRUE)[1:2]) / N   # top two species

# There is no berger-parker function in vegan. Build it like this:
# library(vegan)
# d <- apply(m, 1, max) / rowSums(m)      # one d per site from a matrix

# 4. PRINT A PLAIN-ENGLISH VERDICT
verdict <- if (d > 0.50) "high dominance" else
           if (d >= 0.30) "moderate dominance" else "low dominance, even community"
cat("Total individuals N     :", N, "\n")
cat("Species richness S      :", S, "\n")
cat("Dominant species        :", dominant, "with", Nmax, "individuals\n")
cat("Berger-Parker d         :", round(d, 4), "\n")
cat("Reciprocal 1/d          :", round(recip, 4), "\n")
cat("Dominance percent       :", round(dom_pct, 2), "\n")
cat("All other species       :", round(sub_pct, 2), "percent\n")
cat("Lowest possible d       :", round(d_min, 4), "\n")
cat("Standardised d*         :", round(d_star, 4), "\n")
cat("McNaughton (top two)    :", round(mcnaughton, 4), "\n")
if (ties > 1) cat("WARNING:", ties, "species tie for the top count\n")
cat("Verdict                 :", verdict, "\n")

# 5. SAVE ONE 300 dpi FIGURE
png("berger_parker.png", width = 1800, height = 1200, res = 300)
ord <- order(counts, decreasing = TRUE)
cols <- c("#c0392b", rep("#3aab6d", S - 1))
bp <- barplot(counts[ord],
              names.arg = species[ord],
              col = cols, border = NA, las = 2,
              ylim = c(0, Nmax * 1.2),
              ylab = "Number of individuals",
              main = paste0("Berger-Parker d = ", round(d, 3)))
text(bp, counts[ord], labels = counts[ord], pos = 3, cex = 0.9)
dev.off()
cat("Figure saved as berger_parker.png\n")
9.2 What each line does
| Line | What it does |
|---|---|
| counts <- c(68, 45, ...) | Your species counts. This is the only line most users change. |
| keep <- counts > 0 | Drops species recorded as absent. They do not affect d but they do affect S. |
| Nmax <- max(counts) | The count of the commonest species. The only species-level number the index uses. |
| d <- Nmax / N | The Berger-Parker index. One division, no logs, no squares. |
| recip <- 1 / d | The reciprocal form, which rises with diversity. |
| d_min <- 1 / S | The floor d can reach at this richness. Useful context for any d value. |
| d_star <- (d - d_min) / (1 - d_min) | Rescales d to 0 to 1 so sites with different richness can be compared. |
| which.max(counts) | Position of the commonest species, used to get its name. |
| ties <- sum(counts == Nmax) | Checks for co-dominants. If this is above 1, do not name a single dominant species. |
| sort(counts, decreasing = TRUE)[1:2] | The top two counts, for the McNaughton index. |
| apply(m, 1, max) / rowSums(m) | One d per site straight from a site-by-species matrix. |
9.3 What the figure shows
The script saves a ranked bar chart with the dominant species picked out in red and every other species in green, with d printed in the title. The visual point is the height gap between the first bar and the second: that gap is what Berger-Parker measures, and a reader grasps it without reading a number. The counts are printed above each bar so the figure stands alone in a report.
9.4 Problems and fixes
| Problem | Cause | Fix |
|---|---|---|
| Error: could not find function "bergerparker" | vegan has no Berger-Parker function | Build it: max(x) / sum(x). It is one line. |
| skbio or vegan "dominance" gives 0.323 | That function returns Simpson's D, not Berger-Parker | They are different indices. Berger-Parker is 0.4533 on this data. |
| d is above 1 | The division was inverted | d cannot exceed 1. Check max is the numerator. |
| The wrong species is named dominant | Two species tie for the top and which.max returns the first | Keep the ties check in the script and report co-dominants |
| d looks high for a species-poor site | d is bounded below by 1/S, so few species force d upward | Use d_star, the richness-standardised form |
| Empty PNG file | dev.off() was never called | Run dev.off() once, then re-run the plotting block |
9.5 One-liners worth keeping
| Code | Returns |
|---|---|
| max(x) / sum(x) | Berger-Parker d from a count vector |
| sum(x) / max(x) | The reciprocal, 1/d |
| apply(m, 1, max) / rowSums(m) | One d per site from a site-by-species matrix |
| names(x)[which.max(x)] | The dominant species name from a named vector |
| sum(sort(x, decreasing = TRUE)[1:2]) / sum(x) | The McNaughton index for co-dominated communities |
| vegan::diversity(x, "simpson") | Simpson's 1 - D, the fuller dominance alternative |
🐍 10. How to Calculate Berger-Parker in Python
Python, one complete script you can run top to bottom
10.1 The complete script
Save this as berger_parker.py and run it. Change only the counts line. It prints every form of the index and saves one 300 dpi figure.
# ------------------------------------------------------------------
# Berger-Parker Dominance Index in Python
# StatsUnlock.com - free ecology and wildlife analysis tools
# ------------------------------------------------------------------
import numpy as np
import matplotlib
matplotlib.use("Agg")
import matplotlib.pyplot as plt

np.random.seed(42)

# 1. YOUR DATA -- change only this line
counts = np.array([68, 45, 22, 11, 4], dtype=float)
species = ["Bulbul", "Babbler", "Sunbird", "Barbet", "Drongo"]

# Reading from a file instead? Uncomment the three lines below.
# import pandas as pd
# dat = pd.read_csv("my_survey.csv")          # columns: species, count
# counts, species = dat["count"].to_numpy(float), dat["species"].tolist()

# 2. CLEAN THE DATA
counts = np.nan_to_num(counts, nan=0.0)       # missing values become zero
keep = counts > 0                             # a zero count is not present
species = [s for s, k in zip(species, keep) if k]
counts = counts[keep]

# 3. CALCULATE
N = counts.sum()                              # total individuals
S = counts.size                               # species richness
Nmax = counts.max()                           # count of the commonest species
d = float(Nmax / N)                           # Berger-Parker dominance
recip = 1 / d                                 # reciprocal form
dom_pct = d * 100                             # dominance as a percentage
sub_pct = (1 - d) * 100                       # everything else
d_min = 1 / S                                 # lowest possible d for this richness
d_star = (d - d_min) / (1 - d_min)            # richness-standardised dominance

dominant = species[int(np.argmax(counts))]    # name of the commonest species
ties = int(np.sum(counts == Nmax))            # check for co-dominants
mcnaughton = float(np.sort(counts)[::-1][:2].sum() / N)   # top two species

# scikit-bio has it as dominance():
# from skbio.diversity.alpha import dominance
# NOTE: skbio dominance() returns Simpson's D, NOT Berger-Parker. Do not confuse them.

# 4. PRINT A PLAIN-ENGLISH VERDICT
if d > 0.50:
    verdict = "high dominance"
elif d >= 0.30:
    verdict = "moderate dominance"
else:
    verdict = "low dominance, even community"
print(f"Total individuals N     : {N:.0f}")
print(f"Species richness S      : {S}")
print(f"Dominant species        : {dominant} with {Nmax:.0f} individuals")
print(f"Berger-Parker d         : {d:.4f}")
print(f"Reciprocal 1/d          : {recip:.4f}")
print(f"Dominance percent       : {dom_pct:.2f}")
print(f"All other species       : {sub_pct:.2f} percent")
print(f"Lowest possible d       : {d_min:.4f}")
print(f"Standardised d*         : {d_star:.4f}")
print(f"McNaughton (top two)    : {mcnaughton:.4f}")
if ties > 1:
    print(f"WARNING: {ties} species tie for the top count")
print(f"Verdict                 : {verdict}")

# 5. SAVE ONE 300 dpi FIGURE
order = np.argsort(counts)[::-1]
cols = ["#c0392b"] + ["#3aab6d"] * (S - 1)
fig, ax = plt.subplots(figsize=(6, 4))
bars = ax.bar([species[i] for i in order], counts[order], color=cols)
ax.bar_label(bars, fmt="%.0f", padding=3)
ax.set_ylim(0, Nmax * 1.2)
ax.set_ylabel("Number of individuals")
ax.set_title(f"Berger-Parker d = {d:.3f}")
plt.xticks(rotation=45, ha="right")
plt.tight_layout()
plt.savefig("berger_parker.png", dpi=300)
print("Figure saved as berger_parker.png")
10.2 What each line does
| Line | What it does |
|---|---|
| matplotlib.use("Agg") | Draws without a screen, so the script runs on a server or in a notebook. |
| counts = np.array([...]) | Your species counts. The only line most users change. |
| keep = counts > 0 | Drops absent species. They do not change d but they do change S. |
| Nmax = counts.max() | The commonest species count, the numerator of the index. |
| d = Nmax / N | The Berger-Parker index itself. |
| recip = 1 / d | The reciprocal form, which rises with diversity. |
| d_min = 1 / S | The floor d can reach at this richness. |
| d_star = (d - d_min) / (1 - d_min) | Rescales d so sites with different richness can be compared fairly. |
| np.argmax(counts) | Position of the commonest species, used to get its name. |
| ties = np.sum(counts == Nmax) | Counts co-dominants. Above 1 means do not name a single dominant. |
| np.sort(counts)[::-1][:2] | The top two counts, for the McNaughton index. |
10.3 What the figure shows
The saved PNG is a ranked bar chart with the dominant species in red and the rest in green, labelled with counts and d in the title, identical in meaning to the R figure. For the blunt two-slice version that works well in presentations, use ax.pie([d, 1-d], labels=["Dominant", "All others"], autopct="%1.1f%%").
10.4 Problems and fixes
| Problem | Cause | Fix |
|---|---|---|
| skbio dominance() returns 0.323 | That function is Simpson's D, not Berger-Parker | Use counts.max() / counts.sum(), which gives 0.4533 |
| d is above 1 | The division was inverted | d cannot exceed 1. Check max is the numerator. |
| Integer division gives 0 | Counts stored as int in old Python code | Keep dtype=float in the array line |
| The wrong species is named | argmax returns the first of several tied maxima | Keep the ties check and report co-dominants |
| d looks high for a species-poor site | d is bounded below by 1/S | Report d_star alongside |
| Figure window never opens | The Agg backend has no screen output | That is expected. Open the saved PNG file. |
10.5 One-liners worth keeping
| Code | Returns |
|---|---|
| c.max() / c.sum() | Berger-Parker d |
| c.sum() / c.max() | The reciprocal, 1/d |
| df.max(axis=1) / df.sum(axis=1) | One d per site from a pandas site-by-species table |
| species[int(np.argmax(c))] | The dominant species name |
| np.sort(c)[::-1][:2].sum() / c.sum() | The McNaughton index |
| 1 - np.sum((c/c.sum())**2) | Simpson's 1 - D, the fuller dominance alternative |
📋 11. Reference Tables
Six lookup tables for reading, converting and sanity-checking a Berger-Parker result.
Table 11.1 Published d values by habitat type
| Habitat | Taxon | Typical d | Typical S |
|---|---|---|---|
| Lowland tropical rainforest | Birds | 0.08 to 0.18 | 40 to 120 |
| Dry deciduous forest | Birds | 0.15 to 0.28 | 25 to 50 |
| Temperate woodland | Birds | 0.18 to 0.35 | 15 to 35 |
| Grassland, managed | Plants | 0.25 to 0.45 | 10 to 30 |
| Wetland, freshwater | Waterbirds | 0.22 to 0.45 | 12 to 40 |
| Coral reef transect | Fish | 0.15 to 0.30 | 30 to 80 |
| Camera trap grid | Large mammals | 0.25 to 0.50 | 6 to 20 |
| Urban park | Birds | 0.30 to 0.55 | 8 to 20 |
| Intensive cropland | Arthropods | 0.35 to 0.65 | 5 to 20 |
| Breeding colony or reed bed | Birds | 0.70 to 0.95 | 3 to 15 |
What to conclude: compare within a row, never across. A d of 0.30 is high for a rainforest bird survey and low for a camera trap grid, because richness sets the floor.
Table 11.2 Converting d, 1/d and percentage
| d | 1/d | Dominant holds | All others hold | Reading |
|---|---|---|---|---|
| 0.10 | 10.00 | 10% | 90% | Very low dominance |
| 0.20 | 5.00 | 20% | 80% | Low |
| 0.30 | 3.33 | 30% | 70% | Moderate begins |
| 0.4533 | 2.21 | 45.33% | 54.67% | The worked example |
| 0.50 | 2.00 | 50% | 50% | High dominance begins |
| 0.60 | 1.67 | 60% | 40% | High |
| 0.80 | 1.25 | 80% | 20% | Extreme |
| 0.95 | 1.05 | 95% | 5% | Near monoculture |
| 1.00 | 1.00 | 100% | 0% | Single species |
What to conclude: 1/d spreads out the low-dominance end where d compresses. Between d = 0.10 and d = 0.20 the reciprocal halves from 10 to 5, which is far easier to discuss than a 0.1 difference.
Table 11.3 The floor set by species richness
| Species richness S | Minimum possible d (1/S) | Maximum 1/d | Meaning |
|---|---|---|---|
| 2 | 0.500 | 2 | d can never drop below 0.50 with two species |
| 5 | 0.200 | 5 | The worked example's floor |
| 10 | 0.100 | 10 | |
| 20 | 0.050 | 20 | |
| 50 | 0.020 | 50 | |
| 100 | 0.010 | 100 | A very rich sample can reach near-zero d |
What to conclude: this is the limitation reviewers raise most. A species-poor site cannot score a low d no matter how even it is, so use the standardised form d* when richness differs between sites.
Table 11.4 Standardised dominance d*
| d | S = 5, d* | S = 20, d* | S = 50, d* |
|---|---|---|---|
| 0.20 | 0.000 | 0.158 | 0.184 |
| 0.30 | 0.125 | 0.263 | 0.286 |
| 0.4533 | 0.317 | 0.425 | 0.442 |
| 0.50 | 0.375 | 0.474 | 0.490 |
| 0.70 | 0.625 | 0.684 | 0.694 |
| 0.90 | 0.875 | 0.895 | 0.898 |
What to conclude: read down a column and the ordering is unchanged; read across a row and you see how much of a raw d value is simply an artefact of having few species.
Table 11.5 Berger-Parker against the other dominance measures
| Measure | Uses | Range | Best when |
|---|---|---|---|
| Berger-Parker d | The top species only | 1/S to 1 | Small samples, incomplete rare-species lists, plain reporting |
| Reciprocal 1/d | The top species only | 1 to S | You want a value that rises with diversity |
| McNaughton index | The top two species | 2/S to 1 | Two species clearly co-dominate |
| Simpson's D | Every species | 1/S to 1 | You need dominance weighted across the whole community |
| Pielou's J' | Every species | 0 to 1 | You want evenness rather than dominance |
| Shannon H' | Every species | 0 to ~4.6 | Rare species matter to your question |
What to conclude: Berger-Parker and Simpson's D answer the same question at different resolutions. On the worked example they give 0.453 and 0.323, and the gap between them tells you the subordinate species are not negligible.
Table 11.6 Minimum sampling effort by survey type
| Survey type | Minimum effort for a usable d | Preferred effort |
|---|---|---|
| Bird point counts | 10 points, 40 individuals | 30 points across 3 visits |
| Line transects | 1 km walked | 10 km, repeated in 2 seasons |
| Camera trapping | 200 trap nights | 1,000 or more trap nights |
| Vegetation quadrats | 8 quadrats of 1 m² | 30 quadrats, stratified by habitat |
| Pitfall traps | 15 trap days | 100 trap days across 5 stations |
| Reef fish belt transects | 3 transects of 50 m | 12 transects across 3 depths |
| Light trap insects | 2 trap nights | 12 trap nights across the season |
What to conclude: these minimums are the lowest of any index on StatsUnlock. Berger-Parker stabilises early because it depends only on the commonest species, which you detect first.
📊 12. Example Results
Eight worked scenarios showing what different Berger-Parker values look like in the field.
Scenario 1: Species-rich tropical forest
A bird survey records 412 individuals across 28 species, the commonest being 52 individuals. d = 52/412 = 0.126 and 1/d = 7.9. Very low dominance, typical of an intact lowland forest where no single species runs the community.
Scenario 2: Degraded fragment
A logged patch holds 200 individuals across 6 species, with 150 of one species. d = 0.750 and 1/d = 1.33. Extreme dominance: three quarters of every bird seen is the same species, a clear disturbance signal.
Scenario 3: Two sites, same richness, different d
Two wetlands each hold 12 waterbird species. Site A's commonest species takes 18 percent of individuals (d = 0.18), Site B's takes 52 percent (d = 0.52). Identical species lists, opposite community structure, and only a dominance measure reveals it.
Scenario 4: Invasion tracked over five years
A grassland's d rises from 0.24 to 0.61 over five years as one invasive grass spreads, while species richness stays at 14 throughout. Nothing was lost, but the community is now run by one species. This is the classic use of the index.
Scenario 5: Camera trap grid
Across 1,400 trap nights, 320 independent detections cover 9 mammal species, with chital at 96 detections. d = 0.300 and 1/d = 3.33. Moderate dominance, normal for a dry deciduous mammal community with an abundant ungulate.
Scenario 6: Where Berger-Parker misleads
A site holds 3 species with counts 40, 38, 2. d = 0.50 looks like high dominance, but two species clearly co-dominate. The McNaughton index (78/80 = 0.975) tells the real story. Always check the second-largest count.
Scenario 7: A naturally dominated habitat
A reed bed holds 240 individuals across 5 species, with 205 reed warblers. d = 0.854. That would be alarming in a forest, but reed beds are single-species systems by design and this one is in good condition. Low diversity is not the same as poor habitat.
Scenario 8: The worked example used in Sections 8, 9 and 10
Five species with counts 68, 45, 22, 11, 4 give N = 150, Nmax = 68, d = 0.4533, 1/d = 2.2059, dominance 45.33 percent, standardised d* = 0.317 and McNaughton 0.753. Excel, R, Python and this calculator all agree.
🥾 13. How to Collect Raw Data in the Field
The Berger-Parker index is only as good as your count of the commonest species. These eighteen points are written for that. Print this list and take it with you.
Plan
- Fix your effort before you start. Decide trap nights, transect length or number of point counts, and keep it identical at every site you intend to compare.
- Define the community you are measuring. All birds, or only insectivores? The dominant species changes with the boundary you draw, and so does d.
- Choose your unit of pooling. Site, transect or station. Berger-Parker calculated per station and then averaged is not the same number as one calculated on pooled counts.
- Pick the season deliberately. Dominance swings with breeding, migration and flowering. One species can run a site in June and be absent in January.
- Randomise or stratify station placement. Placing stations where you expect wildlife inflates the commonest species and pushes d upward.
Kit
- Prepared datasheet. Columns for Date, Site, Station, Observer, Species, Count, Detection type and Notes. One row per species per station.
- Tally counter or clicker for the abundant species. Counting 68 individuals by memory is where the largest errors enter this index.
- Camera or phone for vouchering anything you cannot identify with confidence.
- Rangefinder or measuring tape so transect lengths and plot sizes are real numbers, not estimates.
- Waterproof notebook and a spare pencil. A pen fails in rain; the survey does not stop for it.
Collect
- Count the abundant species most carefully. Nmax is half the calculation. An error of ten individuals in a flock moves d directly.
- Record every species, even singletons. They do not change d, but they set S, which the standardised form and every sibling index need.
- Separate independent detections. For camera traps, records of the same species within 30 minutes count once. Without this rule, one curious animal can become the dominant species.
- Note aggregations explicitly. Flocks, fruiting trees, roosts and carcasses concentrate one species and can double your d for reasons unrelated to habitat.
- Use consistent morphospecies labels. "Warbler sp. 1" is fine, but it must mean the same bird on every sheet, or you will split one species into two and understate dominance.
Check
- Total your counts in the field. Add the column before you leave the site. A missing row is easy to fix there and impossible to fix later.
- Confirm the dominant species by eye. If the sheet says one species dominates and your impression says another, one of the two is wrong. Find out which before you go home.
- Enter the data the same day. Photograph paper sheets or type them into a spreadsheet each evening, while you can still read your own handwriting.
🎯 14. When to Use This Tool
14.1 Quick decision checklist
- ✅ You need a quick, intuitive single number summarising dominance.
- ✅ Your question is how skewed the community is toward one species.
- ✅ Your rare-species list is incomplete, which breaks Shannon but not this.
- ✅ Your sample is small, where Berger-Parker stays stable and H' does not.
- ✅ You are explaining a result to a manager, landowner or council.
- ❌ Rare species composition matters. Use Shannon or Hill q = 1.
- ❌ Two or more species co-dominate. Use the McNaughton index or Simpson's D.
- ❌ Species richness differs a lot between sites. Use the standardised d*, since d is bounded below by 1/S.
14.2 Four real situations
| Situation | What you do | What d tells you |
|---|---|---|
| Pre and post-disturbance bird survey | Same point counts before and after logging | Whether one species has taken over, usually before richness changes |
| National park camera trap community | 1,400 trap nights, independent detections per species | A defensible one-number summary of mammal community structure |
| Tree species dominance in forest plots | Stem counts per species per plot | Whether the plot is a near-monoculture or a mixed stand |
| Reef fish on impacted versus reference reefs | Belt transects at both, same depth and effort | Whether one tolerant species now runs the impacted reef |
14.3 Sampling design guidance
- Count the common species properly. This index cares about accuracy at the top of the distribution, not completeness at the bottom.
- Standardise effort. d is a proportion, so it is less effort-sensitive than richness, but unequal effort still biases which species tops the list.
- Replicate within sites. Three or more stations let you report a mean d with a standard error rather than a bare number.
- Record richness too. You need S to interpret d at all, because 1/S is the floor.
- Watch the season. A single migratory arrival can change the dominant species overnight.
14.4 Which metric next
- Want dominance across the whole community, not just the top species? Use Simpson's index.
- Want the mirror image, how evenly individuals are spread? Use Pielou's J'.
- Two species share the top? Use the McNaughton index, the sum of the top two shares.
- Want rare species to count? Use the Shannon Wiener index.
- Want to see the whole shape rather than one number? Plot a rank abundance curve.
🛠️ 15. Troubleshooting and Common Errors
Ten problems users hit with the Berger-Parker index, and how to fix each one.
My d is 0.45 but a colleague reports 2.21 for the same data
Cause: you reported d, they reported the reciprocal 1/d. Fix: both are called "the Berger-Parker index" in the literature. They are the same result. Name the form in your methods and in every table caption.
My d is above 1
Cause: the division was inverted, or a total row was included so Nmax picked up the total. Fix: d is a proportion and cannot exceed 1. Check that the largest species count is the numerator.
Every site comes out at almost exactly 0.5
Cause: a total row sits inside the range, so MAX returns the total and the total is roughly twice the largest species. Fix: stop your ranges at the last species row. This error is dangerous because 0.5 looks like a plausible result.
The tool named the wrong dominant species
Cause: two species tie for the top count, and lookup functions return only the first. Fix: the value of d is still correct. Check for ties before naming a single dominant species, and report co-dominants where they exist.
My species-poor site always looks dominated
Cause: d is bounded below by 1/S. With three species, d can never fall below 0.333 however even the community is. Fix: use the richness-standardised form d*, or compare only sites with similar richness.
d says high dominance but the community looks balanced
Cause: two species co-dominate, and Berger-Parker only sees one of them. Fix: check the second-largest count. If the top two are close, report the McNaughton index or Simpson's D instead.
My R or Python "dominance" function gives a different number
Cause: both scikit-bio's dominance() and most references to "dominance" in vegan mean Simpson's D, not Berger-Parker. Fix: they are different indices. Berger-Parker is simply max(x) / sum(x), which is one line in either language.
d jumped this year but nothing else changed
Cause: often a single aggregation, such as a flock, roost or fruiting tree, encountered on one survey day. Fix: check your field notes for that date and consider reporting the result with and without the aggregation.
Can I calculate d without a full species list?
Cause: you may only have the dominant count and a reliable total. Fix: yes, and this is the index's real advantage. You need Nmax and N only. You will not be able to calculate S, so the standardised form is unavailable.
Charts do not appear after I click Run
Cause: the charting library was blocked by a network filter or an offline device. Fix: reload the page on a normal connection. The numbers and the results table still work without charts.
⚠️ 16. Assumptions and Limitations
Berger-Parker is the most robust index on this site and the narrowest. It asks one question and answers it well. Problems arise when people read it as a general diversity measure.
16.1 What the index assumes
- The count of the commonest species is accurate. Everything else enters only through the total.
- Survey effort is standardised across the sites being compared.
- The dominant species had a fair chance of being detected, and is not simply the loudest or most conspicuous.
- Each record is independent. Ten photographs of one animal in one minute is one detection.
- Counts are of individuals, not biomass, cover, or basal area.
- Species rows are unique, with no species split across two differently spelled entries.
16.2 What it cannot tell you
- Anything about the other species. Two communities with identical d can have 3 species or 300.
- Whether two species share the dominance. It sees only the top one.
- Whether the dominant species is native, invasive or of conservation concern.
- Whether a difference between sites is statistically significant.
- How many species you failed to detect, which is the one thing it is deliberately indifferent to.
16.3 The four limitations reviewers raise most
| Limitation | Why it matters | What to do |
|---|---|---|
| Bounded below by 1/S | A species-poor site cannot score a low d however even it is | Report d* or restrict comparisons to similar richness |
| Blind to co-dominance | Two species at 40 percent each score the same d as one at 40 and a long tail | Check the second-largest count; report McNaughton where relevant |
| Two forms, one name | d and 1/d run in opposite directions and are both called the index | Name the form in the methods and every caption |
| Ignores everything below the top | Losing half your rare species does not move d at all | Pair with richness or Shannon so the rest of the community is represented |
What to conclude: report d with S and N attached. A d of 0.45 means something different at S = 5 than at S = 50, and the reader cannot tell which you had unless you say.
🏁 17. Conclusion
❓ 18. Frequently Asked Questions
Q1. What is the Berger-Parker dominance index and when should I use it?
The Berger-Parker index (d) is the proportion of a sample held by its single commonest species, calculated as the largest species count divided by the total. Use it when you want a simple dominance measure, when your sample is small, or when your rare-species list is incomplete.
Q2. How do you calculate the Berger-Parker index step by step?
Find the count of the most abundant species, then divide by the total number of individuals. With counts 68, 45, 22, 11, 4 the largest is 68 and the total is 150, so d = 68/150 = 0.4533. Multiply by 100 for the percentage, 45.33.
Q3. What is the Berger-Parker index formula?
d = Nmax / N, where Nmax is the number of individuals of the most abundant species and N is the total individuals across all species. The reciprocal form is 1/d = N / Nmax, which runs from 1 to S and rises with diversity.
Q4. What is the Excel formula for the Berger-Parker index?
Use =MAX(B2:B6)/SUM(B2:B6) in a single cell. No proportion column is needed. Add =COUNTIF(B2:B6,MAX(B2:B6)) as a check: if it returns more than 1, two species tie for the top and you should report co-dominance.
Q5. How do I calculate the Berger-Parker index in R?
One line: max(counts) / sum(counts). There is no Berger-Parker function in vegan, so do not look for one. For a site-by-species matrix use apply(m, 1, max) / rowSums(m) to get one value per site.
Q6. Which Python package calculates the Berger-Parker index?
NumPy alone: counts.max() / counts.sum(). Be careful with scikit-bio's dominance() function, which returns Simpson's D rather than Berger-Parker. On this page's worked example those give 0.323 and 0.4533 respectively.
Q7. What does a high Berger-Parker value mean?
It means one species holds a large share of the community. Above 0.50 the commonest species holds more than half of all individuals. High values often follow disturbance, pollution or invasion, though some habitats such as reed beds are naturally dominated.
Q8. What is a good Berger-Parker index value?
There is no universal figure, because the value depends on habitat and on species richness. Below 0.30 is low dominance, 0.30 to 0.50 is moderate, and above 0.50 is high. Compare against a reference site sampled the same way.
Q9. What is the difference between d and 1/d?
They are the same result in opposite directions. d rises with dominance, so higher means less diverse. The reciprocal 1/d rises with diversity, matching every other index, which is why many papers prefer it. For this page's example they are 0.453 and 2.21.
Q10. Berger-Parker vs Simpson's index, what is the difference?
Berger-Parker uses only the commonest species. Simpson's index squares every species proportion and sums them, so it accounts for the whole community. Berger-Parker is simpler and more robust to small samples; Simpson's is more informative when several species are common.
Q11. Why is my Berger-Parker value high for a species-poor site?
Because d is bounded below by 1/S. With three species, d can never fall below 0.333 however even the community is. Use the richness-standardised form, d* = (d - 1/S) / (1 - 1/S), when comparing sites with different richness.
Q12. Can the Berger-Parker index detect two co-dominant species?
No, and this is its main blind spot. Two species at 40 percent each give the same d as one species at 40 percent with a long rare tail. Check the second-largest count, and use the McNaughton index, the combined share of the top two, when they are close.
Q13. Do I need a complete species list to calculate it?
No. You need only the largest species count and a reliable total, which is the index's real advantage over Shannon and Simpson. Without the full list you cannot calculate species richness, so the standardised form will be unavailable.
Q14. Does sample size affect the Berger-Parker index?
Much less than it affects richness or the Shannon index. Because it depends only on the commonest species, which you detect first, it stabilises after relatively little effort. That makes it a good choice for pilot surveys and small samples.
Q15. How do I report the Berger-Parker index in a journal?
Name the form, give the value, and add richness and sample size, for example: Berger-Parker d = 0.453 (Nmax = 68, N = 150, S = 5 species). Stating S matters, because d cannot fall below 1/S.
Q16. What are the assumptions and limitations of the Berger-Parker index?
It assumes accurate counting of the commonest species and standardised effort. It cannot tell you anything about the rest of the community, cannot detect co-dominance, and is bounded below by 1/S, so richness-poor sites always look more dominated.
Q17. Is a high Berger-Parker value always bad for conservation?
No. Reed beds, salt marshes, kelp forests and breeding colonies are naturally dominated by one species and often have high conservation value. A high d is a description of community structure, not a verdict on habitat quality.
Q18. Who created the Berger-Parker index?
Wolfgang Berger and Frances Parker introduced it in 1970 in a study of planktonic foraminifera in deep-sea sediments, published in Science. They needed a dominance measure that worked when rare species could not be reliably counted.
Q19. Can I use the Berger-Parker index for camera trap data?
Yes, and it suits camera traps well. Use independent detections rather than raw photographs, applying a 30-minute threshold so one curious animal does not become the dominant species. Report trap nights alongside the index.
Q20. Is this Berger-Parker calculator free and accurate?
Yes. It is completely free, runs entirely in your browser, stores no data, and uses the published formula d = Nmax / N with the reciprocal, percentage and standardised forms. Results are cross-checked against R and Python.
📝 19. Cite This Tool
Use one of these three formats when you mention this Berger-Parker calculator in a thesis, report, or paper.
APA 7th edition
StatsUnlock. (2026). Berger-Parker dominance index calculator: Free online ecology tool [Computer software]. https://statsunlock.com/tools/berger-parker-dominance-index-calculator
BibTeX
@misc{statsunlock_bergerparker_2026,
  title        = {Berger-Parker Dominance Index Calculator: Free Online Ecology Tool},
  author       = {{StatsUnlock}},
  year         = {2026},
  howpublished = {\url{https://statsunlock.com/tools/berger-parker-dominance-index-calculator}},
  note         = {Accessed: 2026-09-16}
}
Methods paragraph
Community dominance was quantified using the Berger-Parker index, d = Nmax / N, where Nmax is the number of individuals of the most abundant species and N is the total number of individuals recorded (Berger & Parker, 1970; Magurran, 2004). Results are reported as d, with the reciprocal form (1/d) given alongside. All values were computed with the StatsUnlock Berger-Parker dominance index calculator (https://statsunlock.com/tools/berger-parker-dominance-index-calculator) and verified in R.
🔗 20. Related Tools
The Berger-Parker index measures dominance, but a complete community profile usually pairs it with one or more complementary metrics. Use the calculators below to compute Shannon-Wiener diversity, Simpson's diversity, species richness, and evenness on the same dataset:
📖 21. Glossary of Terms
📚 22. References (20 Peer-Reviewed Sources)
The following references support the ecological methods used in this Berger-Parker dominance index calculator, covering dominance measurement, species diversity, and best practice in biodiversity sampling and wildlife analysis.
- Berger, W. H., & Parker, F. L. (1970). Diversity of planktonic foraminifera in deep-sea sediments. Science, 168(3937), 1345–1347. doi.org/10.1126/science.168.3937.1345
- Simpson, E. H. (1949). Measurement of diversity. Nature, 163, 688. doi.org/10.1038/163688a0
- May, R. M. (1975). Patterns of species abundance and diversity. In M. L. Cody & J. M. Diamond (Eds.), Ecology and evolution of communities (pp. 81–120). Harvard University Press.
- Hill, M. O. (1973). Diversity and evenness: A unifying notation and its consequences. Ecology, 54(2), 427–432. doi.org/10.2307/1934352
- Jost, L. (2006). Entropy and diversity. Oikos, 113(2), 363–375. doi.org/10.1111/j.2006.0030-1299.14714.x
- Pielou, E. C. (1966). The measurement of diversity in different types of biological collections. Journal of Theoretical Biology, 13, 131–144. doi.org/10.1016/0022-5193(66)90013-0
- Caruso, T., Pigino, G., Bernini, F., Bargagli, R., & Migliorini, M. (2007). The Berger-Parker index as an effective tool for monitoring the biodiversity of disturbed soils. Biodiversity and Conservation, 16(12), 3277–3285. doi.org/10.1007/s10531-006-9137-3
- Gotelli, N. J., & Colwell, R. K. (2001). Quantifying biodiversity: Procedures and pitfalls in the measurement and comparison of species richness. Ecology Letters, 4(4), 379–391. doi.org/10.1046/j.1461-0248.2001.00230.x
- Chao, A., & Jost, L. (2012). Coverage-based rarefaction and extrapolation: Standardizing samples by completeness rather than size. Ecology, 93(12), 2533–2547. doi.org/10.1890/11-1952.1
- Chao, A., Gotelli, N. J., Hsieh, T. C., et al. (2014). Rarefaction and extrapolation with Hill numbers. Ecological Monographs, 84(1), 45–67. doi.org/10.1890/13-0133.1
- Smith, B., & Wilson, J. B. (1996). A consumer's guide to evenness indices. Oikos, 76(1), 70–82. doi.org/10.2307/3545749
- Whittaker, R. H. (1972). Evolution and measurement of species diversity. Taxon, 21(2/3), 213–251. doi.org/10.2307/1218190
- McNaughton, S. J. (1967). Relationships among functional properties of Californian grassland. Nature, 216, 168–169. doi.org/10.1038/216168b0
- Roswell, M., Dushoff, J., & Winfree, R. (2021). A conceptual guide to measuring species diversity. Oikos, 130(3), 321–338. doi.org/10.1111/oik.07202
- Hsieh, T. C., Ma, K. H., & Chao, A. (2016). iNEXT: An R package for rarefaction and extrapolation of species diversity. Methods in Ecology and Evolution, 7(12), 1451–1456. doi.org/10.1111/2041-210X.12613
- Niedballa, J., Sollmann, R., Courtiol, A., & Wilting, A. (2016). camtrapR: An R package for efficient camera trap data management. Methods in Ecology and Evolution, 7(12), 1457–1462. doi.org/10.1111/2041-210X.12600
- Ahumada, J. A., Silva, C. E. F., Gajapersad, K., et al. (2011). Community structure and diversity of tropical forest mammals: Data from a global camera trap network. Philosophical Transactions of the Royal Society B, 366(1578), 2703–2711. doi.org/10.1098/rstb.2011.0115
- Jost, L. (2007). Partitioning diversity into independent alpha and beta components. Ecology, 88(10), 2427–2439. doi.org/10.1890/06-1736.1
- Hillebrand, H., Bennett, D. M., & Cadotte, M. W. (2008). Consequences of dominance: A review of evenness effects on local and regional ecosystem processes. Ecology, 89(6), 1510–1520. doi.org/10.1890/07-1053.1
- Magurran, A. E., & Henderson, P. A. (2003). Explaining the excess of rare species in natural species abundance distributions. Nature, 422, 714–716. doi.org/10.1038/nature01547