
Simpson's Diversity Index Calculator
A free online tool to measure species diversity with Simpson's index (D, 1-D, and inverse Simpson) from your survey counts, with instant charts and report-ready results.
⚡ 0. Quick Answer
The Simpson's diversity index calculator turns species counts into a diversity value between 0 and 1. Enter counts such as 45, 30, 15, 7, 3 and the tool returns dominance D = 0.321 from D = Σ pi², diversity 1 - D = 0.679, and reciprocal 1/D = 3.12. Higher 1 - D means greater diversity.
🌿 Key Takeaways
- The Simpson's diversity index calculator turns your species counts into a diversity number based on how much the community is dominated by common species.
- You only need the count of individuals per species. Paste them comma separated, upload a CSV file, or type them in.
- It returns three linked values: Simpson's dominance (D), Simpson's index of diversity (1-D), and inverse Simpson (1/D).
- A higher 1-D means greater diversity and less dominance; a value near 0 means one or two species dominate the sample.
- Typical field uses: camera trapping, point counts, vegetation plots, transects, and reef fish surveys.
🌱 1. What Is Simpson's Diversity Index?
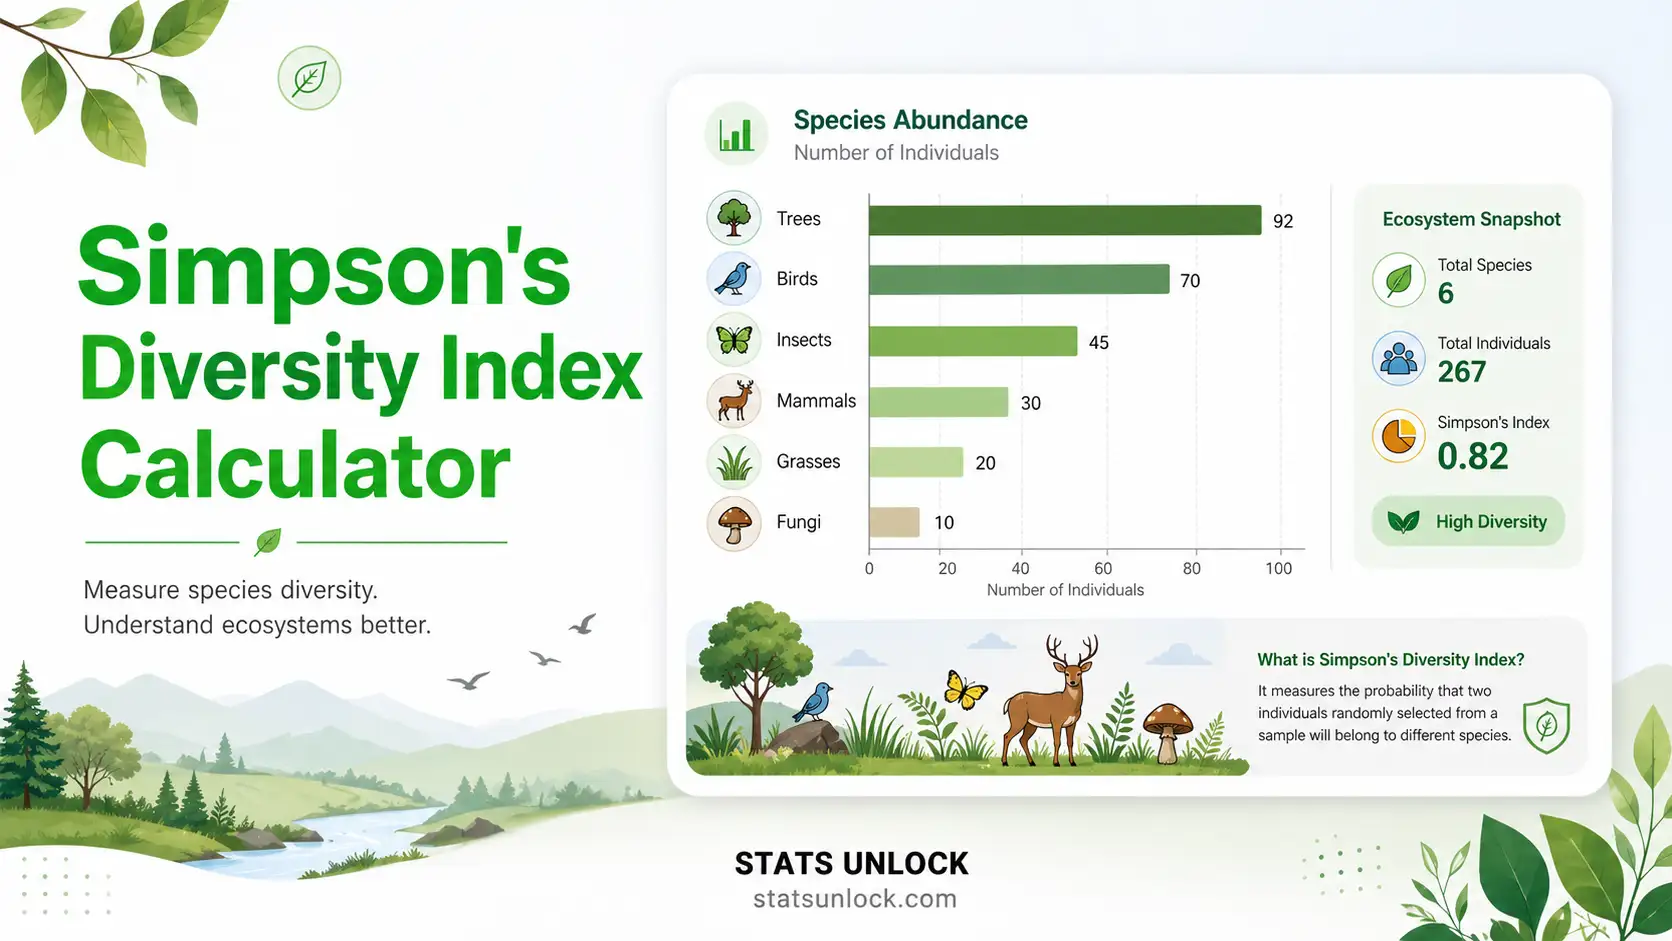
Simpson's diversity index answers one plain question: if you pick two individuals at random from your sample, what is the chance they belong to the same species? That chance is dominance, written D. Subtract it from 1 and you get Simpson's index of diversity, 1 - D, the chance the two individuals are different species.
The number comes from proportions. Divide each species count by the total to get a proportion p, square each one, and add them up. That sum is D. Because D is a probability, it always sits between 0 and 1, which makes Simpson's index easier to explain to a non-specialist than the Shannon index.
Ecologists use it because it is dominated by the common species. A community with one species holding most individuals gets a high D and a low 1 - D, no matter how many rare species are hiding in the tail. That is exactly what you want when the question is about disturbance, invasion, or one species taking over.
1.1 The three numbers people call "Simpson's index"
| Name | Symbol | Range | Reads as |
|---|---|---|---|
| Simpson's dominance | D | 0 to 1 | Higher means one species dominates |
| Simpson's index of diversity | 1 - D | 0 to 1 | Higher means more diverse. This is the one most papers report. |
| Simpson's reciprocal index | 1/D | 1 to S | Effective number of common species |
What to conclude: always say which form you are reporting. "Simpson's index = 0.32" and "Simpson's index = 0.68" can describe the very same community, which is the single most common source of confusion in the literature.
1.2 What the value means
| 1 - D range | Reading | Typical setting |
|---|---|---|
| 0.00 to 0.30 | Very low Concern | Monoculture, one invasive species, heavily polluted water |
| 0.30 to 0.50 | Low Concern | Degraded fragment, intensive farmland, urban core |
| 0.50 to 0.70 | Moderate Watch | Secondary forest, managed grassland, recovering site |
| 0.70 to 0.85 | High Healthy | Mature temperate forest, healthy wetland, good reef transect |
| Above 0.85 | Very high Healthy | Lowland tropical forest, large insect trap samples |
What to conclude: these bands are a first reading only. Compare your value against a reference site sampled with the same method, the same effort, and the same season.
📥 2. Set Up Your Data
0 values entered
🔎 4. Interpretation of Results, In Detail
▶ Run the analysis above to generate a detailed, plain-English interpretation of your Simpson's diversity result.
✍️ 5. How to Write Your Results in Research
▶ Run the analysis above to auto-fill all six examples with your results.
🪧 5.1 Research Poster Panel
A print-ready poster layout that updates with your result. Copy the text or use the visual scaffold for A0 / A1 conference posters.
▶ Run the analysis above to build your poster panel.
🧮 6. Formulas Used
Every number this Simpson's diversity index calculator reports comes from one of the seven formulas below. Card 1 is dominance, and each later card moves one step outward.
Simpson's dominance (the infinite population form)
- D dominance, the chance two random individuals are the same species, unitless
- pi proportion of individuals in species i, unitless
- S number of species in the sample, a count
- Range: 1/S to 1. D = 1 means a single species.
- Example: counts 45, 30, 15, 7, 3 give D = 0.321.
Simpson's index of diversity
- 1 - D the chance two random individuals are different species, 0 to 1
- Rule: this is the form most journals expect. Say so explicitly in your methods.
- Example: 1 - 0.321 = 0.679.
- Note: sometimes written as the Gini-Simpson index.
Simpson's reciprocal index
- 1/D effective number of common species, in species units
- Range: 1 to S. Equals S only when every species is equally common.
- Use for: honest ratios. 1/D of 8 really is twice 1/D of 4.
- Example: 1 / 0.321 = 3.12 effective species out of 5 observed.
The finite sample form (use this for real field data)
- ni count of individuals of species i
- N total individuals across all species
- Requires: whole-number counts, never percentages.
- Example: 3108 / 9900 = 0.314, slightly below the 0.321 the proportion form gives.
- Rule: the two forms converge as N grows. Below about N = 100 the difference matters.
Species proportion
- Rule: all proportions must add to 1.00.
- Note: unlike the Shannon index, a species with a count of 0 causes no error here. It simply contributes nothing.
- Use for: the input to cards 1, 2 and 3.
Simpson's evenness
- E1/D evenness, unitless, 0 to 1
- Range: 1.0 is perfectly even, values under 0.5 mean strong dominance.
- Example: 3.12 / 5 = 0.623.
- Note: this is the Simpson equivalent of Pielou's J'.
Berger-Parker dominance, the quick screen
- nmax count of the single commonest species
- Range: 1/S to 1.
- Example: 45 / 100 = 0.45, so the top species holds 45 percent of individuals.
- Use for: a one-second check on whether dominance is driving your Simpson value.
🧭 7. How to Use This Calculator
Ten steps from a field sheet to a publication-ready Simpson's diversity result.
- Collect standardised counts. Record the number of individuals for each species using the same effort at every site.
- Pick an input tab. Use Paste or Type for a quick run, Upload CSV for a spreadsheet, or Manual Table to key in rows.
- Enter species names and counts. In Column Entry mode, put the species name on the left and the count on the right.
- Or load a sample dataset. Choose one of the built-in field datasets to see how the tool behaves before you use your own data.
- Name your study area. Type the site name into the Study Area box so it appears in every report template and in the poster panel.
- Decide which form you will report. 1 - D is the usual choice. Note it in your methods so nobody misreads your number.
- Set the decimal places. Three decimals is normal for Simpson's index in ecology papers.
- Click Run Analysis. The tool returns D, 1 - D, 1/D, richness, evenness, charts, and a results table.
- Read the interpretation. It explains your number in plain English and flags any sampling problems.
- Copy or download your result. Use the report templates, the poster panel, Download Doc, or Download PDF for your thesis or paper.
📗 8. How to Calculate Simpson's Diversity Index in Excel
Excel, step by step, with the same worked example used everywhere on this page
The worked example below uses five species with counts 45, 30, 15, 7, 3 (N = 100). Excel, R, Python and this calculator all return D = 0.321, 1 - D = 0.679 and 1/D = 3.12 for it.
8.1 The Excel functions you need
| Function | What it does | Example |
|---|---|---|
| SUM | Adds your counts to get N | =SUM(B2:B6) |
| SUMSQ | Squares every value and adds them, giving D in one cell | =SUMSQ(C2:C6) |
| SUMPRODUCT | Builds the finite sample form without a helper column | =SUMPRODUCT(B2:B6,B2:B6-1)/(B7*(B7-1)) |
| COUNTIF | Counts species with a count above zero, giving S | =COUNTIF(B2:B6,">0") |
| MAX | Finds the commonest species for Berger-Parker | =MAX(B2:B6)/B7 |
| ROUND | Displays three decimals without losing precision upstream | =ROUND(D7,3) |
What to conclude: SUMSQ is the shortcut nobody teaches. It replaces an entire squared-proportion column with one cell.
8.2 Step by step in the sheet
Step 1. Type your data and total the counts
Species names go in column A, counts in column B. Cell B7 holds =SUM(B2:B6), which returns N = 100.
Step 2. Turn each count into a proportion
C2 holds =B2/$B$7 and returns 0.45. The dollar signs lock the total so the formula fills down correctly to C6. Column C now adds to 1.00.
Step 3. Square every proportion
D2 holds =C2^2 and returns 0.2025. Squaring is what makes Simpson's index lean on the common species: 0.45 squared is 0.2025, but 0.03 squared is only 0.0009.
Step 4. Add the squares and read all three forms
D7 holds =SUM(D2:D6) and returns D = 0.3208. Diversity is =1-D7 = 0.6792 and the reciprocal is =1/D7 = 3.117. Column E shows =B2*(B2-1) for the finite sample version.
8.3 The awkward cases
| Case | What breaks | Fix |
|---|---|---|
| A species with a count of 0 | Nothing breaks, but it inflates your species count S | Delete the row, or use =COUNTIF(B2:B6,">0") for S |
| Only one species present | 1/D returns 1 and 1 - D returns 0 | That is correct. A single species has zero diversity. |
| Counts entered as percentages | The finite sample form returns a meaningless value | Go back to the raw counts, or use the proportion form only |
| Text mixed into the count column | SUM ignores it silently, so N is wrong | Check N by eye against =COUNT(B2:B6) |
| Duplicate species rows | The same species is split in two, lowering D | Use a PivotTable to sum counts by species name first |
What to conclude: Simpson's index is more forgiving than Shannon's because zeros do not throw errors. That makes silent mistakes easier to miss, so check N every time.
8.4 Why answers differ between Excel, R and Python
The usual cause is not software, it is which form was reported. R's vegan returns 1 - D by default when you ask for "simpson", and "invsimpson" for 1/D. Python's skbio returns 1 - D as well. If your Excel sheet stops at =SUMSQ, you are holding D, not 1 - D, and the two look nothing alike. The second cause is the finite sample correction: this page's worked example gives 0.3208 with proportions and 0.3139 with the n(n-1) form. Both are correct; state which you used. Rounding proportions to two decimals before squaring is the third cause, and it can shift the third decimal.
8.5 Charting the result in Excel
- Relative abundance pie. Select columns A and C, then Insert, Pie chart. Simpson's index is a dominance measure, so the pie is the honest picture of it.
- Contribution bar chart. Chart column D. The tallest bar is the species driving your D value, which is usually the sentence a reviewer wants.
- Site comparison bars. One 1 - D value per site in a column, then a clustered bar chart with the axis fixed from 0 to 1.
- Label the axis properly. Write "Simpson's 1 - D" on the value axis, never just "Simpson's index".
8.6 Excel error messages and what they mean
| Message | Cause | Fix |
|---|---|---|
| #DIV/0! | N is zero, or D is zero in the 1/D cell | Check the SUM range covers every data row |
| #VALUE! | Text inside a numeric range | Clear notes such as "none seen" from the count column |
| #NUM! | A negative count reached the squaring step | Counts cannot be negative. Re-check data entry. |
| Result is exactly 1 | You calculated D for a single-species sample | Correct, but report 1 - D = 0 rather than D = 1 |
| Result is above 1 | Percentages were used with the finite sample form | Switch to raw counts |
| 1/D is smaller than 1 | D was entered above 1 | Impossible value. Recheck the proportion column adds to 1.00. |
What to conclude: any Simpson value outside 0 to 1 is a data problem, not an ecological finding.
📘 9. How to Calculate Simpson's Diversity Index in R
R, one complete script you can run top to bottom
9.1 The complete script
Copy this into RStudio and press Run. It needs no packages. Change only the counts line. It prints all three Simpson forms and saves one 300 dpi figure.
# ------------------------------------------------------------------
# Simpson's Diversity Index in R
# StatsUnlock.com - free ecology and wildlife analysis tools
# ------------------------------------------------------------------
set.seed(42)

# 1. YOUR DATA -- change only this line
counts <- c(45, 30, 15, 7, 3)
species <- c("Bulbul", "Babbler", "Sunbird", "Barbet", "Drongo")

# Reading from a file instead? Uncomment the two lines below.
# dat <- read.csv("my_survey.csv")          # columns: species, count
# counts <- dat$count; species <- dat$species

# 2. CLEAN THE DATA
counts[is.na(counts)] <- 0        # missing values become zero
keep <- counts > 0                # zero counts add nothing, drop them
counts <- counts[keep]
species <- species[keep]

# 3. CALCULATE
N <- sum(counts)                          # total individuals
S <- length(counts)                       # species richness
p <- counts / N                           # proportions
D <- sum(p^2)                             # Simpson's dominance
div <- 1 - D                              # Simpson's index of diversity
inv <- 1 / D                              # Simpson's reciprocal index
D_finite <- sum(counts * (counts - 1)) / (N * (N - 1))   # finite sample form
even <- inv / S                           # Simpson's evenness
bp <- max(counts) / N                     # Berger-Parker dominance

# Same answers using the vegan package:
# install.packages("vegan")
# library(vegan)
# vegan::diversity(counts, index = "simpson")      # returns 1 - D
# vegan::diversity(counts, index = "invsimpson")   # returns 1 / D

# 4. PRINT A PLAIN-ENGLISH VERDICT
verdict <- if (div >= 0.70) "high diversity" else if (div >= 0.50) "moderate diversity" else "low diversity"
cat("Dominance D             :", round(D, 3), "\n")
cat("Simpson 1 - D           :", round(div, 3), "\n")
cat("Reciprocal 1/D          :", round(inv, 3), "\n")
cat("Finite sample D         :", round(D_finite, 3), "\n")
cat("Species richness S      :", S, "\n")
cat("Total individuals N     :", N, "\n")
cat("Simpson evenness        :", round(even, 3), "\n")
cat("Berger-Parker d         :", round(bp, 3), "\n")
cat("Verdict                 :", verdict, "\n")

# 5. SAVE ONE 300 dpi FIGURE
png("simpson_contribution.png", width = 1800, height = 1200, res = 300)
ord <- order(p^2, decreasing = TRUE)
barplot(p[ord]^2,
        names.arg = species[ord],
        col = "#3aab6d", border = NA, las = 2,
        ylab = "Contribution to D (p squared)",
        main = paste0("What drives D, 1 - D = ", round(div, 3)))
dev.off()
cat("Figure saved as simpson_contribution.png\n")
9.2 What each line does
| Line | What it does |
|---|---|
| set.seed(42) | Fixes anything random so your figure is reproducible. |
| counts <- c(45, 30, ...) | Your species counts. This is the only line most users change. |
| keep <- counts > 0 | Drops zero counts. They add nothing to D, but they inflate S. |
| p <- counts / N | Converts counts to proportions that add to 1.00. |
| D <- sum(p^2) | Simpson's dominance. The core of the whole index. |
| div <- 1 - D | Simpson's index of diversity, the form most papers report. |
| inv <- 1 / D | Simpson's reciprocal index, the effective number of common species. |
| D_finite <- sum(counts * (counts - 1)) / (N * (N - 1)) | The finite sample form. Use it when N is small. |
| diversity(x, "simpson") | The vegan one-liner. It returns 1 - D, not D. This trips people up constantly. |
| diversity(x, "invsimpson") | The vegan call for 1/D. |
| dev.off() | Closes the device and writes the file. Forget this and the PNG stays empty. |
9.3 What the figure shows
The script saves a contribution chart: each species plotted by its squared proportion, sorted largest first. This is the most useful figure for Simpson's index, because it names the species responsible for your D value. In the worked example the first bar alone (0.2025) is nearly two thirds of D = 0.3208, which tells the whole story in one glance.
9.4 Problems and fixes
| Problem | Cause | Fix |
|---|---|---|
| vegan gives 0.679 but my sheet gives 0.321 | vegan returns 1 - D, your sheet returned D | Both are right. Decide which form you report and be consistent. |
| Error: could not find function "diversity" | vegan is not loaded | Run install.packages("vegan") then library(vegan) |
| 1/D returns Inf | D is zero, which needs an empty sample | Check that counts holds at least one positive value |
| Value changes when I add rare species | Expected. Simpson's index barely moves for rare species. | If rare species matter, report richness or the Shannon index too |
| Empty PNG file | dev.off() was never called | Run dev.off() once, then re-run the plotting block |
| Finite form differs from vegan | vegan uses the proportion form | Expected below N = 100. State which form you used. |
9.5 One-liners worth keeping
| Code | Returns |
|---|---|
| vegan::diversity(x, "simpson") | 1 - D from a count vector or a site-by-species matrix |
| vegan::diversity(x, "invsimpson") | 1/D, the reciprocal index |
| 1 - vegan::diversity(x, "simpson") | D, the dominance form |
| vegan::specnumber(x) | Species richness S |
| max(x)/sum(x) | Berger-Parker dominance |
| iNEXT::iNEXT(x, q = 2) | Rarefaction and extrapolation for Hill number q = 2, which equals 1/D |
🐍 10. How to Calculate Simpson's Diversity Index in Python
Python, one complete script you can run top to bottom
10.1 The complete script
Save this as simpson.py and run it. Change only the counts line. It prints all three Simpson forms and saves one 300 dpi figure.
# ------------------------------------------------------------------
# Simpson's Diversity Index in Python
# StatsUnlock.com - free ecology and wildlife analysis tools
# ------------------------------------------------------------------
import numpy as np
import matplotlib
matplotlib.use("Agg")
import matplotlib.pyplot as plt

np.random.seed(42)

# 1. YOUR DATA -- change only this line
counts = np.array([45, 30, 15, 7, 3], dtype=float)
species = ["Bulbul", "Babbler", "Sunbird", "Barbet", "Drongo"]

# Reading from a file instead? Uncomment the three lines below.
# import pandas as pd
# dat = pd.read_csv("my_survey.csv")          # columns: species, count
# counts, species = dat["count"].to_numpy(float), dat["species"].tolist()

# 2. CLEAN THE DATA
counts = np.nan_to_num(counts, nan=0.0)       # missing values become zero
keep = counts > 0                             # zero counts add nothing
species = [s for s, k in zip(species, keep) if k]
counts = counts[keep]

# 3. CALCULATE
N = counts.sum()                              # total individuals
S = counts.size                               # species richness
p = counts / N                                # proportions
D = float(np.sum(p ** 2))                     # Simpson's dominance
div = 1 - D                                   # Simpson's index of diversity
inv = 1 / D                                   # Simpson's reciprocal index
D_finite = float(np.sum(counts * (counts - 1)) / (N * (N - 1)))   # finite sample
even = inv / S                                # Simpson's evenness
bp = float(counts.max() / N)                  # Berger-Parker dominance

# Same answer using scikit-bio:
# from skbio.diversity.alpha import simpson
# div = simpson(counts.astype(int))    # returns 1 - D

# 4. PRINT A PLAIN-ENGLISH VERDICT
verdict = "high diversity" if div >= 0.70 else "moderate diversity" if div >= 0.50 else "low diversity"
print(f"Dominance D             : {D:.3f}")
print(f"Simpson 1 - D           : {div:.3f}")
print(f"Reciprocal 1/D          : {inv:.3f}")
print(f"Finite sample D         : {D_finite:.3f}")
print(f"Species richness S      : {S}")
print(f"Total individuals N     : {N:.0f}")
print(f"Simpson evenness        : {even:.3f}")
print(f"Berger-Parker d         : {bp:.3f}")
print(f"Verdict                 : {verdict}")

# 5. SAVE ONE 300 dpi FIGURE
contrib = p ** 2
order = np.argsort(contrib)[::-1]
fig, ax = plt.subplots(figsize=(6, 4))
ax.bar([species[i] for i in order], contrib[order], color="#3aab6d")
ax.set_ylabel("Contribution to D (p squared)")
ax.set_title(f"What drives D, 1 - D = {div:.3f}")
plt.xticks(rotation=45, ha="right")
plt.tight_layout()
plt.savefig("simpson_contribution.png", dpi=300)
print("Figure saved as simpson_contribution.png")
10.2 What each line does
| Line | What it does |
|---|---|
| matplotlib.use("Agg") | Draws without a screen, so the script runs on a server or in a notebook. |
| counts = np.array([...]) | Your species counts. The only line most users change. |
| np.nan_to_num(counts) | Turns missing values into zero so the script does not stop. |
| keep = counts > 0 | Drops zero counts, which add nothing to D but inflate S. |
| p = counts / N | Converts counts to proportions that add to 1.00. |
| D = np.sum(p ** 2) | Simpson's dominance. |
| div = 1 - D | Simpson's index of diversity, the form most papers report. |
| inv = 1 / D | Simpson's reciprocal index. |
| D_finite = ...(counts - 1)... | The finite sample form, for small N. |
| skbio ... simpson(counts) | The scikit-bio one-liner. It returns 1 - D and needs integer counts. |
| plt.savefig(..., dpi=300) | Writes the 300 dpi figure most journals ask for. |
10.3 What the figure shows
The saved PNG plots each species by its contribution to D, sorted largest first, identical in meaning to the R figure. If one bar towers over the rest, dominance is driving your result and 1 - D will be low. For a relative abundance pie instead, swap ax.bar for ax.pie(p, labels=species).
10.4 Problems and fixes
| Problem | Cause | Fix |
|---|---|---|
| ImportError: cannot import simpson | scikit-bio is not installed, or the name changed between versions | Use the manual NumPy line, which needs no extra package |
| scipy.stats has no simpson for diversity | scipy.integrate.simpson is numerical integration, not diversity | Do not use it. Calculate D with NumPy directly. |
| Result is 0.321 not 0.679 | You printed D rather than 1 - D | Report div, and say which form in your methods |
| ZeroDivisionError on 1/D | Every count was filtered out | Check the array is not empty after the keep filter |
| Integer division gives zeros | Counts stored as int in old Python code | Keep dtype=float in the array line |
| Figure window never opens | The Agg backend has no screen output | That is expected. Open the saved PNG file. |
10.5 One-liners worth keeping
| Code | Returns |
|---|---|
| 1 - np.sum((c/c.sum())**2) | Simpson's 1 - D, no packages beyond NumPy |
| 1 / np.sum((c/c.sum())**2) | Simpson's reciprocal index 1/D |
| np.sum(c*(c-1))/(c.sum()*(c.sum()-1)) | The finite sample dominance D |
| skbio.diversity.alpha.simpson(c) | 1 - D from scikit-bio, integer counts only |
| c.max()/c.sum() | Berger-Parker dominance |
| (c > 0).sum() | Species richness S |
📋 11. Reference Tables
Six lookup tables for reading, converting, and sanity-checking a Simpson's diversity index value.
Table 11.1 Published 1 - D values by habitat type
| Habitat | Taxon | Typical 1 - D | Typical S |
|---|---|---|---|
| Lowland tropical rainforest | Birds | 0.90 to 0.96 | 40 to 120 |
| Dry deciduous forest | Birds | 0.82 to 0.92 | 25 to 50 |
| Temperate woodland | Birds | 0.78 to 0.88 | 15 to 35 |
| Grassland, managed | Plants | 0.65 to 0.85 | 10 to 30 |
| Wetland, freshwater | Waterbirds | 0.72 to 0.88 | 12 to 40 |
| Coral reef transect | Fish | 0.85 to 0.94 | 30 to 80 |
| Camera trap grid | Large mammals | 0.60 to 0.82 | 6 to 20 |
| Urban park | Birds | 0.55 to 0.80 | 8 to 20 |
| Intensive cropland | Arthropods | 0.45 to 0.75 | 5 to 20 |
| Polluted stream | Macroinvertebrates | 0.15 to 0.55 | 3 to 10 |
What to conclude: Simpson values cluster high and compress at the top. A jump from 0.90 to 0.94 is a bigger ecological change than it looks, which is why the reciprocal form is easier to compare.
Table 11.2 Converting between the three Simpson forms
| D (dominance) | 1 - D (diversity) | 1/D (reciprocal) | Reading |
|---|---|---|---|
| 1.000 | 0.000 | 1.00 | One species only |
| 0.800 | 0.200 | 1.25 | Extreme dominance |
| 0.500 | 0.500 | 2.00 | Strong dominance |
| 0.321 | 0.679 | 3.12 | The worked example on this page |
| 0.250 | 0.750 | 4.00 | Moderate |
| 0.200 | 0.800 | 5.00 | High |
| 0.100 | 0.900 | 10.00 | Very high |
| 0.050 | 0.950 | 20.00 | Exceptional |
| 0.020 | 0.980 | 50.00 | Large, very even sample |
What to conclude: 1 - D changes very little between 0.95 and 0.98, while 1/D doubles from 20 to 50. For comparing sites, report 1/D as well.
Table 11.3 Maximum possible diversity for a given richness
| Species richness S | Minimum D (all equal) | Maximum 1 - D | Maximum 1/D |
|---|---|---|---|
| 2 | 0.500 | 0.500 | 2 |
| 5 | 0.200 | 0.800 | 5 |
| 10 | 0.100 | 0.900 | 10 |
| 20 | 0.050 | 0.950 | 20 |
| 50 | 0.020 | 0.980 | 50 |
| 100 | 0.010 | 0.990 | 100 |
What to conclude: 1/D can never exceed S. If your reported 1/D is larger than your species count, you have a calculation error.
Table 11.4 Reading Simpson's evenness
| E = (1/D) / S | Reading | What it usually means |
|---|---|---|
| 0.90 to 1.00 | Very even Healthy | No species dominates. Common in stable systems. |
| 0.75 to 0.90 | Even Healthy | A normal, balanced community. |
| 0.60 to 0.75 | Moderate Watch | Two or three species carry most individuals. |
| 0.40 to 0.60 | Uneven Watch | Clear dominance. Check for disturbance or an aggregation. |
| Below 0.40 | Very uneven Concern | One species takes over. Often invasion or pollution. |
What to conclude: the worked example scores 0.623, moderate. Two species out of five hold three quarters of the individuals.
Table 11.5 Minimum sampling effort by survey type
| Survey type | Minimum effort for a usable 1 - D | Preferred effort |
|---|---|---|
| Bird point counts | 10 points, 30 individuals | 30 points across 3 visits |
| Line transects | 2 km walked | 10 km, repeated in 2 seasons |
| Camera trapping | 300 trap nights | 1,000 to 2,000 trap nights |
| Vegetation quadrats | 10 quadrats of 1 m² | 30 quadrats, stratified by habitat |
| Pitfall traps | 20 trap days | 100 trap days across 5 stations |
| Reef fish belt transects | 4 transects of 50 m | 12 transects across 3 depths |
| Light trap insects | 3 trap nights | 12 trap nights across the season |
What to conclude: Simpson's index needs less effort than the Shannon index to stabilise, because it depends on the common species. That is one of its real advantages.
Table 11.6 Which diversity index to report
| Index | Weights | Range | Best used when |
|---|---|---|---|
| Simpson's 1 - D | Common species | 0 to 1 | Dominance is the story, or the sample is small |
| Simpson's 1/D | Common species | 1 to S | You need a comparable ratio between sites |
| Shannon Wiener H' | Rare species | 0 to ~4.6 | You want richness and evenness balanced in one number |
| Species richness S | All equally | 1 upward | Presence lists only, no reliable counts |
| Pielou's J' | Evenness only | 0 to 1 | Comparing communities with different richness |
| Berger-Parker | The single commonest species | 0 to 1 | Quick screening for one dominant species |
| Hill numbers | Tunable by q | 1 upward | You need a true diversity ratio. 1/D is Hill q = 2. |
What to conclude: most reviewers expect Simpson plus one companion index. Simpson with Shannon is the safest pair, because one leans on common species and the other on rare ones.
📊 12. Example Results
Scenario 1: High-diversity tropical forest
A bird survey records 28 species and 412 individuals with fairly even counts. Simpson's 1-D works out to about 0.95. This high value means two random birds are almost always different species, typical of an intact community.
Scenario 2: Disturbed, degraded site
A logged fragment holds 6 species and 200 individuals, but one species makes up 150 of them. Simpson's 1-D drops to about 0.42. The low value reflects strong dominance and reduced ecological integrity.
Scenario 3: Same richness, different evenness
Two plots each have 5 species. Plot A counts 20,20,20,20,20 (1-D = 0.80); Plot B counts 80,5,5,5,5 (1-D = 0.35). Same richness, very different diversity, Simpson's index reacts strongly to the dominant species.
Scenario 4: Before vs after restoration
A grassland plot rises from 1-D = 0.55 before management to 1-D = 0.78 three years after invasive removal, showing recovering evenness as native species return.
Scenario 5: Camera-trap mammal survey
Across 1,400 trap nights, 8 mammal species are detected with counts 40,35,30,25,20,15,10,5. Simpson's 1-D = 0.83, a fairly high value for a mid-sized mammal community in a wildlife corridor.
Scenario 6: Edge case / caution
Only 3 individuals across 3 species gives 1-D = 1.00, but the sample is far too small to trust. Always collect at least 30 individuals before reporting a Simpson's value.
Scenario 7: Where 1 - D flattens and 1/D does not
Site X scores 1 - D = 0.95 and Site Y scores 1 - D = 0.98. The gap looks trivial. In reciprocal form they are 20.0 and 50.0 effective species, a two and a half times difference. This is why rich communities should always be compared with 1/D.
Scenario 8: The worked example used in Sections 8, 9 and 10
Five species with counts 45, 30, 15, 7, 3 give N = 100, S = 5, D = 0.321, 1 - D = 0.679, 1/D = 3.12, Simpson evenness 0.623 and Berger-Parker 0.45. The finite sample form gives D = 0.314. Excel, R, Python and this calculator all agree, so use this dataset to check your own setup.
🥾 13. How to Collect Raw Data in the Field
Simpson's index is only as good as the counts you feed it. Follow these ready-to-use steps in the field to collect clean, comparable species abundance data. Print this list and take it with you.
- Define your question first. Decide what you are comparing (site vs site, season vs season, before vs after) before you collect a single count.
- Pick one taxonomic group and stick to it. Count only birds, only trees, or only mammals. Mixing groups makes the index meaningless.
- Choose a standard sampling method and use it everywhere: point counts, line transects, quadrats, camera traps, pitfall traps, or mist nets.
- Fix your sampling effort. Keep the same transect length, plot size, count duration, or number of trap nights at every site.
- Set a minimum sample. Aim for at least 30 individuals and several species; small samples give unstable Simpson's values.
- Use replicates. Place at least 3 stations, plots, or transects per site so you can estimate variation.
- Mark station locations with GPS so the exact spot can be resurveyed in future years.
- Record every individual, not just species presence. Simpson's index needs abundance counts, not a checklist.
- Count during a consistent time window and avoid rain, high wind, or extreme heat.
- Avoid double-counting. Move in one direction, note flying birds separately, and use a set detection radius.
- Log detection method (seen, heard, trapped, photographed) for later corrections.
- Identify to species where possible. If you cannot, use a consistent morphospecies label and keep it identical across sheets.
- Use a prepared datasheet. Columns: Date, Site, Station, Observer, Species, Count, Detection type, Notes.
- Record effort metadata on every sheet: start and end time, weather, observer name, and equipment used.
- Photograph or voucher tricky species to settle identification disputes back at the desk.
- Enter counts as whole numbers, not percentages or densities.
- Back up your data the same day by photographing paper sheets or typing counts into a spreadsheet.
- Keep a field notebook for disturbance, human activity, unexpected species, or equipment problems.
- Sum counts per species before entry, then paste the per-species totals into this calculator (for example
52, 48, 55, 61, 47). - Never invent or round zeros away. A species absent from the sample is simply not listed.
🎯 14. When to Use This Tool
14.1 Quick decision checklist
- ✅ You have counts of individuals per species, not just a species list.
- ✅ Your question is about dominance: is one species taking over?
- ✅ Your sample is modest in size. Simpson's index is more stable than Shannon's at low N.
- ✅ You need a number between 0 and 1 that a non-specialist audience can read.
- ❌ Rare species are the point of your study. Simpson's index barely notices them.
- ❌ You only know which species were present. Use species richness instead.
- ❌ Effort differs a lot between sites and cannot be standardised. Rarefy first.
14.2 Four real situations
| Situation | What you do | What 1 - D tells you |
|---|---|---|
| Tracking an invasive plant in a grassland | Same quadrats each year, counts per species | Whether one species is squeezing out the rest, the exact thing Simpson detects best |
| Water quality monitoring on a stream | Kick samples above and below a discharge | Whether pollution-tolerant species now dominate downstream |
| Reporting a small pilot survey | 60 individuals, 8 species, one season | A stable estimate where the Shannon index would still be climbing with effort |
| Explaining biodiversity to a council or landowner | Any standardised count | A plain probability: the chance two animals picked at random are different species |
14.3 Sampling design guidance
- Fix effort first. Decide trap nights, transect length, or quadrat count before you start, and keep it identical at every site.
- Replicate within sites. Three or more stations per site let you report a mean with a standard error rather than a bare number.
- Randomise or stratify placement. Placing stations where you expect wildlife inflates the common species and drags D upward.
- Hold the season constant. Dominance swings with breeding, migration, and flowering. Compare like with like.
- Use the finite sample form for small N. Below about 100 individuals it is the more honest estimate.
14.4 Which metric next
- Want rare species to count? Go to the Shannon Wiener index.
- Want a fair ratio, for example "twice as diverse"? Report 1/D, which is Hill number q = 2.
- Only care about the single commonest species? Use Berger-Parker.
- Sample sizes differ? Use rarefaction or Margalef's index.
- Comparing species turnover between sites? Use beta diversity, not Simpson's index.
🛠️ 15. Troubleshooting and Common Errors
Ten problems users hit with Simpson's diversity index, and how to fix each one.
My value is 0.32 but the paper I am copying reports 0.68
Cause: you calculated D, they reported 1 - D. Fix: both describe the same community. Subtract from 1, and always state which form you are reporting in your methods. This is by far the most common Simpson's index error.
My 1 - D is 0
Cause: only one species has a count above zero. Fix: nothing to fix. A single-species sample genuinely has zero diversity. Check that no species were lost during data entry.
My value is above 1
Cause: percentages were used with the finite sample formula, or the proportions do not add to 1.00. Fix: D, 1 - D and every proportion must sit between 0 and 1. Go back to raw counts.
1/D is larger than my number of species
Cause: a calculation error. Fix: 1/D can never exceed S. Check that your proportion column sums to exactly 1.00 and that no row is a total row.
Adding ten rare species barely changed my result
Cause: that is how Simpson's index works. Squaring the proportions crushes small values: 0.01 squared is 0.0001. Fix: if rare species matter to your question, report species richness or the Shannon index alongside.
The finite sample form gives a different answer
Cause: expected. The proportion form assumes an infinite population; the n(n-1) form corrects for a finite sample. Fix: use the finite form when N is below about 100, and say which you used.
R's vegan does not match my spreadsheet
Cause: vegan::diversity(x, "simpson") returns 1 - D, and it uses the proportion form. Fix: compare like with like. For D, use 1 - vegan::diversity(x, "simpson").
The tool says invalid input
Cause: text, symbols, or negative numbers in the count list. Fix: keep only whole numbers separated by commas, spaces, tabs, or new lines. Replace notes such as "none seen" with 0.
Two sites have the same 1 - D but look different
Cause: richness and evenness can trade off, and Simpson's index compresses at the top of its range. Fix: report S, 1/D and 1 - D together. The reciprocal form separates sites that 1 - D flattens.
Charts do not appear after I click Run
Cause: the Chart.js library was blocked by a network filter or an offline device. Fix: reload the page on a normal connection. The numbers and the results table still work without charts.
⚠️ 16. Assumptions and Limitations
Simpson's diversity index is robust and easy to explain, but it answers a narrower question than people assume. These are the conditions it relies on, and the things it cannot tell you.
16.1 What the index assumes
- Individuals were sampled at random from the community.
- All species had a fair chance of being detected. Shy or nocturnal species break this.
- Every individual was identified to the same taxonomic level.
- Counts are of individuals, not biomass, cover, or percentages.
- Each record is independent. Ten photographs of one animal in one minute is one detection.
- For the finite sample form, counts are whole numbers and N is the true total.
16.2 What it cannot tell you
- Which species are present. Two sites with no species in common can score the same 1 - D.
- Anything much about rare species. Squaring the proportions all but erases them.
- Whether the species are native, threatened, or invasive. The index treats all species as equal.
- Whether a difference between sites is statistically significant. That needs replicates and a test.
- Population size or trend. Use density, occupancy, or abundance estimates for that.
16.3 The four limitations reviewers raise most
| Limitation | Why it matters | What to do |
|---|---|---|
| Compression at the top | Rich sites all cluster between 0.90 and 0.99, hiding real differences | Report 1/D as well, which spreads them out |
| Three forms, one name | Readers cannot tell D from 1 - D from 1/D without being told | Name the form explicitly in the methods and in every table caption |
| Blind to rare species | Losing half your rare species may not move the index at all | Pair it with richness or the Shannon index |
| Detection bias | Cryptic species are systematically missed, inflating apparent dominance | Use occupancy models, or state the bias openly |
What to conclude: report 1 - D as one line of evidence, with richness, 1/D, effort, and a species list beside it. On its own it is a summary, not a conclusion.
🔍 17. Conclusion
❓ 18. Frequently Asked Questions
What is Simpson's diversity index and when should I use it?
Simpson's diversity index measures the chance that two individuals picked at random from a sample belong to different species. Use it when your question is about dominance, when your sample is small, or when you need a number between 0 and 1 that a non-specialist can understand.
How do you calculate Simpson's diversity index step by step?
Divide each species count by the total to get a proportion p. Square each proportion. Add the squares together to get dominance D. Subtract from 1 for the diversity form. With counts 45, 30, 15, 7, 3 the squares sum to 0.321, so 1 - D = 0.679.
What is the difference between D, 1-D and 1/D?
D is dominance, the chance two individuals match, and higher means less diverse. 1 - D is Simpson's index of diversity, and higher means more diverse. 1/D is the reciprocal index, the effective number of common species. For the example above they are 0.321, 0.679 and 3.12.
What is the Excel formula for Simpson's diversity index?
Use =1-SUMSQ(B2:B6)/SUM(B2:B6)^2 to get 1 - D straight from raw counts in one cell. For the finite sample form use =SUMPRODUCT(B2:B6,B2:B6-1)/(B7*(B7-1)) where B7 holds the total. SUMSQ is the function most tutorials miss.
How do I calculate Simpson's index in R?
Base R needs one line: D <- sum(p^2), where p is counts divided by their total. The package version is vegan::diversity(counts, index = "simpson"), which returns 1 - D, not D. Use index = "invsimpson" for the reciprocal form.
Which Python package calculates Simpson's diversity index?
scikit-bio has skbio.diversity.alpha.simpson(), which returns 1 - D from integer counts. SciPy has no diversity function, so most people use NumPy directly: 1 - np.sum((c/c.sum())**2). Do not confuse it with scipy.integrate.simpson, which is numerical integration.
What is a good Simpson's diversity index value?
There is no universal cutoff. Values of 1 - D above 0.85 are high, 0.70 to 0.85 is healthy for most temperate systems, 0.50 to 0.70 is moderate, and below 0.50 suggests strong dominance. Always compare against a reference site sampled the same way.
What data do I need to calculate Simpson's diversity index?
You need the count of individuals for each species in your sample. Paste them comma separated, upload a CSV file, or type them into the grid. Whole numbers are required for the finite sample form. Aim for at least 30 individuals.
What does a high Simpson's index mean?
It depends on which form. A high 1 - D means high diversity, with individuals spread across many species. A high D means the opposite, with one or two species dominating. This is why naming the form in your methods matters more for Simpson than for any other index.
Simpson's index vs Shannon index, which should I use?
Simpson weights common species and is stable at small sample sizes. Shannon weights rare species and is more sensitive to richness. Report both when you can. If your question is about one species taking over, Simpson answers it better.
Why does Simpson's index ignore rare species?
Because it squares the proportions. A species holding 45 percent of individuals contributes 0.2025 to D, while one holding 1 percent contributes 0.0001. Squaring crushes small values, which is a design feature, not a flaw.
When should I use the finite sample formula?
Use D = Σ n(n-1) / [N(N-1)] when your total sample is below roughly 100 individuals. It corrects for the fact that you are sampling without replacement. Above N = 200 the two forms agree to three decimals.
Does sample size affect Simpson's diversity index?
Less than it affects the Shannon index. Because it depends on the common species, Simpson's index stabilises after relatively few individuals. It still rises slightly with effort, so standardise effort across sites before comparing.
Can I compare Simpson's index between sites or seasons?
Yes, when effort, protocol, taxonomic group and season are comparable. Report 1/D as well as 1 - D, because 1 - D compresses at the top of its range and can hide real differences between species-rich sites.
How do I report Simpson's diversity index in a paper?
Name the form, give the value, and add richness and sample size, for example: Simpson's index of diversity 1 - D = 0.679 (S = 5 species, N = 100 individuals). State whether you used the proportion form or the finite sample form.
What are the assumptions and limitations of Simpson's index?
It assumes a random, representative sample with standardised effort and correct identification. It cannot tell you which species are present, whether they are native or threatened, or anything useful about rare species.
What is the Gini-Simpson index?
It is another name for 1 - D, Simpson's index of diversity. The same quantity appears in economics as the Gini impurity and in machine learning as a splitting criterion, which is why the name travels between fields.
What is the inverse Simpson index used for?
1/D gives the effective number of common species, so it behaves like a species count. A site with 1/D of 10 really is twice as diverse as one with 5, which is not true of 1 - D. It is also Hill number q = 2.
Why does my Simpson's index not match my supervisor's?
Almost always because one of you reported D and the other reported 1 - D. The second most common cause is the finite sample correction. Compare the raw counts and the formula used before assuming either value is wrong.
Is this Simpson's diversity index calculator free and accurate?
Yes. It is completely free, runs entirely in your browser, stores no data, and uses the published Simpson formulas in all three forms. Results are cross-checked against R's vegan package and Python, and match to three decimal places.
📝 19. Cite This Tool
Use one of these three formats when you mention this Simpson's diversity index calculator in a thesis, report, or paper.
APA 7th edition
StatsUnlock. (2026). Simpson's diversity index calculator: Free online ecology tool [Computer software]. https://statsunlock.com/simpsons-diversity-index-calculator/
BibTeX
@misc{statsunlock_simpson_2026,
  title        = {Simpson's Diversity Index Calculator: Free Online Ecology Tool},
  author       = {{StatsUnlock}},
  year         = {2026},
  howpublished = {\url{https://statsunlock.com/simpsons-diversity-index-calculator/}},
  note         = {Accessed: 2026-09-15}
}
Methods paragraph
Species diversity was summarised using Simpson's index (Simpson, 1949; Magurran, 2004). Dominance was calculated as D = Σ p², where p is the proportion of individuals belonging to each species, and results are reported as Simpson's index of diversity (1 - D) together with the reciprocal form (1/D). All indices were computed with the StatsUnlock Simpson's diversity index calculator (https://statsunlock.com/simpsons-diversity-index-calculator/) and verified in R with vegan::diversity().
🔗 20. Related Tools
Free ecology and wildlife calculators that pair well with Simpson's diversity index.
The companion index. It weights rare species, where Simpson weights common ones. Report both.
Separates evenness from richness when two sites share the same 1 - D.
Puts 1/D on a common scale with richness and the Shannon index. 1/D is Hill q = 2.
Turns raw counts into the proportions the Simpson formula squares.
A richness measure that is less sensitive to sample size.
Turns photo detections and trap nights into the standardised counts this tool needs.
📖 21. Glossary of Terms
📚 22. References (20 Peer-Reviewed Sources)
The following references support the ecological methods used in this Simpson's diversity index calculator, covering biodiversity measurement, species diversity, and best practices in ecological sampling and wildlife analysis.
- Simpson, E. H. (1949). Measurement of diversity. Nature, 163, 688. doi.org/10.1038/163688a0
- Shannon, C. E., & Weaver, W. (1949). The mathematical theory of communication. University of Illinois Press.
- Magurran, A. E. (2004). Measuring biological diversity. Blackwell Publishing.
- Krebs, C. J. (1999). Ecological methodology (2nd ed.). Benjamin Cummings.
- Hill, M. O. (1973). Diversity and evenness: A unifying notation and its consequences. Ecology, 54(2), 427–432. doi.org/10.2307/1934352
- Jost, L. (2006). Entropy and diversity. Oikos, 113(2), 363–375. doi.org/10.1111/j.2006.0030-1299.14714.x
- Lande, R. (1996). Statistics and partitioning of species diversity. Oikos, 76(1), 5–13. doi.org/10.2307/3545743
- Chao, A., & Jost, L. (2012). Coverage-based rarefaction and extrapolation. Ecology, 93(12), 2533–2547. doi.org/10.1890/11-1952.1
- Oksanen, J., et al. (2022). vegan: Community ecology package. R package v2.6-4. CRAN.R-project.org/package=vegan
- Bibby, C. J., Burgess, N. D., Hill, D. A., & Mustoe, S. H. (2000). Bird census techniques (2nd ed.). Academic Press.
- Gotelli, N. J., & Colwell, R. K. (2001). Quantifying biodiversity: Procedures and pitfalls. Ecology Letters, 4(4), 379–391. doi.org/10.1046/j.1461-0248.2001.00230.x
- Colwell, R. K. (2013). EstimateS: Statistical estimation of species richness (v9). purl.oclc.org/estimates
- Whittaker, R. H. (1972). Evolution and measurement of species diversity. Taxon, 21(2/3), 213–251. doi.org/10.2307/1218190
- R Core Team. (2024). R: A language and environment for statistical computing. R-project.org
- Ahumada, J. A., et al. (2011). Community structure and diversity of tropical forest mammals. Phil. Trans. R. Soc. B, 366(1578), 2703–2711. doi.org/10.1098/rstb.2011.0115
- Chao, A., et al. (2014). Rarefaction and extrapolation with Hill numbers. Ecological Monographs, 84(1), 45–67. doi.org/10.1890/13-0133.1
- Niedballa, J., et al. (2016). camtrapR: An R package for camera trap data. Methods Ecol. Evol., 7(12), 1457–1462. doi.org/10.1111/2041-210X.12600
- Hsieh, T. C., Ma, K. H., & Chao, A. (2016). iNEXT: rarefaction and extrapolation of Hill numbers. Methods Ecol. Evol., 7(12), 1451–1456. doi.org/10.1111/2041-210X.12613
- Roswell, M., Dushoff, J., & Winfree, R. (2021). A conceptual guide to measuring species diversity. Oikos, 130(3), 321–338. doi.org/10.1111/oik.07202
- Peet, R. K. (1974). The measurement of species diversity. Annual Review of Ecology and Systematics, 5, 285–307. doi.org/10.1146/annurev.es.05.110174.001441