
Simple Random Sampling Calculator
Draw a reproducible simple random sample, then get sample size, mean, standard deviation, standard error, margin of error and a 95 percent confidence interval for every group, with four colour charts and a printable field pack.
0Quick Answer
★Key Takeaways
- Simple random sampling is the baseline probability design: equal selection probability n/N for every unit, and no subgroup is favoured.
- A sample is only defensible if the draw is reproducible, so always record the random seed and the sampling frame date.
- Precision is driven by the standard error s/√n, not by the sampling fraction, until n/N passes 5 percent.
- Apply the finite population correction √(1 − n/N) whenever you sample more than 5 percent of the population.
- Always draw a reserve list of about 20 percent extra units so inaccessible units can be replaced without breaking randomness.
1What Is Simple Random Sampling?
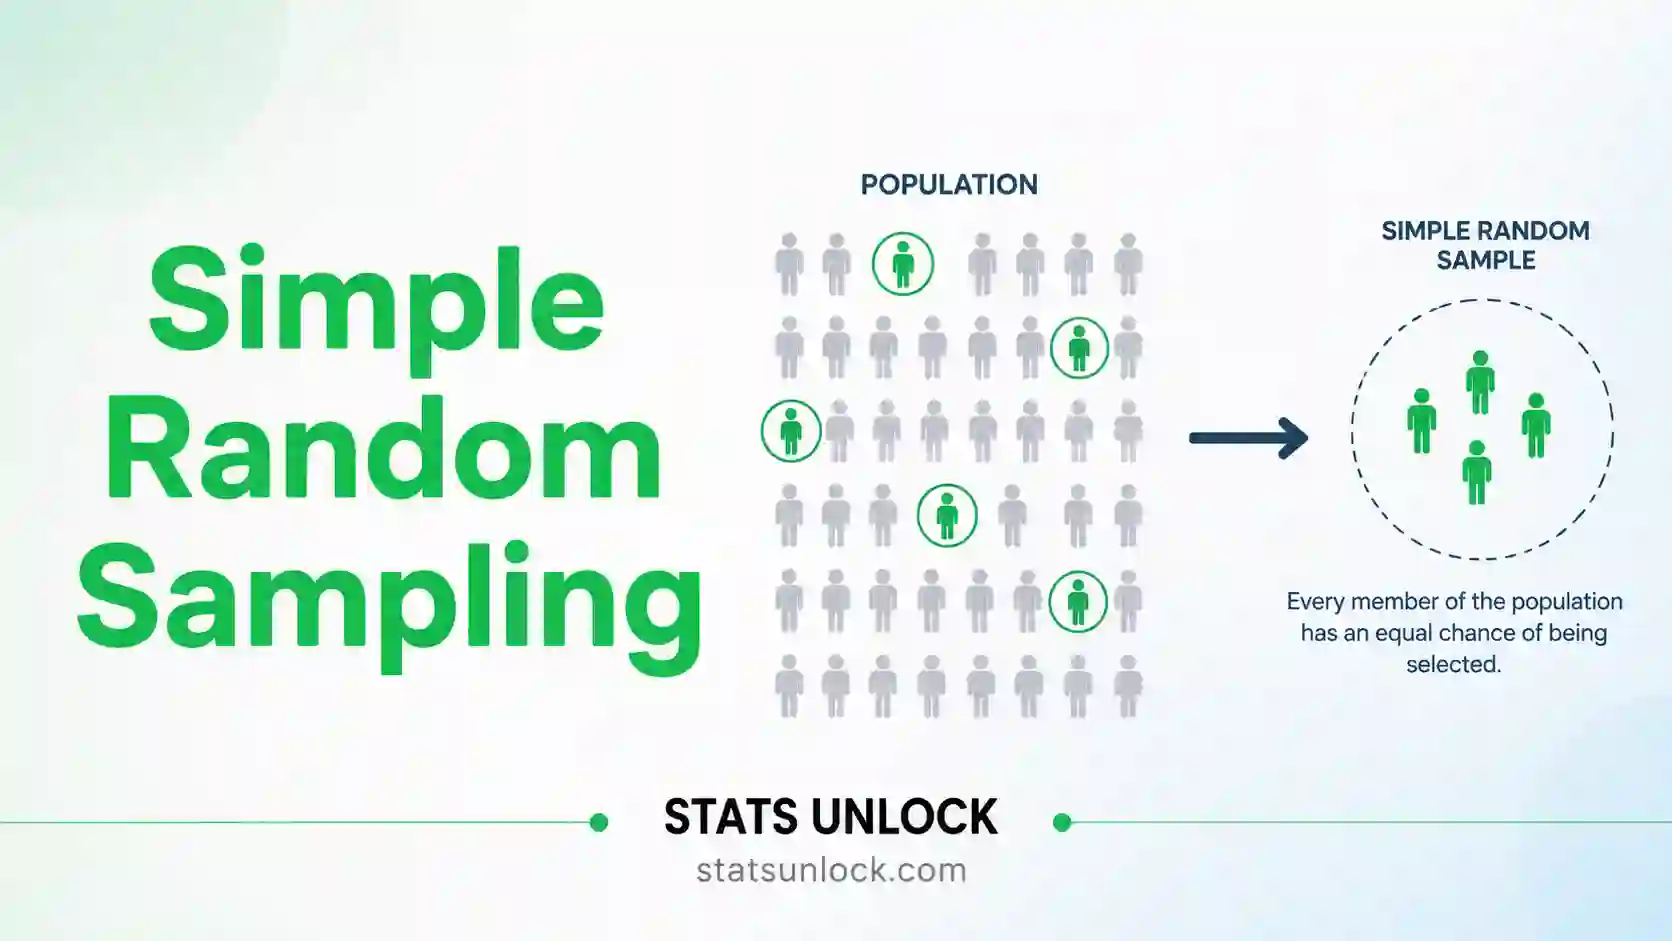
Simple random sampling (SRS) is a probability sampling method in which n units are selected from a population of N units in such a way that every unit has the same inclusion probability, and every possible sample of size n is equally likely. It is the reference design that all other sampling methods are compared against.
The method has two forms. Without replacement means a unit can be drawn only once, which is the normal choice in field and survey work. With replacement allows the same unit to be drawn twice, which simplifies the variance formula but wastes effort. This tool draws without replacement using a partial Fisher-Yates shuffle, so a duplicate can never appear.
Researchers use SRS because the estimator is unbiased, the variance formula is simple, and reviewers accept it without argument. Its weakness is that it ignores structure: if the population contains distinct strata or clusters, a stratified or cluster design will usually give a smaller standard error for the same cost.
Figure 1.1 Every unit in the frame has the same inclusion probability under simple random sampling.
2Sampling Setup: Enter Your Data and Design
Measurement data (one group per box)
3Results
4Interpretation of Results in Detail
How to read each number
The mean (x̄). Under simple random sampling the sample mean is an unbiased estimator of the population mean. That does not mean your particular sample mean equals the true value. It means that if you repeated the same draw many times, the average of all those sample means would land on the population mean. So never report the mean alone. Report it with its standard error or confidence interval so the reader can see how much sampling noise sits behind it.
The standard deviation (s). This describes how spread out the individual units are. It is a property of the population, not of your effort. Collecting more data does not shrink s. If s is large relative to the mean, the variable itself is patchy, and you will need a bigger sample to pin down the mean.
The standard error (SE). This describes how much the sample mean itself would bounce around across repeated samples. SE = s / √n. Because of the square root, halving the SE needs four times the sample. This is the single most useful sentence to remember when a supervisor asks whether to add 10 more plots: going from n = 40 to n = 50 improves precision by only about 11 percent.
The margin of error (MOE). MOE = t × SE, adjusted by the finite population correction when needed. It is the half width of the confidence interval, expressed in the same unit as your measurement. If your mean tree height is 18.4 m with a MOE of 1.2 m, you are saying the plausible range is roughly 17.2 to 19.6 m.
The 95 percent confidence interval. The correct reading is procedural: if the whole study were repeated many times, about 95 percent of the intervals built this way would contain the true population mean. It is not a 95 percent probability that the true mean lies in your one interval. Practically, a narrow interval means your design was adequate; a wide interval means the estimate is too vague to support a management decision.
The relative standard error (RSE). RSE = 100 × SE / x̄. This is the fastest quality flag because it is unit free. Most statistical agencies treat RSE below 10 percent as good, 10 to 25 percent as usable with a caution note, and above 25 percent as too unreliable to publish as a standalone figure. This tool shows a green, amber or red badge on exactly those cut points.
The sampling fraction and FPC. The fraction f = n/N tells you what share of the population you measured. When f is above 0.05 the finite population correction √(1 − f) meaningfully shrinks the standard error, because you are running out of population left to be uncertain about. When you census the whole population, f = 1 and the correction drives the SE to zero, which is correct: there is no sampling error in a complete count, only measurement error.
The required sample size (n required). This is what the tool solves backwards from your observed variability and your target margin of error. If n required is much larger than the n you drew, your pilot has told you the design is under-powered and you should either add units, accept a wider interval, or switch to a stratified design that removes some of the variance.
Comparing groups. If two group intervals do not overlap at all, the difference is almost certainly real. If they overlap slightly, the difference may still be significant, because overlapping confidence intervals are a conservative test. Run a formal two-sample test rather than eyeballing the bars when the overlap is small.
What the numbers cannot tell you. None of these statistics detect a bad sampling frame. If your list of households missed every seasonal migrant, the confidence interval will still look tight and reassuring while the estimate itself is biased. Precision statistics only describe sampling noise, never frame coverage error or measurement error.
5How to Write Your Results in Research
Use the templates below. Every one of them names the design, the sample size, the seed, the sampling fraction and the uncertainty, which is exactly what reviewers check first.
Rules that make a results paragraph pass review
- Name the design in the first sentence. Write "units were selected by simple random sampling without replacement", not "units were selected randomly". The word randomly on its own is ambiguous and reviewers flag it.
- Give N before n. The reader needs the population size to judge the sampling fraction. "40 of 400 quadrats (10 percent)" is complete; "40 quadrats" is not.
- State the randomisation instrument and seed. One clause is enough: "drawn with a Mulberry32 pseudo-random generator, seed 20250607". This single detail converts a claim into a reproducible procedure.
- Report the mean with a dispersion measure, always. Choose SD when describing the units, SE or CI when describing the estimate of the mean. Say which one you used, because M = 52.4 ± 1.3 is meaningless without a label.
- Match decimal places to precision. If the SE is 1.3, reporting the mean as 52.4382 is false precision. One more decimal than the SE is the usual convention.
- Say whether the FPC was applied. If f > 0.05 and you did not apply it, your intervals are too wide; if you did, say so, because the reader cannot reproduce your SE otherwise.
- Report non-response and replacements. "Three drawn units were inaccessible and were replaced from the pre-drawn reserve list in the order drawn" protects you from an accusation of convenience substitution.
- Put precision in the abstract. A mean without an interval in the abstract is the most common minor revision request in ecology and survey journals.
- Do not confuse SD and SE in figures. State in the caption which one the error bars show, and whether they are 1 SE or a 95 percent CI.
- Archive the frame and the drawn list. Deposit the sampling frame, the seed and the drawn IDs as supplementary data. This is now expected by most journals with an open data policy.
Common wording mistakes and the fix
| Wrong wording | Why it fails | Correct wording |
|---|---|---|
| "Samples were chosen at random." | Does not identify the design or the instrument. | "Units were selected by simple random sampling without replacement using a seeded generator." |
| "Mean = 52.4 ± 8.1" | Ambiguous: SD or SE. | "Mean = 52.4 (SD = 8.1, SE = 1.28, 95 percent CI 49.8 to 55.0)." |
| "There is a 95 percent chance the true mean is in this interval." | Misstates frequentist coverage. | "The 95 percent confidence interval, under repeated sampling, is 49.8 to 55.0." |
| "We sampled 10 percent, which is standard." | Percentages are not a justification for precision. | "n was set so the margin of error stayed below 2.5 units at 95 percent confidence." |
| "Missing plots were replaced by nearby plots." | Breaks the equal probability property. | "Inaccessible plots were replaced in order from a pre-drawn reserve list." |
6Formulas Used
7How to Use This Tool
- Type your study area or project name so it appears in every template and export.
- Pick a sample dataset preset if you want to see how the tool behaves, or skip straight to your own data.
- Enter the population size N, that is the total number of units in your sampling frame.
- Enter the sample size n you plan to draw, or use the required n the tool reports after a pilot run.
- Set a random seed. Write this number in your field notebook; it is what makes the draw reproducible.
- Paste your measurements as comma separated numbers, one box per group, and rename each group.
- Or switch to the upload tab, choose a CSV or Excel file, then click the columns that should each become a cluster.
- Choose the confidence level and the reserve list percentage, then click Draw Sample and Calculate.
- Read the summary cards, the per group table, the drawn sample and the four plots.
- Download the Field Pack for the field day, and copy the ready made methods paragraph into your manuscript.
8Detailed Reference Tables
Table 8.1 Critical values
| Confidence level | α | z value | t at df = 9 | t at df = 29 | t at df = 99 |
|---|---|---|---|---|---|
| 90 percent | 0.10 | 1.645 | 1.833 | 1.699 | 1.660 |
| 95 percent | 0.05 | 1.960 | 2.262 | 2.045 | 1.984 |
| 99 percent | 0.01 | 2.576 | 3.250 | 2.756 | 2.626 |
Table 8.2 Sample size for a proportion at 95 percent confidence (p = 0.5, worst case)
| Population N | MOE 10% | MOE 5% | MOE 3% | MOE 1% |
|---|---|---|---|---|
| 100 | 50 | 80 | 92 | 99 |
| 500 | 81 | 218 | 341 | 476 |
| 1,000 | 88 | 278 | 517 | 906 |
| 5,000 | 94 | 357 | 880 | 3,288 |
| 10,000 | 95 | 370 | 964 | 4,899 |
| 100,000 | 96 | 383 | 1,056 | 8,762 |
| 1,000,000 or more | 96 | 384 | 1,067 | 9,604 |
Table 8.3 Finite population correction factor √(1 − f)
| Sampling fraction f | √(1 − f) | Effect on SE | Apply it? |
|---|---|---|---|
| 0.01 | 0.995 | SE reduced by 0.5 percent | Optional |
| 0.05 | 0.975 | SE reduced by 2.5 percent | Threshold |
| 0.10 | 0.949 | SE reduced by 5 percent | Yes |
| 0.25 | 0.866 | SE reduced by 13 percent | Yes |
| 0.50 | 0.707 | SE reduced by 29 percent | Yes |
| 1.00 | 0.000 | No sampling error, full census | Yes |
Table 8.4 Precision verdict thresholds used by this tool
| Relative standard error | Badge | What to do |
|---|---|---|
| Below 10 percent | Good | Report the estimate as it is. |
| 10 to 25 percent | Use with caution | Report with a precision note, or add units. |
| Above 25 percent | Not adequate | Increase n, pool groups, or switch to stratified sampling. |
9Example Results (8 Worked Cards)
Example 1. Forest quadrat survey, tree density
N = 400 quadrats, n = 40, seed 20250607
Figure 9.1 Point estimate with its 95 percent confidence interval.
| Mean | SD | SE | MOE | 95% CI | Verdict |
|---|---|---|---|---|---|
| 52.4 stems/quadrat | 8.10 | 1.22 | 2.47 | 49.9 to 54.9 | Good |
What it means: The relative standard error is 2.3 percent, so 40 quadrats were more than enough for this variable.
How to write it: Tree density averaged 52.4 stems per quadrat (SD = 8.10, 95 percent CI 49.9 to 54.9, n = 40 of 400 quadrats).
Example 2. Household income survey, one village
N = 620 households, n = 60, seed 4412
Figure 9.2 Measured value for each sampled unit, drawn as vertical bars against the mean line.
| Mean | SD | SE | MOE | 95% CI | Verdict |
|---|---|---|---|---|---|
| 9,840 INR/month | 3,120 | 384 | 768 | 9,072 to 10,608 | Good |
What it means: RSE is 3.9 percent. The FPC applied because the fraction is 9.7 percent, trimming the SE by about 5 percent.
How to write it: Mean monthly income was 9,840 INR (SE = 384, 95 percent CI 9,072 to 10,608), from a simple random sample of 60 of 620 households.
Example 3. Camera trap station capture rate
N = 120 stations, n = 24, seed 771
Figure 9.3 Group totals compared side by side as horizontal bars.
| Mean | SD | SE | MOE | 95% CI | Verdict |
|---|---|---|---|---|---|
| 3.85 captures/100 nights | 2.60 | 0.48 | 0.99 | 2.86 to 4.84 | Use with caution |
What it means: RSE is 12.5 percent because capture rates are highly skewed. Consider more stations or a log transform.
How to write it: Capture rate averaged 3.85 per 100 trap nights (95 percent CI 2.86 to 4.84, n = 24 of 120 stations).
Example 4. Soil organic carbon, farm block
N = 250 grid cells, n = 25, seed 91
Figure 9.4 Every sampled unit shown as one dot, with the mean marked.
| Mean | SD | SE | MOE | 95% CI | Verdict |
|---|---|---|---|---|---|
| 1.42 percent | 0.31 | 0.059 | 0.12 | 1.30 to 1.54 | Good |
What it means: RSE 4.2 percent. A 10 percent sampling fraction, so the FPC was applied.
How to write it: Soil organic carbon averaged 1.42 percent (SD = 0.31, 95 percent CI 1.30 to 1.54, n = 25 of 250 cells).
Example 5. Student test scores, one school
N = 480 students, n = 48, seed 2024
Figure 9.5 Values plotted in frame order to reveal any trend across the population.
| Mean | SD | SE | MOE | 95% CI | Verdict |
|---|---|---|---|---|---|
| 64.7 marks | 12.9 | 1.77 | 3.56 | 61.1 to 68.3 | Good |
What it means: RSE 2.7 percent. The interval is narrow enough to compare against a pass mark of 60.
How to write it: Mean score was 64.7 marks (SD = 12.9, 95 percent CI 61.1 to 68.3), from 48 of 480 students drawn at random.
Example 6. Water quality, dissolved oxygen
N = 90 sites, n = 18, seed 505
Figure 9.6 Frequency distribution of the sampled values, with a smoothed outline.
| Mean | SD | SE | MOE | 95% CI | Verdict |
|---|---|---|---|---|---|
| 6.15 mg/L | 1.05 | 0.221 | 0.47 | 5.68 to 6.62 | Good |
What it means: RSE 3.6 percent. Sampling fraction 20 percent, so the FPC reduced the SE by about 11 percent.
How to write it: Dissolved oxygen averaged 6.15 mg/L (95 percent CI 5.68 to 6.62, n = 18 of 90 sites).
Example 7. Clinic waiting time, patient sample
N = 1,500 visits, n = 100, seed 3030
Figure 9.7 Share of the sample held by each part of the design.
| Mean | SD | SE | MOE | 95% CI | Verdict |
|---|---|---|---|---|---|
| 37.6 minutes | 18.4 | 1.78 | 3.53 | 34.1 to 41.1 | Good |
What it means: RSE 4.7 percent. Waiting times are right skewed, so the median is also worth reporting.
How to write it: Mean waiting time was 37.6 minutes (SD = 18.4, 95 percent CI 34.1 to 41.1, n = 100 of 1,500 visits).
Example 8. Awkward case: tiny population, high spread
N = 30 plots, n = 8, seed 12
Figure 9.8 Spread, quartiles and median for each group as box and whisker plots.
| Mean | SD | SE | MOE | 95% CI | Verdict |
|---|---|---|---|---|---|
| 14.5 units | 9.80 | 2.99 | 7.07 | 7.4 to 21.6 | Not adequate |
What it means: RSE is 20.6 percent and the interval spans a threefold range. Eight plots cannot support a management decision here.
How to write it: The estimate was 14.5 units (95 percent CI 7.4 to 21.6, n = 8 of 30 plots) and is reported as provisional because of low precision.
10How to Collect Raw Data in the Field
10a. The 18 point field protocol for simple random sampling
Plan
- Build the sampling frame first. Write every unit once, with a unique ID, in a spreadsheet. A frame with duplicates or gaps breaks the equal probability property before you set foot outside.
- Fix the unit definition in writing. A quadrat is 10 m by 10 m with the peg at the south west corner; a household is everyone who ate from one kitchen last night. Ambiguous units create measurement noise you cannot fix later.
- Decide n from a target margin of error, not from habit. Run a 10 unit pilot, feed the pilot SD into this tool, and read the required n.
- Draw the simple random sample before travelling and record the seed in the notebook, not only on the phone.
- Draw a reserve list of 20 percent extra units in draw order. Replacements must come from this list, in order, never from whatever is nearby.
Figure 10.1 The drawn sample and the reserve list, plotted before the field day.
Kit
- Carry the printed Field Pack from this tool. Phones die; paper does not.
- Carry a GPS or a phone with offline maps and check its accuracy reading before you accept a point.
- Carry the measuring kit matched to the unit: 30 m tape and pegs for quadrats, calibrated balance for weights, a DO meter with a fresh calibration for water.
- Carry two pencils and a waterproof sheet cover. Ink runs in rain and a lost sheet is a lost field day.
Locate
- Go to the drawn unit, not the convenient one. This is the single most common way a random sample quietly becomes a convenience sample.
- Navigate to the coordinate, then place the unit by a fixed rule, for example the peg goes at the coordinate and the quadrat extends north east. Use the same rule everywhere.
- If a unit is genuinely inaccessible, mark it Not found, write the reason, and take the next reserve unit in order.
Figure 10.2 Substituting an easy unit for a drawn unit destroys the equal probability property.
Collect
- Fill one datasheet row per unit, on the spot. Never write from memory at the end of the day.
- Record a true zero as 0, never as a blank. A blank means not measured; a zero means measured and none present. Confusing the two is the most damaging data entry error in field work.
- Record effort as well as outcome: start time, end time, observer, weather. Effort lets you check whether tired observers produced different numbers.
Figure 10.3 One completed datasheet row, including a true zero.
Figure 10.4 Three different records that must never be written the same way.
Check
- Before leaving each unit, re-read the row aloud against the ground. Two seconds of checking saves a week of cleaning.
- At the end of the day, count rows against the drawn list. Rows plus Not found entries must equal n exactly.
- Photograph every sheet the same evening and enter the numbers within 48 hours, while the handwriting still makes sense.
Figure 10.5 The effort block that turns a raw count into a comparable rate.
10b. Datasheet column specification
| Column | Format | Example | Why it matters |
|---|---|---|---|
| Study area | Text, header once | Anaimalai Block C | Links the sheet to the project and the frame. |
| Date | YYYY-MM-DD | 2026-08-07 | Unambiguous across countries. |
| Seed | Integer, header once | 20250607 | Lets anyone regenerate the same draw. |
| Unit ID | Prefix plus number from the tool | U-0137 | Never renumber; the ID ties the row to the draw. |
| Draw order | Integer 1..n | 14 | Reserve units must be used in this order. |
| Latitude, Longitude | Decimal degrees, 5 dp | 10.41207, 76.98811 | Allows a re-visit and a spatial check. |
| Status | Found / Not found / Replaced | Found | Separates non-response from a true zero. |
| Value | Number with unit in header | 0 | The measurement itself; 0 is a real value. |
| Observer | Initials | RP | Detects observer effects. |
| Start, End time | HH:MM 24 hour | 07:42, 08:05 | Effort correction and quality control. |
| Notes | Free text, short | True zero, dense litter | Explains anything a number cannot. |
Zero rule: write 0 for measured and none present; leave blank only when the unit was not measured at all. No renumbering rule: keep the unit IDs exactly as drawn, even if you visit them out of order.
10c. Filled worked datasheet
| # | Unit ID | Lat, Long | Status | Value (stems) | Observer | Notes |
|---|---|---|---|---|---|---|
| 1 | U-0012 | 10.41102, 76.98420 | Found | 48 | RP | |
| 2 | U-0037 | 10.41255, 76.98604 | Found | 55 | RP | |
| 3 | U-0061 | 10.41310, 76.98711 | Found | 0 | RP | True zero, bare rock patch |
| 4 | U-0088 | 10.41402, 76.98850 | Not found | RP | Inside fenced private plot, no access | |
| 5 | R-0104 | 10.41455, 76.98902 | Replaced | 51 | RP | Reserve unit 1 used in place of U-0088 |
| 6 | U-0119 | 10.41501, 76.99011 | Found | 61 | SK | |
| 7 | U-0137 | 10.41207, 76.98811 | Found | 47 | SK | |
| 8 | U-0158 | 10.41620, 76.99120 | Found | 58 | SK | Uncertain, two stems may be one clump |
| 9 | U-0173 | 10.41688, 76.99204 | Found | 44 | SK | |
| 10 | U-0190 | 10.41740, 76.99301 | Found | 53 | SK |
What this sheet shows:
- Row 3 is a true zero, written as 0, so it still contributes to the mean.
- Row 4 is a non-response with the reason recorded, so the loss is auditable.
- Row 5 uses the first reserve unit in draw order, which keeps the design defensible.
- Row 8 flags an uncertain count in the notes rather than silently rounding it.
- The observer column changes at row 6, which lets you test for an observer effect later.
10d. Blank print ready datasheet
Download the blank sheet as a .csv file, open it in Excel, Google Sheets or LibreOffice, then print it. Rows are sized to stay readable after a black and white photocopy, and the same columns match the Field Pack export.
11Which Sampling Method Should You Use?
Decision tree. Answer these in order and stop at the first yes.
- Do you have a complete list of every unit, and is the population fairly uniform? Use simple random sampling.
- Do you have a list, but the population splits into subgroups that clearly differ, such as habitat types or income bands? Use stratified random sampling.
- Do you have a list in a fixed order and want an easy field rule? Use systematic sampling with a random start, unless the list has a repeating cycle.
- Is there no list, but the population comes in natural groups you can list, such as villages or plots? Use cluster sampling.
- Is the population huge and spread over long distances? Use multistage sampling.
- Do units differ hugely in size, so bigger units should have a bigger chance? Use probability proportional to size.
- Is the target rare and clumped? Use adaptive cluster sampling.
- Is the population hidden or hard to reach, with no frame at all? Use respondent driven or snowball sampling, and accept that it is non-probability.
| Method | Needs a frame? | Field cost | Bias risk | Precision per unit | Field difficulty |
|---|---|---|---|---|---|
| Simple random | Yes, complete | High travel | Low | Baseline | Medium |
| Systematic | Yes, ordered | Low | Low unless periodic | Equal or better | Easy |
| Stratified | Yes, plus strata | Medium | Low | Better | Medium |
| Cluster | List of clusters only | Low | Medium | Worse, deff > 1 | Easy |
| Multistage | Partial | Low | Medium | Worse | Medium |
| PPS | Yes, plus sizes | Medium | Low | Better for totals | Hard |
| Convenience | No | Very low | Very high | Not estimable | Very easy |
12Troubleshooting and Common Sampling Errors
My confidence interval is far too wide to be useful
Cause: n is too small for the natural variability s. Fix: read the required n from the results cards, or reduce variance by stratifying on the variable that drives the spread.
Several drawn units were inaccessible
Cause: the frame includes units you cannot legally or physically reach. Fix: use the reserve list in order, record every replacement, and if losses exceed 10 percent report a non-response analysis comparing found and not found units.
My field team replaced points with easier nearby points
Cause: no reserve list was carried. Fix: this is a real bias, not a rounding issue. Report it honestly as a limitation and re-draw for the next round with a printed reserve list.
The frame is out of date and some units no longer exist
Cause: frame ageing. Fix: treat vanished units as out of scope, reduce N accordingly, and document the date of the frame. Do not silently substitute new units.
Two observers produced systematically different values
Cause: observer effect. Fix: cross calibrate on 5 shared units, and include observer as a factor when analysing. Randomising which observer visits which unit prevents this becoming a confound.
My sampling fraction is above 50 percent, is that wrong?
Cause: a small population. Fix: nothing is wrong, but you must apply the finite population correction, and at that point a full census is often cheaper than a sample.
The tool says my relative standard error is above 25 percent
Cause: high variability relative to the mean, often a skewed count variable. Fix: increase n, pool small groups, or analyse on a log scale and report a geometric mean.
I lost the seed, can I still report the design?
Cause: the seed was only on a phone. Fix: report the drawn unit list itself as supplementary data, which preserves reproducibility even without the seed, and write the seed in the notebook next time.
My data has a few extreme outliers
Cause: genuine heterogeneity or a recording error. Fix: check the raw sheet first. If real, keep them, report the median alongside the mean, and consider a stratified redesign, because outliers inflate the SE dramatically.
Uploaded CSV columns loaded with blank values
Cause: mixed text and numbers, or trailing empty rows. Fix: the tool skips non numeric cells automatically, but check the n shown per group matches what you expect.
13Assumptions, Bias and Limitations
- Complete frame assumption. Every unit must appear exactly once. Units missing from the frame have zero selection probability, which produces coverage bias no statistic can detect.
- Equal probability assumption. Any substitution of a convenient unit for a drawn unit breaks this and turns the design into convenience sampling.
- Independence assumption. Drawing without replacement makes units slightly dependent, which is exactly what the finite population correction accounts for.
- Approximate normality of the sample mean. The t interval relies on the central limit theorem. For strongly skewed variables with n below about 30, use a bootstrap interval instead.
- Non-response bias. If missing units differ systematically from found units, the estimate is biased even though the interval looks fine.
- Measurement error. These formulas describe sampling noise only. A miscalibrated instrument shifts every value and no confidence interval will warn you.
- Efficiency limitation. Simple random sampling ignores structure, so it is often the least precise probability design per unit of cost in a heterogeneous population.
- Travel cost limitation. Randomly scattered points mean long walks. Systematic or cluster designs cover ground far more cheaply.
14Conclusion
What simple random sampling gives you
Simple random sampling is the design that needs the least defending. Because every unit carries the same inclusion probability, the sample mean is unbiased, the variance has a closed form, and no reviewer will ask you to justify a weighting scheme. That simplicity is why it remains the reference point for every other sampling method, and why an SRS estimate with a stated seed and a stated sampling fraction is accepted almost anywhere.
What it costs you
Simplicity is paid for in the field. Random points scatter, so travel time rises, and in a heterogeneous population the standard error will be larger than a stratified design would deliver for the same n. If your pilot shows a large standard deviation driven by an obvious subgroup difference, moving to stratified sampling is usually the cheapest precision gain available.
What to check before you publish
Confirm four things: the frame was complete and dated, the seed and drawn list are archived, the finite population correction was applied whenever the fraction exceeded 5 percent, and every mean is reported with a standard error or a confidence interval. Those four lines are what separate a design a reviewer trusts from one they query.
What to do next
Use the required sample size from your pilot to plan the full survey, print the Field Pack with the reserve list, and keep the same seed convention across seasons so repeat surveys stay comparable. If your relative standard error is still above 10 percent after increasing n, the variable itself is patchy and the answer is a better design, not more walking.
15Test Yourself
1. A population has N = 500 and you draw n = 50. What is the inclusion probability of any one unit?
0.10. Under SRS the probability is n/N for every unit, identical across the population.
2. You double your sample from 40 to 80. By how much does the standard error fall?
By a factor of √2, about 29 percent. Precision improves with the square root of n, not linearly.
3. When must you apply the finite population correction?
When the sampling fraction n/N exceeds about 0.05. Below that the correction changes the standard error by less than 2.5 percent.
4. A drawn quadrat sits inside a locked private plot. What do you do?
Mark it Not found with the reason, then take the next unit from the pre-drawn reserve list in order. Never pick a nearby accessible quadrat.
5. Your mean is 12.0 with SE 3.5. Is this publishable as a standalone figure?
The relative standard error is 29 percent, above the 25 percent cut point, so it is too imprecise to stand alone. Increase n or report it as provisional.
6. Why report the random seed in a methods section?
Because it makes the draw reproducible. Another researcher can regenerate the identical sample, which turns a claim of randomness into a verifiable procedure.
16Frequently Asked Questions
1. What is simple random sampling in statistics?
Simple random sampling is a probability design in which n units are drawn from N so that every unit has the same chance of selection and every possible sample of size n is equally likely. It is the reference design all other methods are compared to.
2. How do I do simple random sampling step by step?
List every unit with a unique ID, decide n from a target margin of error, set a random seed, draw n IDs without replacement, draw a 20 percent reserve list, then visit exactly those units and record one row per unit.
3. What is the formula for simple random sampling sample size?
For a mean, n0 = (z s / e)^2, then n = n0 / (1 + n0/N). For a proportion, n0 = z^2 p(1-p) / e^2 with the same correction. Always round up.
4. What is the difference between simple random sampling and systematic sampling?
Simple random sampling picks n IDs at random. Systematic sampling picks every k-th unit after a random start, where k = N/n. Systematic is easier in the field but fails if the list has a repeating cycle.
5. Is simple random sampling with or without replacement?
Field and survey work almost always uses without replacement, so a unit cannot be drawn twice. Without replacement needs the finite population correction; with replacement does not.
6. What is the finite population correction and when do I use it?
It is the factor sqrt(1 - n/N) applied to the standard error. Use it whenever you sample more than about 5 percent of the population, because sampling a large share leaves less uncertainty.
7. How large should my sample be for simple random sampling?
Large enough that the margin of error meets your decision need. Run a 10 unit pilot, feed the pilot standard deviation into the formula n0 = (z s / e)^2, apply the correction, and round up.
8. What is a good relative standard error?
Below 10 percent is good, 10 to 25 percent is usable with a caution note, and above 25 percent is generally treated as too unreliable to publish as a standalone estimate.
9. Why do I need a random seed?
A seed makes the draw reproducible. Reporting it lets a reviewer regenerate the exact same sample, which converts an unverifiable claim of randomness into a checkable procedure.
10. Can I use Excel for simple random sampling?
Yes, RAND or RANDBETWEEN with a sort works, but Excel gives no reproducible seed by default and RANDBETWEEN can repeat values. A seeded tool with a duplicate free draw is safer.
11. What are the advantages of simple random sampling?
Unbiased estimates, a simple variance formula, no weighting needed, easy to explain, and universally accepted by reviewers and statistical agencies.
12. What are the disadvantages of simple random sampling?
It needs a complete frame, scattered points make field travel expensive, and it ignores population structure, so it is often less precise than stratified sampling for the same effort.
13. When should I use stratified sampling instead?
When the population contains subgroups that clearly differ from one another. Stratifying removes between group variance from the error term and usually shrinks the standard error for the same n.
14. How do I handle units I cannot reach?
Mark them Not found with the reason, then replace them in order from a pre-drawn reserve list. Never substitute a convenient nearby unit, because that breaks equal probability.
15. Does simple random sampling guarantee a representative sample?
No. It guarantees an unbiased procedure, not a representative outcome for any single draw. A small random sample can still look unbalanced by chance.
16. What is the sampling fraction?
The sampling fraction is f = n/N, the share of the population you measured. It also equals the inclusion probability of each unit under simple random sampling.
17. How do I report simple random sampling in a research paper?
State the design, the frame and its date, N and n, the randomisation instrument and seed, the sampling fraction, whether the finite population correction was applied, and the mean with a confidence interval.
18. What is the difference between standard deviation and standard error here?
Standard deviation describes how spread the individual units are. Standard error describes how much the sample mean itself would vary across repeated samples, and equals s divided by the square root of n.
19. Can I run simple random sampling without knowing the population size?
You can draw randomly from whatever list you have, but you cannot compute the sampling fraction, apply the correction, or generalise to a defined population. An unknown N weakens every inference.
20. Is simple random sampling suitable for rare species surveys?
Usually not. Rare and clumped targets produce many zeros and a huge relative standard error. Adaptive cluster sampling or stratified sampling with a habitat stratum works far better.
17Cite This Tool
18Related Tools
- Stratified Random Sampling Calculator for proportional, equal and Neyman allocation.
- Systematic Sampling Calculator for interval k with a random start.
- Sample Size Calculator using Cochran, Yamane and Krejcie-Morgan.
19Glossary of Terms
| Term | Meaning |
|---|---|
| Bias | A systematic difference between the expected estimate and the true population value. |
| Cluster | A natural group of units, such as a village or a plot, used as a sampling unit. |
| Confidence interval | A range built so that a stated share of such intervals would contain the true value under repeated sampling. |
| Coverage error | Error caused by units missing from, or duplicated in, the sampling frame. |
| Design effect | The ratio of the variance under the actual design to the variance under simple random sampling. |
| Effective sample size | n divided by the design effect; the equivalent SRS sample size. |
| Estimator | The rule used to compute a population quantity from the sample, such as the sample mean. |
| Finite population correction | The factor √(1 − n/N) that shrinks the standard error when a large share of N is sampled. |
| Inclusion probability | The chance that a given unit enters the sample; equal to n/N under SRS. |
| Margin of error | Half the width of a confidence interval, equal to the critical value times the standard error. |
| Non-response | A drawn unit that could not be measured. |
| Population | The complete set of units you want to describe. |
| Reserve list | Extra units drawn in advance, used in order to replace inaccessible units. |
| Sampling frame | The actual list of units from which the sample is drawn. |
| Sampling fraction | n divided by N, the share of the population measured. |
| Seed | A number that fixes a pseudo-random sequence so a draw can be repeated exactly. |
| Standard deviation | Spread of individual values around the sample mean. |
| Standard error | Expected variability of the sample mean across repeated samples. |
| Stratum | A subgroup of the population treated as a separate sampling layer. |
| Without replacement | A draw in which a selected unit cannot be selected again. |
20References
- Cochran, W. G. (1977). Sampling Techniques (3rd ed.). Wiley. Publisher page
- Lohr, S. L. (2021). Sampling: Design and Analysis (3rd ed.). CRC Press. https://doi.org/10.1201/9780429298899
- Thompson, S. K. (2012). Sampling (3rd ed.). Wiley. https://doi.org/10.1002/9781118162934
- Kish, L. (1965). Survey Sampling. Wiley. Archive record
- Krejcie, R. V., & Morgan, D. W. (1970). Determining sample size for research activities. Educational and Psychological Measurement, 30(3), 607-610. https://doi.org/10.1177/001316447003000308
- Yamane, T. (1967). Statistics: An Introductory Analysis (2nd ed.). Harper and Row. WorldCat record
- Horvitz, D. G., & Thompson, D. J. (1952). A generalization of sampling without replacement from a finite universe. Journal of the American Statistical Association, 47(260), 663-685. https://doi.org/10.1080/01621459.1952.10483446
- Neyman, J. (1934). On the two different aspects of the representative method. Journal of the Royal Statistical Society, 97(4), 558-625. https://doi.org/10.2307/2342192
- Hansen, M. H., & Hurwitz, W. N. (1943). On the theory of sampling from finite populations. Annals of Mathematical Statistics, 14(4), 333-362. https://doi.org/10.1214/aoms/1177731356
- Elzinga, C. L., Salzer, D. W., & Willoughby, J. W. (1998). Measuring and Monitoring Plant Populations. BLM Technical Reference 1730-1. BLM library
- Krebs, C. J. (1999). Ecological Methodology (2nd ed.). Benjamin Cummings. WorldCat record
- Buckland, S. T., et al. (2001). Introduction to Distance Sampling. Oxford University Press. Publisher page
- Gregoire, T. G., & Valentine, H. T. (2007). Sampling Strategies for Natural Resources and the Environment. Chapman and Hall. https://doi.org/10.1201/9780203498880
- Bartlett, J. E., Kotrlik, J. W., & Higgins, C. C. (2001). Organizational research: determining appropriate sample size in survey research. Information Technology, Learning, and Performance Journal, 19(1), 43-50. ERIC record
- Levy, P. S., & Lemeshow, S. (2008). Sampling of Populations: Methods and Applications (4th ed.). Wiley. https://doi.org/10.1002/9780470374597
- Sarndal, C. E., Swensson, B., & Wretman, J. (1992). Model Assisted Survey Sampling. Springer. https://doi.org/10.1007/978-1-4612-4378-6
- Rao, J. N. K., & Molina, I. (2015). Small Area Estimation (2nd ed.). Wiley. https://doi.org/10.1002/9781118735855
- Groves, R. M., et al. (2009). Survey Methodology (2nd ed.). Wiley. Publisher page
- Marsaglia, G. (2003). Xorshift RNGs. Journal of Statistical Software, 8(14), 1-6. https://doi.org/10.18637/jss.v008.i14
- Efron, B., & Tibshirani, R. J. (1993). An Introduction to the Bootstrap. Chapman and Hall. https://doi.org/10.1201/9780429246593