
Systematic Sampling Calculator
Calculate the sampling interval k, draw a seeded random start, list every selected unit, then get the mean, standard error, margin of error, design effect and a periodicity check, with four colour charts and a printable field pack.
0Quick Answer
★Key Takeaways
- Systematic sampling needs only one random number, the start r, and then a fixed interval k = N / n does the rest.
- It spreads the sample evenly across the frame, so it usually beats simple random sampling when the frame carries a trend or gradient.
- It fails badly when the frame is periodic and the cycle length matches k, because every drawn unit lands on the same phase.
- Use circular systematic sampling when N is not an exact multiple of n, so you always get exactly n units.
- A single systematic sample gives no unbiased variance estimate, so use the successive differences estimator or multiple random starts.
1What Is Systematic Sampling?
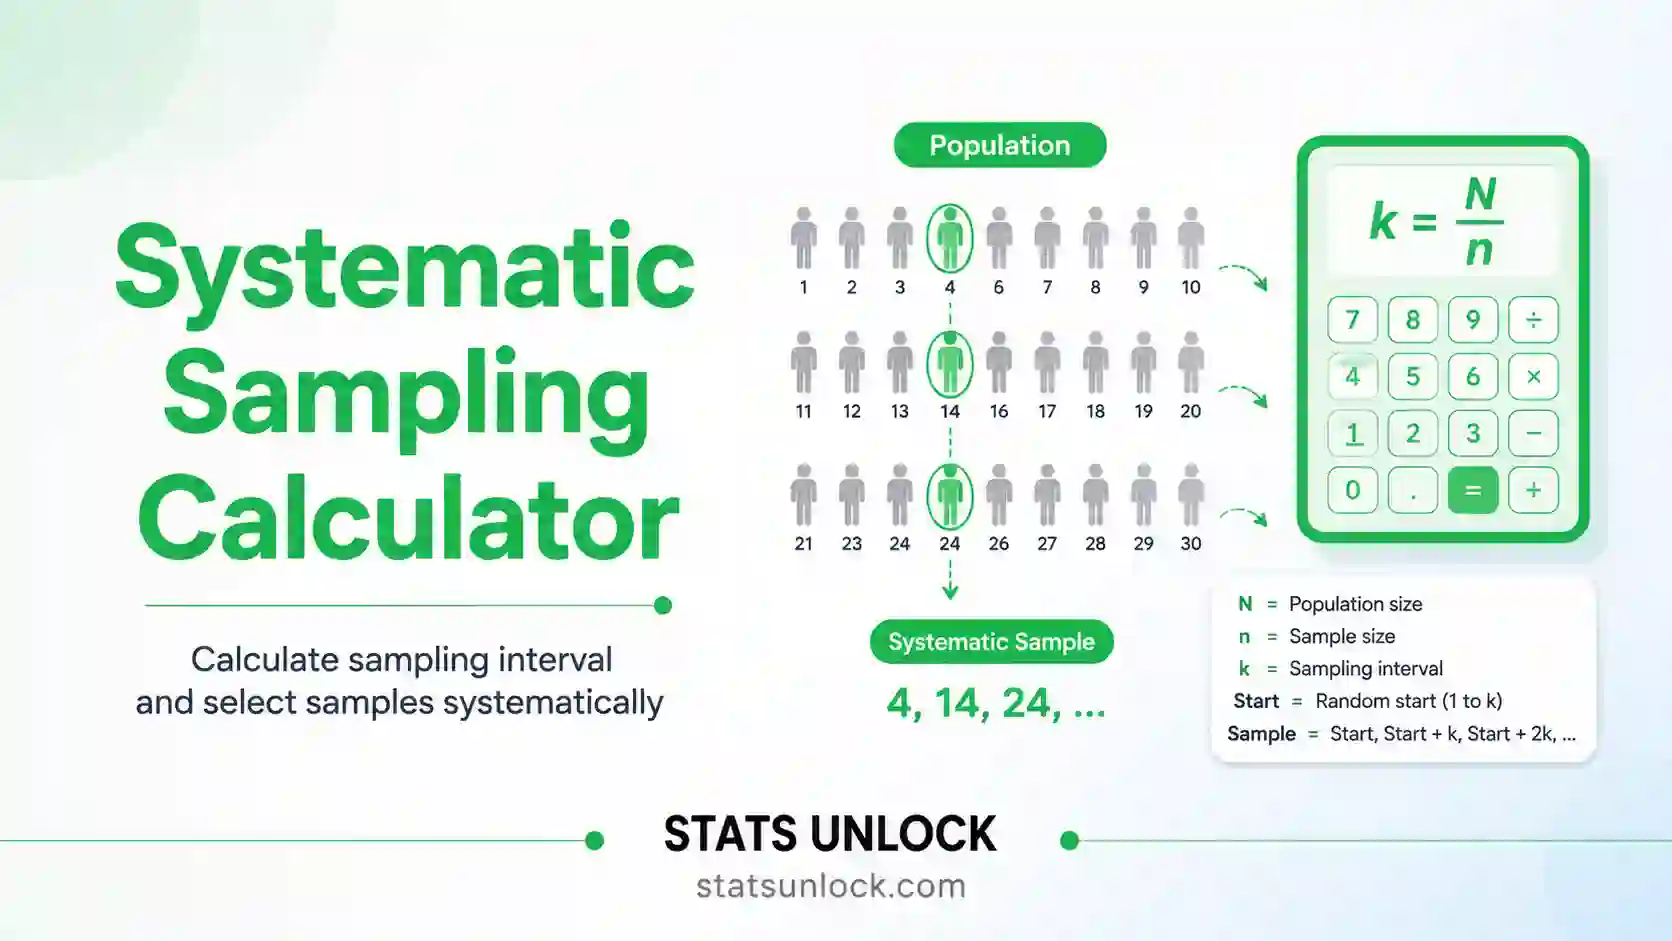
Systematic sampling is a probability sampling method in which the units of an ordered population are selected at a fixed interval. You divide the population size N by the sample size n to get the sampling interval k, draw one random start r between 1 and k, then select units r, r + k, r + 2k and so on until the list ends. Because only the start is random, the whole sample is decided by a single random number.
This is why field teams like it. Walking a transect and stopping every 25 metres is far easier than hunting for scattered random coordinates, and a register can be sampled by counting down every k-th row without any lookup table. The units also spread evenly across the frame, so a trend from one end to the other is automatically covered, which is where systematic sampling often beats simple random sampling on precision.
The method has one serious weakness. If the frame repeats on a cycle whose length matches or divides k, every selected unit falls on the same phase of that cycle. Sampling every 7th day always lands on the same weekday. Sampling every 4th house in a block of 4 always lands on the corner plot. That is periodicity, and it produces bias no amount of extra sampling will fix.
Figure 1.1 One random start plus a fixed interval k selects the entire systematic sample.
2Sampling Setup: Enter Your Data and Design
Measurement data (one group per box)
3Results
4Interpretation of Results in Detail
How to read each number
The sampling interval k. This is N divided by n, and it is the single most important number in a systematic design. It sets the physical spacing between units, so k = 10 on a 500 metre transect means a stop every 10 metres if units are one metre apart. When N is not an exact multiple of n, k is not a whole number, and rounding it down gives you slightly more units than requested while rounding up gives you fewer. The tool reports both the exact N/n and the integer k actually used, so the mismatch is never hidden.
The random start r. Only one random number is drawn in the entire design, and this is it. It must fall between 1 and k inclusive. If you fix r at 1 out of habit, the design stops being a probability sample, because unit positions are then determined rather than random, and no valid inference follows. Report r alongside the seed.
The achieved sample size. In linear systematic sampling the number of units you actually get is either floor((N - r)/k) + 1 or one more or less than the n you asked for. This is normal and not an error. If you need exactly n every time, switch to circular systematic sampling, which wraps around the end of the frame and always returns exactly n units.
The mean and standard deviation. The systematic sample mean is unbiased for the population mean whenever N is an exact multiple of n. When it is not, a small bias enters because the possible samples have slightly different sizes; circular systematic sampling removes that bias. The standard deviation describes the spread of individual units and does not shrink as n grows.
The three standard errors. A single systematic sample cannot give an unbiased variance estimate, because there is only one random draw. The tool therefore shows three estimators. The simple random approximation treats the sample as if it were simple random, which is the common default and is conservative when the frame carries a trend. The successive differences estimator uses the squared gaps between neighbouring selected units and is usually the better choice for an ordered frame. The between starts estimator appears only when you request two or more random starts, and it is the only genuinely unbiased option of the three.
The design effect and intraclass correlation. The design effect compares the systematic variance to the simple random variance. A value below 1 means systematic sampling gained you precision, which happens when the frame has a smooth trend and the even spread captures it. A value above 1 means you lost precision, which usually signals periodicity or clustering in the frame. The implied intraclass correlation rho is derived from the design effect and tells you how similar neighbouring units are.
The margin of error and confidence interval. The margin of error is the critical t value multiplied by the standard error you choose to trust, with the finite population correction applied when the sampling fraction exceeds 5 percent. Always say which variance estimator produced the interval you report, because the three can differ substantially.
The periodicity check. The tool compares your stated cycle length against k. If the cycle divides k exactly, or k divides the cycle, every selected unit lands on the same phase and the estimate is biased no matter how large n is. The fix is not more units, it is a different k, a random start within each cycle, or a switch to stratified sampling with the cycle as the stratum.
What the numbers cannot tell you. None of these statistics can detect a frame whose ordering is itself meaningless or corrupted. Systematic sampling assumes the order carries information, whether that is spatial sequence, time sequence or a register order. If the list was sorted by something irrelevant, systematic sampling degrades to a slightly awkward version of simple random sampling, and if it was sorted by the variable you are measuring, the even spread will look artificially precise.
5How to Write Your Results in Research
Use the templates below. Each one names the interval, the random start, the seed and the variance estimator, which is exactly what a reviewer will look for in a systematic design.
Rules that make a results paragraph pass review
- Name the design and the ordering. Write "systematic sampling with a random start from a frame ordered by distance along the transect". The ordering is part of the design, not background detail.
- Give N, n and k together. "Every 10th of 500 quadrats (k = 10, n = 50)" is complete; "every 10th quadrat" is not.
- State the random start explicitly. "Random start r = 7, drawn with seed 20250607" is the sentence that proves this was a probability sample and not a convenience walk.
- Say whether the design was linear or circular. These give different sample sizes and different bias properties, so the reader cannot reproduce your work without knowing which you used.
- Name the variance estimator. A confidence interval from the simple random approximation is not the same as one from successive differences. Say which one produced your numbers.
- Report the periodicity check. One sentence is enough: "the frame contains no cycle of length 10 or any divisor of 10". Reviewers of systematic designs always ask.
- Report the achieved n, not just the target n. If you asked for 50 and got 51, write 51 and explain the rounding in one clause.
- Report the design effect if you computed it. A deff below 1 is a genuine result worth stating, because it justifies the design choice.
- Match decimal places to the standard error. One more decimal than the SE is the usual convention; anything more is false precision.
- Archive the ordered frame. With systematic sampling the frame order is part of the method, so deposit the ordered list, not just the drawn IDs.
Common wording mistakes and the fix
| Wrong wording | Why it fails | Correct wording |
|---|---|---|
| "We sampled every 10th unit." | No random start, so no probability design is described. | "We sampled every 10th unit (k = 10) after a random start of r = 7." |
| "We started at the first unit." | A fixed start destroys the randomisation. | "The start was drawn at random from 1 to k using a seeded generator." |
| "Mean = 52.4, SE = 1.2" | Does not say which of the three estimators produced the SE. | "Mean = 52.4 (SE = 1.2 by the successive differences estimator, 95 percent CI 49.9 to 54.9)." |
| "Systematic sampling was used, which is like random sampling." | Glosses over the periodicity assumption. | "Systematic sampling was used; the frame was checked and contains no cycle matching k." |
| "n = 50 units were measured." | Hides that linear systematic gave 51. | "51 units were measured, one more than the target of 50 because N/n was not an integer." |
6Formulas Used
7How to Use This Tool
- Type your study area or project name so it appears in every template and export.
- Pick a sample dataset preset to see how the tool behaves, or go straight to your own data.
- Enter the population size N, that is the total number of units in your ordered frame.
- Enter the sample size n you want; the tool works out the interval k for you.
- Choose linear systematic for the classic every k-th rule, or circular systematic when you need exactly n units.
- Choose how many random starts to use. Two or more lets the tool estimate the variance directly.
- Enter any known cycle length in your frame so the periodicity check can warn you.
- Paste your measurements in frame order as comma separated numbers, one box per group, and rename each group.
- Or switch to the upload tab, choose a CSV or Excel file, then click the columns that should each become a cluster.
- Click Draw Systematic Sample and Calculate, read the results and the four plots, then download the Field Pack.
8Detailed Reference Tables
Table 8.1 Sampling interval k for common N and n
| Population N | n = 20 | n = 30 | n = 50 | n = 100 | n = 200 |
|---|---|---|---|---|---|
| 100 | k = 5 | k = 3 | k = 2 | census | not possible |
| 250 | k = 13 | k = 8 | k = 5 | k = 3 | k = 1 |
| 500 | k = 25 | k = 17 | k = 10 | k = 5 | k = 3 |
| 1,000 | k = 50 | k = 33 | k = 20 | k = 10 | k = 5 |
| 5,000 | k = 250 | k = 167 | k = 100 | k = 50 | k = 25 |
| 10,000 | k = 500 | k = 333 | k = 200 | k = 100 | k = 50 |
Table 8.2 Periodicity risk by cycle length and interval
| Frame type | Typical cycle c | Dangerous k values | Safe k values |
|---|---|---|---|
| Daily register | 7 days | 7, 14, 21, 28 | 5, 8, 9, 11, 13 |
| Monthly records | 12 months | 2, 3, 4, 6, 12, 24 | 5, 7, 11, 13 |
| Housing block layout | 4 houses per block | 2, 4, 8, 12 | 3, 5, 7, 9 |
| Crop planting rows | Row spacing repeat | Any multiple of the repeat | Any k coprime with the repeat |
| Shift roster | 3 shifts | 3, 6, 9, 12 | 4, 5, 7, 8 |
| Unordered register | none | none | any k |
Table 8.3 Which variance estimator to report
| Situation | Estimator to use | Why |
|---|---|---|
| Frame order is random or meaningless | Simple random approximation | Systematic behaves like simple random, so the approximation is fair. |
| Frame carries a smooth trend | Successive differences | Uses neighbouring gaps, so it does not inflate the variance with the trend. |
| Frame may be periodic | Between starts, with m of at least 4 | The only estimator that captures periodic bias in its spread. |
| Sampling fraction above 5 percent | Any, with the finite population correction | Ignoring the correction gives intervals that are too wide. |
| Very small n, below 10 | Between starts, or report a range | Both single sample estimators are unstable at small n. |
Table 8.4 Design effect interpretation
| Design effect | Meaning | Badge | Action |
|---|---|---|---|
| Below 0.8 | Systematic clearly beat simple random | Gain | Keep the design and state the gain in your paper. |
| 0.8 to 1.2 | Roughly equivalent to simple random | Neutral | Keep the design for its field convenience. |
| 1.2 to 2.0 | Precision lost, neighbouring units resemble each other | Loss | Check the ordering and consider a different k. |
| Above 2.0 | Serious loss, periodicity or strong clustering likely | Investigate | Test for a cycle, or switch to stratified sampling. |
9Example Results (8 Worked Cards)
Example 1. Roadside vegetation transect, stems per plot
N = 500 plots, n = 50, k = 10, random start r = 7
Figure 9.1 Point estimate with its 95 percent confidence interval.
| Mean | SD | SE | MOE | 95% CI | Design effect verdict |
|---|---|---|---|---|---|
| 52.4 stems | 8.10 | 1.09 | 2.19 | 50.2 to 54.6 | Gain |
What it means: The successive differences SE (1.09) is smaller than the simple random SE (1.15), giving deff = 0.90. The even spread captured the roadside gradient.
How to write it: Plots were selected by systematic sampling (k = 10, random start r = 7, seed 20250607). Mean density was 52.4 stems (SE = 1.09 by successive differences, 95 percent CI 50.2 to 54.6, n = 50 of 500).
Example 2. Hospital patient register, waiting minutes
N = 1,500 visits, n = 100, k = 15, r = 4
Figure 9.2 Measured value for each sampled unit, drawn as vertical bars against the mean line.
| Mean | SD | SE | MOE | 95% CI | Design effect verdict |
|---|---|---|---|---|---|
| 37.6 minutes | 18.40 | 1.72 | 3.41 | 34.2 to 41.0 | Neutral |
What it means: deff = 0.98, essentially the same as simple random. The register order carried no useful trend, which is the common case for admission lists.
How to write it: Visits were selected systematically (k = 15, r = 4). Mean waiting time was 37.6 minutes (SE = 1.72, 95 percent CI 34.2 to 41.0, n = 100 of 1,500).
Example 3. Daily rainfall register sampled every 7 days
N = 364 days, n = 52, k = 7, r = 3
Figure 9.3 Group totals compared side by side as horizontal bars.
| Mean | SD | SE | MOE | 95% CI | Design effect verdict |
|---|---|---|---|---|---|
| 4.15 mm | 6.80 | 0.88 | 1.77 | 2.38 to 5.92 | Investigate |
What it means: deff = 2.4. The cycle length of 7 exactly matches k, so every sampled day is the same weekday. This estimate is biased and must not be reported as is.
How to write it: A systematic design with k = 7 was abandoned because the frame is periodic on a 7 day cycle; a random start within each week was used instead.
Example 4. Soil cores along a slope gradient
N = 240 cores, n = 24, k = 10, r = 6
Figure 9.4 Every sampled unit shown as one dot, with the mean marked.
| Mean | SD | SE | MOE | 95% CI | Design effect verdict |
|---|---|---|---|---|---|
| 1.42 percent carbon | 0.31 | 0.052 | 0.11 | 1.31 to 1.53 | Gain |
What it means: deff = 0.72. The slope produces a strong monotone trend, which is exactly the situation where systematic sampling outperforms simple random.
How to write it: Cores were taken systematically down the slope (k = 10, r = 6). Soil carbon averaged 1.42 percent (SE = 0.052 by successive differences, 95 percent CI 1.31 to 1.53).
Example 5. Household survey down a village register
N = 620 households, n = 62, k = 10, r = 2
Figure 9.5 Values plotted in frame order to reveal any trend across the population.
| Mean | SD | SE | MOE | 95% CI | Design effect verdict |
|---|---|---|---|---|---|
| 9,840 INR/month | 3,120 | 376 | 752 | 9,088 to 10,592 | Neutral |
What it means: deff = 1.04. Households are listed by street order, which correlates only weakly with income, so the two estimators agree closely.
How to write it: Households were selected systematically from the village register (k = 10, r = 2). Mean income was 9,840 INR (SE = 376, 95 percent CI 9,088 to 10,592, n = 62 of 620).
Example 6. Circular systematic when N is not a multiple of n
N = 437 units, n = 40, k = 11, circular, r = 293
Figure 9.6 Frequency distribution of the sampled values, with a smoothed outline.
| Mean | SD | SE | MOE | 95% CI | Design effect verdict |
|---|---|---|---|---|---|
| 18.60 units | 5.40 | 0.82 | 1.66 | 16.94 to 20.26 | Neutral |
What it means: Linear systematic would have returned 40 or 39 units depending on the start. Circular mode wrapped past the end of the frame and returned exactly 40 every time.
How to write it: Circular systematic sampling (Lahiri) was used with k = 11 and a random start of 293, returning exactly 40 units from a frame of 437.
Example 7. Replicated systematic with 4 random starts
N = 800 units, n = 40, k = 80, m = 4 starts
Figure 9.7 Share of the sample held by each part of the design.
| Mean | SD | SE | MOE | 95% CI | Design effect verdict |
|---|---|---|---|---|---|
| 26.30 units | 7.20 | 1.31 | 4.17 | 22.13 to 30.47 | Neutral |
What it means: The between starts estimator gives an unbiased SE of 1.31 on 3 degrees of freedom. The interval is wider than the single sample version, which is honest rather than worse.
How to write it: Four independent random starts were used (k = 80, 10 units per start). The mean was 26.30 (SE = 1.31 from the between starts estimator, 95 percent CI 22.13 to 30.47, df = 3).
Example 8. Awkward case: interval larger than the frame allows
N = 30 plots, n = 8, k = 4, r = 3
Figure 9.8 Spread, quartiles and median for each group as box and whisker plots.
| Mean | SD | SE | MOE | 95% CI | Design effect verdict |
|---|---|---|---|---|---|
| 14.50 units | 9.80 | 2.86 | 6.76 | 7.74 to 21.26 | Loss |
What it means: deff = 1.32 and the interval spans a threefold range. With N = 30 there are only 4 possible systematic samples, so the design has very little randomisation left in it.
How to write it: Eight plots were selected systematically (k = 4, r = 3). The estimate of 14.50 (95 percent CI 7.74 to 21.26) is reported as provisional given the small number of possible samples.
10How to Collect Raw Data in the Field
10a. The 18 point field protocol for systematic sampling
Plan
- Order the frame before anything else. Systematic sampling only works on an ordered list, so decide the ordering rule first: distance along a transect, row order in a register, chronological order of visits.
- Check the ordering for a repeating cycle. Weekday cycles, block layouts, shift rosters and planting rows are the usual offenders. Write down the cycle length before you choose k.
- Compute the interval k = N / n and pick a k that shares no factor with the cycle. If the cycle is 7 days, avoid k of 7, 14 or 21.
- Draw the random start before travelling and record it with the seed. Starting at unit 1 is the single most common way a systematic design is invalidated.
- Draw a reserve list of 20 percent extra units from the positions between your selected units, so replacements do not disturb the spacing pattern.
Figure 10.1 Even spacing is the practical advantage of systematic sampling over simple random sampling.
Kit
- Carry the printed Field Pack with the selected positions, the interval k and the random start written at the top.
- Carry a measuring wheel, tape or GPS so the interval is measured, not paced. Pacing drift is what turns a systematic design into an approximate one.
- Carry a counter or tally clicker for register work, so you do not lose your place when counting down every k-th row.
- Carry two pencils and a waterproof sheet cover. Ink runs in rain and a lost sheet is a lost field day.
Locate
- Start at the drawn start position r, not at the beginning of the line. Count or measure to r first, then begin the interval.
- Measure the interval from the previous selected unit, never cumulatively from memory. Small errors compound into a drifting sample.
- If a selected position is inaccessible, mark it Not found and take the nearest reserve unit, then return to the original spacing for the next selection. Do not shift the whole sequence.
Figure 10.2 A skipped unit must not shift the rest of the sequence; the interval stays fixed.
Collect
- Fill one datasheet row per selected unit, on the spot, and keep the rows in frame order because the successive differences estimator depends on that order.
- Record a true zero as 0, never as a blank. A blank means not measured; a zero means measured and none present.
- Record the position index as well as the unit ID. The frame position is what proves the interval was kept.
Figure 10.3 A completed row, including the frame position and a true zero.
Figure 10.4 Three records that must never be written the same way, especially in an ordered design.
Check
- Before leaving each unit, check the position number against the printed list. A one step slip early on shifts every later unit.
- At the end of the day, confirm the gaps between consecutive positions all equal k. Any gap that is not k should carry a written explanation.
- Photograph every sheet the same evening and enter the numbers within 48 hours, keeping the frame order intact.
Figure 10.5 The gap column is unique to systematic sampling and is what makes the design auditable.
10b. Datasheet column specification
| Column | Format | Example | Why it matters |
|---|---|---|---|
| Study area | Text, header once | Bhavani riverside transect | Links the sheet to the ordered frame. |
| Date | YYYY-MM-DD | 2026-08-08 | Unambiguous across countries. |
| Interval k | Integer, header once | 10 | The defining parameter of the design. |
| Random start r | Integer, header once | 7 | Proves the design was randomised. |
| Seed | Integer, header once | 20250607 | Lets anyone regenerate the same start. |
| Unit ID | Prefix plus number from the tool | U-0037 | Never renumber; ties the row to the draw. |
| Position in frame | Integer 1..N | 37 | The audit trail for the interval. |
| Gap from previous | Integer, should equal k | 10 | Instantly reveals a counting slip or drift. |
| Latitude, Longitude | Decimal degrees, 5 dp | 10.41207, 76.98811 | Allows a re-visit and a spatial check. |
| Status | Found / Not found / Replaced | Found | Separates non-response from a true zero. |
| Value | Number with unit in header | 0 | The measurement itself; 0 is a real value. |
| Observer | Initials | RP | Detects observer effects. |
| Start, End time | HH:MM 24 hour | 07:42, 08:05 | Effort correction and quality control. |
| Notes | Free text, short | True zero, bare ground | Explains anything a number cannot. |
Zero rule: write 0 for measured and none present; leave blank only when the unit was not measured at all. Order rule: never re-sort the rows, because the successive differences variance estimator reads them in sequence.
10c. Filled worked datasheet
| # | Unit ID | Position | Gap | Status | Value (stems) | Observer | Notes |
|---|---|---|---|---|---|---|---|
| 1 | U-0007 | 7 | start | Found | 48 | RP | Random start r = 7 |
| 2 | U-0017 | 17 | 10 | Found | 55 | RP | |
| 3 | U-0027 | 27 | 10 | Found | 0 | RP | True zero, bare rock patch |
| 4 | U-0037 | 37 | 10 | Not found | RP | Inside fenced private plot | |
| 5 | R-0039 | 39 | 2 | Replaced | 51 | RP | Nearest reserve used for U-0037 |
| 6 | U-0047 | 47 | 10 | Found | 61 | SK | Interval resumed from 37, not from 39 |
| 7 | U-0057 | 57 | 10 | Found | 47 | SK | |
| 8 | U-0067 | 67 | 10 | Found | 58 | SK | Uncertain, two stems may be one clump |
| 9 | U-0077 | 77 | 10 | Found | 44 | SK | |
| 10 | U-0087 | 87 | 10 | Found | 53 | SK |
What this sheet shows:
- Row 1 records the random start explicitly, which is the detail reviewers check first.
- The Gap column reads 10 all the way down, proving the interval was held.
- Row 3 is a true zero written as 0, so it still contributes to the mean.
- Rows 4 and 5 show a replacement taken from the nearest reserve, with the interval resumed from the original position 37, not from the replacement.
- Row 8 flags an uncertain count in the notes rather than silently rounding it.
10d. Blank print ready datasheet
Download the blank sheet as a .csv file, open it in Excel, Google Sheets or LibreOffice, then print it. The Position and Gap columns are pre-labelled so the interval can be audited in the field, and the rows stay readable after a black and white photocopy.
11Which Sampling Method Should You Use?
Decision tree. Answer these in order and stop at the first yes.
- Is your frame ordered in a meaningful way, with no repeating cycle, and do you want an easy field rule? Use systematic sampling.
- Does the frame contain a repeating cycle that matches your interval? Use simple random sampling, or systematic with a fresh random start inside every cycle.
- Is the frame unordered or randomly ordered, and is a complete list available? Use simple random sampling.
- Does the population split into subgroups that clearly differ? Use stratified random sampling, and consider systematic sampling inside each stratum.
- Is N not an exact multiple of n and you need exactly n units? Use circular systematic sampling.
- Do you also need a valid variance estimate from one field visit? Use replicated systematic sampling with 4 or more random starts.
- Is there no list, but the population comes in natural groups you can list? Use cluster sampling.
- Is the population hidden or hard to reach, with no frame at all? Use respondent driven or snowball sampling, and accept that it is non-probability.
| Method | Needs a frame? | Field cost | Bias risk | Precision per unit | Field difficulty |
|---|---|---|---|---|---|
| Systematic | Yes, ordered | Low | Low unless periodic | Equal or better than SRS | Easy |
| Circular systematic | Yes, ordered | Low | Low | Same as systematic | Easy |
| Replicated systematic | Yes, ordered | Low | Low | Slightly worse, but variance is estimable | Easy |
| Simple random | Yes, complete | High travel | Low | Baseline | Medium |
| Stratified | Yes, plus strata | Medium | Low | Better | Medium |
| Cluster | List of clusters only | Low | Medium | Worse, deff greater than 1 | Easy |
| Convenience | No | Very low | Very high | Not estimable | Very easy |
12Troubleshooting and Common Sampling Errors
My interval k is not a whole number
Cause: N is not an exact multiple of n. Fix: either round k and accept an achieved sample size one unit different from the target, or switch to circular systematic sampling, which always returns exactly n units.
I got 51 units when I asked for 50
Cause: normal behaviour of linear systematic sampling when N/n is not an integer and the random start is small. Fix: report the achieved n, not the target. It is not an error and does not need correcting.
The design effect came out above 2
Cause: strong similarity between neighbouring units, or periodicity in the frame. Fix: check whether any cycle length divides k. If it does, change k to a value coprime with the cycle, or use a fresh random start inside each cycle.
My team started at unit 1 instead of the random start
Cause: the printed pack was not consulted. Fix: this removes the randomisation, so the sample cannot support probability inference. Report it as a limitation, and print the start in large type at the top of the next Field Pack.
The gap column shows 9 and 11 instead of 10
Cause: pacing drift or a counting slip. Fix: small drift is tolerable if recorded, but note it in the methods. Use a measuring wheel rather than paces on the next round.
A selected unit was inaccessible
Cause: private land, water, hazard. Fix: mark it Not found, take the nearest reserve unit, and resume the interval from the original position, not from the replacement. Never shift the whole sequence.
The successive differences SE is much smaller than the simple random SE
Cause: the frame carries a smooth trend, which is exactly when systematic sampling gains precision. Fix: nothing is wrong. Report the successive differences interval and state the design effect as a genuine result.
The successive differences SE is much larger
Cause: neighbouring selected units differ sharply, often a sign of periodicity or a sawtooth pattern in the frame. Fix: investigate the ordering before reporting anything.
I cannot estimate the variance from one systematic sample
Cause: correct, there is only one random draw, so no unbiased estimator exists. Fix: use 4 or more random starts next time, and in the meantime report the successive differences estimate with a clear note that it is approximate.
My frame order was arbitrary, does systematic still work?
Cause: an alphabetical or ID-number ordering carries no information. Fix: the design is still valid and behaves like simple random sampling. Report the simple random approximation for the variance and say the ordering was arbitrary.
Uploaded CSV columns loaded with blank values
Cause: mixed text and numbers, or trailing empty rows. Fix: the tool skips non numeric cells automatically, but check the count shown on each group card matches what you expect.
13Assumptions, Bias and Limitations
- Ordered frame assumption. The design assumes the list order is fixed and meaningful before sampling. Re-sorting the frame after the draw invalidates the whole procedure.
- No periodicity assumption. This is the defining risk of systematic sampling. If the frame repeats on a cycle matching k, every unit lands on the same phase and the bias is unfixable by adding units.
- Random start requirement. Only the start is random. A fixed start turns the design into a deterministic selection with no basis for inference.
- Exact multiple assumption for unbiasedness. The linear systematic mean is strictly unbiased only when N is an exact multiple of n. Circular systematic sampling removes this restriction.
- Variance is not identified from one sample. All single sample variance estimates for systematic designs are approximations. Only replicated starts give an unbiased estimate.
- Trend sensitivity. A linear trend across the frame makes systematic sampling more precise than simple random; a sawtooth or cyclical pattern makes it much worse.
- Non-response bias. Replacing inaccessible units with neighbours slightly disturbs the equal spacing and can introduce local bias if inaccessibility is patterned.
- Measurement error. These formulas describe sampling variability only. A miscalibrated instrument shifts every value and no confidence interval will warn you.
14Conclusion
What systematic sampling gives you
Systematic sampling buys you two things that matter in real field work. First, it is dramatically easier to execute: one random number, then a fixed rule anybody on the team can follow without a map or a lookup table. Second, it spreads the sample evenly across the frame, so any smooth gradient from one end to the other is automatically represented. When the frame carries a trend, that even spread routinely produces a smaller standard error than simple random sampling for the same sample size, which is a genuine precision gain and worth stating explicitly in your paper.
What it costs you
The convenience is paid for in two places. The first is periodicity: if the ordered frame repeats on a cycle that matches your interval, every unit you select lands on the same phase and the estimate is biased in a way that more sampling cannot repair. The second is variance estimation: because only one random number is drawn, a single systematic sample gives no unbiased estimate of its own precision, and every standard error you compute from one sample is an approximation resting on an assumption about the ordering.
What to check before you publish
Confirm five things: the frame was ordered by a stated rule and archived in that order, the start was drawn at random and reported alongside the seed, the interval k shares no factor with any cycle in the frame, the achieved sample size is reported rather than the target, and the confidence interval names the variance estimator that produced it. Those five lines are the difference between a systematic design a reviewer accepts and one they send back.
What to do next
If precision matters more than convenience on the next round, run four random starts instead of one. You lose almost nothing in field effort, you keep the even spread, and you gain a properly unbiased variance estimate that makes the whole design defensible. If the design effect came out above 1.2, spend an hour examining the frame ordering before you collect another unit, because the ordering, not the sample size, is where the problem lives.
15Test Yourself
1. N = 800 and you want n = 40. What is the sampling interval k?
k = 800 / 40 = 20. You take every 20th unit after a random start between 1 and 20.
2. Why must the start be drawn between 1 and k, not 1 and N?
In linear systematic sampling a start above k would push the last selections past the end of the frame and shrink the sample. Only circular systematic sampling draws the start from 1 to N.
3. Your frame is a daily register and you choose k = 7. What goes wrong?
Every selected day is the same weekday, so a weekly cycle in the data is sampled at one fixed phase. The estimate is biased and no sample size fixes it.
4. N = 437 and n = 40. Which mode should you use and why?
Circular systematic, because 437 is not a multiple of 40. Linear systematic would return 39 or 40 units depending on the start; circular always returns exactly 40.
5. Your design effect is 0.75. Is that good or bad?
Good. A design effect below 1 means the systematic sample was more precise than a simple random sample of the same size, which happens when the frame carries a trend.
6. Why does one systematic sample give no unbiased variance estimate?
Because the entire sample follows from a single random number, so there is only one degree of randomisation. Estimating variability needs at least two independent random starts.
16Frequently Asked Questions
1. What is systematic sampling?
Systematic sampling selects every k-th unit from an ordered list after a random start between 1 and k, where k is N divided by n. Only the start is random; the rest of the sample follows from it automatically.
2. How do you calculate the sampling interval in systematic sampling?
Divide the population size N by the sample size n. If N is 500 and n is 50, then k is 10, so you take every 10th unit after a random start drawn between 1 and 10.
3. How do you do systematic sampling step by step?
Order the frame, compute k = N/n, draw a random start r between 1 and k, then select units r, r+k, r+2k and so on to the end of the list. Check the frame for a repeating cycle before you begin.
4. Why must the start be random in systematic sampling?
The random start is the only randomisation in the design. Starting at unit 1 by habit makes the selection deterministic, so there is no probability basis for a confidence interval.
5. What is periodicity in systematic sampling?
Periodicity is a repeating cycle in the ordered frame. If the cycle length matches or divides k, every selected unit falls on the same phase of the cycle and the estimate becomes badly biased.
6. What is circular systematic sampling?
Circular systematic sampling, due to Lahiri, draws the start from 1 to N and wraps positions around the end of the frame using modulo N. It always returns exactly n units even when N is not a multiple of n.
7. Is systematic sampling better than simple random sampling?
It is usually equal or better when the frame carries a smooth trend, because the even spread captures the gradient. It is worse when the frame is periodic, and it is much easier to run in the field either way.
8. Is systematic sampling a probability sampling method?
Yes, provided the start is drawn at random. Every unit has the same inclusion probability n/N. Without a random start it is not a probability sample at all.
9. What are the advantages of systematic sampling?
It needs only one random number, it is fast and simple in the field, it spreads units evenly across the frame, it works without a full list in advance, and it often gains precision when a trend is present.
10. What are the disadvantages of systematic sampling?
It is vulnerable to periodicity, it gives no unbiased variance estimate from a single sample, it needs an ordered frame, and the achieved sample size can differ from the target when N is not a multiple of n.
11. How do you estimate the variance of a systematic sample?
Use the successive differences estimator on an ordered frame, the simple random approximation when the ordering is arbitrary, or the between starts estimator when you used two or more independent random starts.
12. Why can a single systematic sample not give an unbiased variance?
Because the whole sample derives from one random number. Estimating variability requires at least two independent random draws, which is why replicated systematic sampling uses several starts.
13. What is replicated systematic sampling?
Replicated or interpenetrating systematic sampling splits the sample across m independent random starts, each with interval m times k. The spread of the m sub sample means gives an unbiased variance estimate.
14. What happens if N is not a multiple of n?
The interval k is not a whole number. Rounding it gives an achieved sample size one unit above or below the target. Circular systematic sampling avoids this and always returns exactly n.
15. What is the design effect in systematic sampling?
The design effect compares the systematic variance to the simple random variance. Below 1 means systematic gained precision; above 1 means it lost precision, usually because neighbouring units resemble each other.
16. When should you not use systematic sampling?
Avoid it when the frame has a repeating cycle you cannot break, when the ordering was created using the variable you are measuring, or when you need a strictly unbiased variance estimate from a single visit.
17. How do you handle an inaccessible unit in systematic sampling?
Mark it Not found, take the nearest reserve unit, then resume the interval from the original position rather than from the replacement. Shifting the whole sequence destroys the even spacing.
18. Can you use systematic sampling within strata?
Yes, and it is a common and strong combination. Stratify first on the factor that drives the variance, then run an independent systematic sample with its own random start inside each stratum.
19. How do you report systematic sampling in a research paper?
State the ordering rule, N, n and k, the random start and seed, whether the design was linear or circular, the achieved sample size, the periodicity check, and which variance estimator produced your confidence interval.
20. What is the difference between systematic and stratified sampling?
Systematic sampling uses a fixed interval on one ordered list. Stratified sampling divides the population into subgroups and samples within each. Stratified needs subgroup information; systematic only needs an order.
17Cite This Tool
18Related Tools
- Simple Random Sampling Calculator for a seeded, duplicate free random draw.
- Stratified Random Sampling Calculator for proportional, equal and Neyman allocation.
- Sample Size Calculator using Cochran, Yamane and Krejcie-Morgan.
19Glossary of Terms
| Term | Meaning |
|---|---|
| Achieved sample size | The number of units actually selected, which can differ from the target n in linear systematic sampling. |
| Circular systematic sampling | A variant that wraps around the end of the frame, always returning exactly n units. |
| Design effect | Ratio of the variance under the actual design to the variance under simple random sampling. |
| Effective sample size | n divided by the design effect; the equivalent simple random sample size. |
| Finite population correction | The factor √(1 − n/N) that shrinks the standard error when a large share of N is sampled. |
| Frame order | The fixed sequence of units in the list; part of the design in systematic sampling. |
| Inclusion probability | The chance a given unit enters the sample; equal to n/N under systematic sampling with a random start. |
| Interpenetrating samples | Independent sub samples from separate random starts, used to estimate variance. |
| Intraclass correlation | How similar neighbouring units are; drives the design effect. |
| Linear systematic sampling | The classic every k-th rule with a random start between 1 and k. |
| Margin of error | Half the width of a confidence interval, equal to the critical value times the standard error. |
| Periodicity | A repeating cycle in the frame that can align with the interval and bias the sample. |
| Random start | The single random number that determines the whole systematic sample. |
| Replicated systematic sampling | Using several independent random starts so the variance becomes estimable. |
| Reserve list | Extra units drawn in advance, used to replace inaccessible selections. |
| Sampling fraction | n divided by N, the share of the population measured. |
| Sampling interval k | N divided by n; the fixed spacing between selected units. |
| Seed | A number that fixes a pseudo-random sequence so the start can be reproduced exactly. |
| Successive differences estimator | A variance estimator built from the squared gaps between neighbouring selected units. |
| Standard error | Expected variability of the sample mean across repeated samples. |
20References
- Cochran, W. G. (1977). Sampling Techniques (3rd ed.), Chapter 8: Systematic Sampling. Wiley. Publisher page
- Madow, W. G., & Madow, L. H. (1944). On the theory of systematic sampling, I. Annals of Mathematical Statistics, 15(1), 1-24. https://doi.org/10.1214/aoms/1177731312
- Madow, W. G. (1949). On the theory of systematic sampling, II. Annals of Mathematical Statistics, 20(3), 333-354. https://doi.org/10.1214/aoms/1177729988
- Lahiri, D. B. (1951). A method of sample selection providing unbiased ratio estimates. Bulletin of the International Statistical Institute, 33(2), 133-140. WorldCat record
- Yates, F. (1948). Systematic sampling. Philosophical Transactions of the Royal Society A, 241(834), 345-377. https://doi.org/10.1098/rsta.1948.0023
- Gautschi, W. (1957). Some remarks on systematic sampling. Annals of Mathematical Statistics, 28(2), 385-394. https://doi.org/10.1214/aoms/1177706966
- Wolter, K. M. (1984). An investigation of some estimators of variance for systematic sampling. Journal of the American Statistical Association, 79(388), 781-790. https://doi.org/10.1080/01621459.1984.10477095
- Wolter, K. M. (2007). Introduction to Variance Estimation (2nd ed.). Springer. https://doi.org/10.1007/978-0-387-35099-8
- Bellhouse, D. R., & Rao, J. N. K. (1975). Systematic sampling in the presence of a trend. Biometrika, 62(3), 694-697. https://doi.org/10.1093/biomet/62.3.694
- Iachan, R. (1982). Systematic sampling: a critical review. International Statistical Review, 50(3), 293-303. https://doi.org/10.2307/1402496
- Murthy, M. N., & Rao, T. J. (1988). Systematic sampling with illustrative examples. In Handbook of Statistics, Vol. 6, 147-185. Elsevier. https://doi.org/10.1016/S0169-7161(88)06010-9
- Lohr, S. L. (2021). Sampling: Design and Analysis (3rd ed.). CRC Press. https://doi.org/10.1201/9780429298899
- Thompson, S. K. (2012). Sampling (3rd ed.). Wiley. https://doi.org/10.1002/9781118162934
- Sarndal, C. E., Swensson, B., & Wretman, J. (1992). Model Assisted Survey Sampling. Springer. https://doi.org/10.1007/978-1-4612-4378-6
- Kish, L. (1965). Survey Sampling. Wiley. Archive record
- Levy, P. S., & Lemeshow, S. (2008). Sampling of Populations: Methods and Applications (4th ed.). Wiley. https://doi.org/10.1002/9780470374597
- Elzinga, C. L., Salzer, D. W., & Willoughby, J. W. (1998). Measuring and Monitoring Plant Populations. BLM Technical Reference 1730-1. BLM library
- Gregoire, T. G., & Valentine, H. T. (2007). Sampling Strategies for Natural Resources and the Environment. Chapman and Hall. https://doi.org/10.1201/9780203498880
- Krebs, C. J. (1999). Ecological Methodology (2nd ed.). Benjamin Cummings. WorldCat record
- Marsaglia, G. (2003). Xorshift RNGs. Journal of Statistical Software, 8(14), 1-6. https://doi.org/10.18637/jss.v008.i14